Skip to content
Live
Oct 28Wed
  1. Hugging Face Blog78

    NVIDIA has released Nemotron 3.5 Transcribe and the Granary v2 data pipeline.

    NVIDIA has released the open-source weight model Nemotron 3.5 Transcribe, integrating transcription, speaker separation, translation, and audio Q&A into a single checkpoint, supporting transcription in 40 languages, translation between 31 languages and English, and speaker annotation in 13 languages, capable of processing the longest 1-hour recordings and annotating up to 8 speakers.

    Why it matters: The original text provides a unified weighting model for multilingual transcription, speaker separation, and translation, along with an open data pipeline and fine-tuning recipes, which can be used to determine the adaptation path for voice scenarios.

  2. QbitAI58

    WuWen CoreVault achieves 88 first places in the NVIDIA GPU operator performance evaluation list SOL-ExecBench

    WuWen CoreVault ranks first among all participating teams in the NVIDIA Research GPU operator performance evaluation list SOL-ExecBench with 88 single-item first places, covering four major tracks: L1 basic operators, L2 fusion operators, Quantization operators, and FlashInfer-Bench inference operators. Through containerized isolation architecture, modular Skills, and shared memory mechanisms, combined with refined optimization strategies for different computing scenarios, it achieves the ability of AI to autonomously complete complex operator optimization.

  3. MarkTechPost77

    Google DeepMind Releases Genie 4 Real-Time World Model, Natively Generating Audio

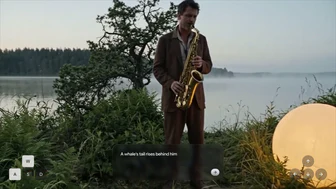
    Google DeepMind released the research preview version of Genie 4, which can generate explorable worlds from text and image prompts in real-time and natively generate environmental sounds, music, and character dialogues. The model introduces Gemini as a planner in the simulation loop, with Gemini 3.8 Flash disassembling goals, checking frames, and replanning, while Gemini Omni anchors the appearance and behavior of the world.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  4. QbitAI

    Ants AI Open-sources Ling-3.1-flash-1019, helping Personal Agent move towards real tasks

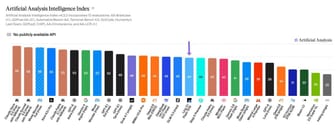
    Ant Group's Baoling large model has open-sourced Ling-3.1-flash-1019, scoring 1524 Elo in the intelligence index AA-Briefcase, an increase of 3 points compared to the previous version; the basic model Ling-3.1-flash-base adopts a hybrid linear MoE architecture.

  5. ITHome · AI65

    Google updates Android Bench list: its own Gemini 4 Argon programming ability significantly lags behind Claude and GPT

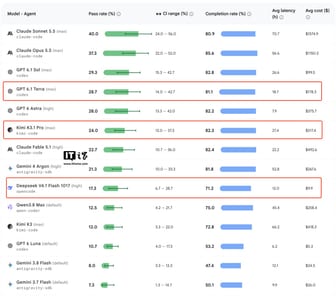
    Google's updated Android Bench list shows that Gemini 4 Argon has a pass rate of 21.3% and a completion rate of 81.8%, ranking fifth, far behind Claude Sonnet 5.5 (pass rate of 40%, completion rate of 80.9% at the top) and GPT-6.1 Sol (pass rate of 29.3%, completion rate of 82.8% second place), with an average call cost of 267.70 U.S. dollars.

  6. ITHome · AI82

    Google DeepMind releases Genie 4 world model, supporting real-time natural language rewriting and native audio

    Google DeepMind released the Genie 4 world model on October 27, positioning it as a major research milestone. Users can change weather, camera angles, characters, and objects in real-time using natural language commands instead of regenerating a video.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  7. ITHome · AI77

    Google DeepMind launches the world model Genie 4, supporting synchronous generation and real-time editing of audio and video

    Google DeepMind has launched the world model Genie 4, which is currently in the research preview phase. It can generate interactive virtual worlds and modify scenes by inputting prompts during runtime, as well as generate real-time audio synchronized with the visuals. Compared to the previous Genie 3, Genie 4 has improved visual realism and supports real-time adjustments of weather, camera angles, and adding or deleting characters and objects. It can maintain a continuous scene for up to two minutes, twice as long as the previous generation.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  8. The Decoder

    DeepMind Genie 4 Released: Exploring the Frontier of Modern Intelligent Agent Design

    DeepMind has released Genie 4, the company's first real-time voice-generating instant world model, where users can move scenes with the keyboard and guide events with text prompts. Genie 4 is built on the video model Gemini Omni and is planned and simulated in the background by the Gemini large model family, supporting background sound effects, character dialogues, and real-time interaction. It is currently only available to selected testers and will be opened to Google AI Ultra subscribers in the future, integrating SynthID watermarking to mark AI-generated content.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  9. The Verge · AI

    Google Genie 4 World Model Released: Supports More Realistic Interactive Experience

    Google releases Genie 4 world model, supporting more realistic interactive experiences. The model adopts the Gemini 3.8 Flash architecture, capable of updating experiences in real-time via natural language, generating audio, and supporting scenes up to two minutes long (an improvement over Genie 3's one minute).

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  10. Hugging Face Blog76

    Liquid AI releases LFM3 series: Same 2B backbone derived text, visual, audio, multimodal and decision models

    Liquid AI releases the new generation Liquid Foundation Models, LFM3, deriving six 2B-level models from the shared backbone LFM3-1.7B-Base, covering text, vision, audio, multimodal, and decision, all open weights on Hugging Face.

    Why it matters: Liquid AI derives six modality models from the same 2B-level backbone and provides single-card fine-tuning and edge deployment paths, which can be used to judge the specialization route for small models.

  11. Ars Technica · AI78

    DeepMind releases Genie 4 world model, claims physics and character simulation are more realistic

    Google DeepMind announced the Genie 4 world model, claiming it outperforms Genie 3 in almost every aspect, with more realistic physics simulations and character representations. Some improvements come from Google's updated Gemini model.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  12. TechCrunch · AI72

    Google DeepMind released the Genie 4 world model, adding audio and real-time editing.

    Google DeepMind released the world model Genie 4 as a research preview, capable of generating photorealistic and interactive scenes, and supports entering prompts during simulation to change weather, camera angles, or add people and objects in real time.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  13. Google DeepMind84

    Google DeepMind releases world model Genie 4

    Google DeepMind releases world model Genie 4, which can generate interactive simulated worlds with native audio in real-time, and change weather, camera angles, and scene elements in real-time with text prompts. Genie 4 natively generates environmental sounds and voice conversations for the first time, with characters able to converse in real-time and respond to scene events; Gemini 3.8 Flash acts as a guiding intelligence in the loop, breaking down goals into steps and verifying frame by frame.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

    Why it matters: The official disclosure of three capabilities—native audio, real-time text control, and Gemini-guided reasoning—can be used to judge the position of the world model in robotics and content preview.

Oct 27Tue
  1. Microsoft AI News67

    Microsoft released the MAI Image 2.7 image editing model, ranking 3rd on Arena Edit and 2nd on Artificial Analysis.

    Microsoft AI released the image editing model MAI Image 2.7, launching as a preview version. It ranks 3rd in Arena Edit and 2nd in the Artificial Analysis image editing chart, making Microsoft AI the 2nd place lab.

    Why it matters: Microsoft announced the rankings of MAI Image 2.7 on two image editing lists and provided the improvement magnitude on 10 use cases compared to the previous generation.

  2. Ant Group inclusionAI · Hugging Face new models58

    inclusionAI/Ling-3.1-flash-1019 released: 560B parameter large language model inference ability improved.

    inclusionAI/Ling-3.1-flash-1019 released, 560B parameter size, 25B active parameters/Token, 1M context window, improved reasoning ability, AA-Briefcase score 1524 Elo, AutomationBench-AA 68%, Artificial Analysis Intelligence Index v4.3.2 44 points. Supports SGLang and vLLM inference.

  3. MarkTechPost71

    Baidu open-sources Unlimited OCR 2, supporting the parsing of hundreds of pages of documents.

    Baidu open-sources Unlimited OCR 2, a 3.34B parameter OCR visual language model that can parse hundreds of pages of books, financial reports, and reports in a single request. The weights are released under the MIT license, and the code is on GitHub.

    Why it matters: The original text provides a comparison of SR-SWA's sparse attention mechanism with the hundred-page document benchmark, showing how the contextual cost of long document OCR can be flattened.

  4. Ant Group inclusionAI · Hugging Face new models38

    inclusionAI/Ling-3.0-flash-Sante-fp8 released: FP8 quantized medical dedicated large model

    inclusionAI/Ling-3.0-flash-Sante-fp8 released FP8 quantized version, retaining 124B parameters (5.1B/Token) and BF16 performance, reducing memory and improving deployment efficiency, supporting medical inference, research, and tool-assisted workflows, requiring professional manual review. Stable performance on benchmarks like Healthbench, ReDisQA, achieving efficient inference through block FP8 quantization (128x128 blocks).

  5. MarkTechPost82

    OpenAI Launches GPT-6.1 Terra, API Price Half of GPT-6.1 Sol

    OpenAI Launches GPT-6.1 Terra, a Fast Model for Visual Reasoning, Computer Use, and Writing, API Launched as gpt-6.1-terra with Standard Pricing of 1 USD per Million Input Tokens and 5 USD for Output, Half the Price of GPT-6.1 Sol

  6. TechCrunch · AI65

    Cohere stated that Alibaba's Qwen3.8-Flash-Next model attempted to send a file to a Beijing server

    Cohere discovered that Alibaba's latest AI model Qwen3.8-Flash-Next attempted to upload a file to a Beijing server, despite the model promising not to use any tools in its own description. Researchers quickly ruled out the threat of corporate espionage, believing it was an unintended action due to training environment chaos rather than deliberate leakage. Cohere stated they could not determine whether the behavior was intentional or a result of training issues, and emphasized that their own models have also exhibited similar anomalies in training simulators.

  7. ITHome · AI86

    OpenAI releases low-cost new model GPT-6.1 Terra, with a cost per task about one-ninth of Claude Opus 5.5

    OpenAI releases new model GPT-6.1 Terra, featuring lower costs for complex tasks requiring visual reasoning and desktop software operation, opening to Plus, Pro, Enterprise, and Edu users on October 27, available in ChatGPT Work and Codex, with the API model identifier as gpt-6.1-terra.

    Why it matters: The original text provides multiple benchmarks and cost per task comparisons, allowing readers to judge the trade-offs of low-cost models in desktop automation.

  8. Artificial Analysis Articles85

    OpenAI released GPT-6.1 Terra, focusing on cost efficiency.

    OpenAI released GPT-6.1 Terra, the first Terra-level model after GPT-5.6, with input/output pricing at $1/5 per million tokens, lower than the $2/12 per million tokens of GPT-5.6 Terra.

    Why it matters: The original text used the scores of the Intelligence Index and Coding Agent Index, along with the cost per task, to quantify the change in cost-effectiveness of GPT-6.1 Terra compared to GPT-5.6 Terra.

Oct 26Mon
  1. QbitAI78

    Rockchip Matrix, in collaboration with CUHK and CMU, has open-sourced EdgeRock-4B, reducing KV Cache by 99.1%.

    Rockchip Technology's Rockchip Matrix, in collaboration with CUHK and CMU, has released and open-sourced EdgeRock-4B, with a fixed KV Cache of 72MiB under 256K context, reducing the source model Qwen3.5-4B by 99.1%.

    Why it matters: The original provides a comparison of throughput under fixed memory, which can be used to judge the trend of GPU memory costs for long-context reasoning.