Skip to content
Live
Nov 14Sat
  1. The Decoder65

    Runway open-sources robot control model Praxis-1

    Runway has released the open-source robot control model Praxis-1, which learns to control robots through video and has shown excellent performance in its own tests, scoring 46.2% on the Nvidia RoboLab-120 evaluation, leading similar models. The model requires additional training to adapt to new robot systems, the standard version requires an 80GB memory GPU, and it has been made available on Hugging Face.

  2. MarkTechPost

    Best AI video generation models in 2026: Elo ranking, per-second price, and open-source weight analysis

    The Elo ranking shows Alibaba Wan 3.0 (1175 T2V Elo) at the top with a price of $0.20 per second; Utopai X (1170 T2V Elo) is second but has no API; MiniMax H3 (1161 T2V Elo) is the first open-source video model with a price of $0.08 per second, but it is regionally restricted. The ranking is based on blind human preference tests, combined with the price per second of the API and the status of weighted licenses.

Nov 13Fri
  1. Hugging Face Daily Papers65

    PhysLoop: Utilizing the physical perception capabilities of large language models to achieve self-improvement of video generation models

    PhysLoop utilizes large language models to guide video generation, selection, and correction, achieving physically consistent self-improvement and controllable data construction. The framework drives recursive self-improvement (RSI) of video generation models with limited human intervention by identifying and correcting physical errors in generated videos, and releases a diverse dataset containing 100K videos along with generation tools.

  2. Hugging Face Daily Papers

    BirdDreams: Joint Perspective and BEV Video Generation for Reasonable, Reactive Driving World Models

    BirdDreams jointly generates bird's-eye view (BEV) videos and bird's-eye view videos, making scene layout a part of predicting the future. By providing an overhead view of vehicle position and movement through BEV, it reduces occlusion, while the perspective video retains scene details. On PhysicalAI-AV and nuScenes, BirdDreams more faithfully follows the input trajectory of its own vehicle and generates more reasonable self-motion without HD map or vehicle state input.

  3. The Decoder

    Anthropic launches Claude Meetings feature to let AI participate in video conferences

    Anthropic has released the Claude Meetings feature, allowing Claude to join video conferences as a visible participant, answer questions, generate documents and whiteboards, take notes and action items, and respond in text format by default. With authorization, it can access connected tools. After the meeting, all notes, text records, and documents are uploaded to the dedicated claude.ai page. Privacy controls default to preventing Claude from joining meetings with external participants.

Nov 12Thu
Nov 11Wed
  1. ITHome · AI

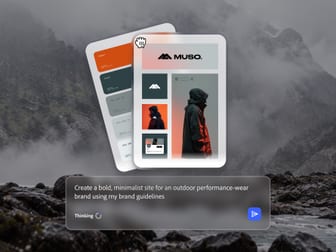
    Adobe announces four AI experimental projects: transforming photos into 3D scenes in seconds, and designing AI characters through chat.

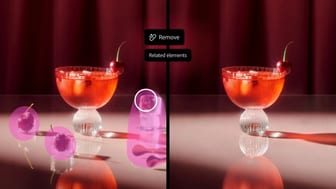
    Adobe announced four AI experimental projects: Project Screen Test designs AI characters through dialogue; Project Sight Span converts photos into explorable 3D scenes; Project Sound Bender allows free adjustment of video sound effects; Project Rinse Repeat automatically replicates editing operations.

  2. The Verge · AI

    Adobe experimental AI tool: makes photos explorable, AI characters can converse, editing like copy and paste

    Adobe has launched experimental AI tools Project Screen Test to design AI characters through dialogue and generate audition animations; Project Sight Span converts photos into explorable 3D environments; Project Sound Bender allows users to customize sound effects like a color wheel; Project Rinse Repeat can replicate edits and apply them automatically to other objects in the same image

  3. Ars Technica · AI65

    Amazon releases AI-powered Ring drone and robot

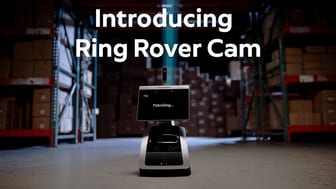
    Amazon introduces Ring Flight drone and Ring Rover Cam robot, offering 2K video features with 148-degree field of view and 360-degree rotation, respectively. The drone has a flight time of 8 minutes, and the robot is priced at $1000, supporting 4K recording and cloud storage for 180 days. Both are controlled via Alexa Home Map, but the drone's performance decreases on reflective surfaces, and the robot is limited to single-story indoor use.

Nov 10Tue
Nov 9Mon
  1. ITHome · AI65

    Microsoft files AI patent: Real-time live stream voice modification and lip synchronization

    Microsoft filed a patent application, using AI to almost instantly modify live broadcast content and synchronize mouth movements, capable of replacing verbal fillers, stuttering, offensive words, etc., supporting real-time translation, with a delay of 1 to 10 seconds, potential application scenarios include lectures, sports event broadcasts, etc., currently only a patent application, the technology has not yet been authorized.

Nov 7Sat
Nov 6Fri
  1. QbitAI

    Dream Short Drama Studio: script storyboard preview all-in-one, partner program provides long-term support

    Dream Short Drama Studio provides a complete creative process from script to storyboard, supporting one-sentence inspiration or existing script creation, generating a 10-episode outline and the first three episodes of the script with clear annotations of character actions and expressions. Seedance 2.5 offers low costs as low as 0.15 yuan per second, supports smart preview and 3D scene verification, and the institutional partner program provides IP connection and publicity support, with annual packages for individuals as low as a 4.5 discount.

  2. QbitAI

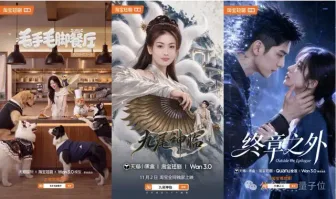
    Wan3.0 supports Taobao's AI branded short dramas in an effort to boost performance during the Double 11 sales event.

    Alibaba's new video generation model Wan3.0, through consistency, realistic texture, style mastery, and video editing capabilities, achieved stable reproduction of character, product, and spatial relationships in Taobao short dramas 'Nine-Tailed God's Arrival,' 'Clumsy Hands Clumsy Feet Restaurant,' and 'Beyond the Final Chapter,' assisting in brand integration and promoting transaction conversion, demonstrating the commercial value of AI video models in the e-commerce field.

  3. 36Kr · AI84

    Google has launched a video generation model, Gemini Omni 1.2 Flash, with a 30% price reduction

    Google launched the video generation model Gemini Omni 1.2 Flash on November 5 local time, and fully opened it in Gemini API and Gemini for Business. The model introduces native 15-second video creation, multi-round conversational editing, and enhanced reference following capabilities, with a 30% price reduction compared to Gemini Omni 1.1, priced at $0.07 per second in 720p resolution.

  4. ITHome · AI94

    Google has released the Gemini Omni 1.2 Flash video generation model, with a native duration of 15 seconds and a 30% price reduction compared to 1.1.

    Google has launched the Gemini Omni 1.2 Flash video generation model and made it available on the Gemini API and the Gemini for business platform. The new native version supports videos up to 15 seconds long, with customizable durations from 3 to 15 seconds in 1-second intervals. The 720p generation price is $0.07 per second, a 30% reduction compared to the 1.1 version.

  5. TechCrunch · AI65

    Meta launches the Muse AI model video chat feature.

    Meta announces that its consumer AI agent Muse's voice and video chat features Muse Realtime Avatar and Muse Realtime Voice are now available to all users in the United States. Users can engage in real-time conversations by interacting with the cute animated avatar Jolly, which can be customized according to user preferences and uses subtle expressions and gestures that match the mood of the conversation.

  6. Hugging Face Blog71

    NVIDIA has released four open-source world model checkpoints for Cosmos 3.

    NVIDIA has added four new open-source weight checkpoints for Cosmos 3 under the Cosmos World Model platform, all of which are post-trained versions of Cosmos 3 Nano, containing 16B trainable parameters, using the OpenMDW1.1 license, allowing commercial and non-commercial use.

    Why it matters: The original text provides four open-source weight checkpoints and a four-stage training recipe, allowing readers to judge how to adapt the world model to their own sensors and robot bodies.

  7. The Decoder92

    Google has released the Gemini Omni 1.2 Flash video generation model, extending duration to 15 seconds and reducing the price by 30%.

    Google DeepMind has made the Gemini Omni 1.2 Flash video generation model generally available, extending clip duration from a maximum of 10 seconds to 3 to 15 seconds, and reducing the price of 720p video to 0.07 USD per second, a 30% decrease from the previous generation.

  8. Google AI Blog78

    Google releases Gemini Omni 1.2 Flash, supports 15-second videos and cuts prices by 30%

    Google has released Gemini Omni 1.2 Flash and has officially opened it through the Gemini API and Gemini for business. The duration of native video generation has increased from 10 seconds in Omni 1.1 to 15 seconds, with a step length of 1 second specified from 3 to 15 seconds. The price of 720p has been reduced to 0.07 US dollars per second, a decrease of 30% from 1.1.

  9. Google DeepMind78

    Google DeepMind has released Gemini Omni 1.2 Flash, supporting 15-second videos and reducing the price by 30%.

    Google DeepMind has released Gemini Omni 1.2 Flash, increasing the native video generation duration from 10 seconds in Omni 1.1 to 15 seconds, and it has been fully opened in the Gemini API and Gemini for business.

    Why it matters: The original text lists specific changes in duration, price, and reference consistency, allowing readers to judge how the cost and workflow of video generation will change.

Nov 5Thu
  1. Hugging Face Daily Papers65

    EmoReward: A self-evolving reward calibration mechanism for emotional video generation

    EmoReward adapts multi-reward weight allocation by extracting evidence reliability from reward trajectories collected during actual training runs to calibrate reward weights for emotional video generation. This mechanism first evaluates specific grounding cues based on emotional prompts, then scores videos during the generation phase using heterogeneous signal primitives, and calibrates their contributions through reflective reward gating.

  2. Hugging Face Daily Papers65

    The TurnWise framework enhances streaming video understanding through round-level credit assignment.

    The TurnWise framework improves streaming video understanding by round-level credit assignment and decision weight balancing. Its round-level credit assignment constructs group relative advantages using prefix scores from silent completions, and round-mean policy optimizes the token loss per round. Experiments show this method outperforms existing streaming video understanding RL methods.

Nov 4Wed
  1. ITHome · AI58

    Xiaomi WorldCast 3D Camera Movement Launched on REDMI K100: Flat Photos Restored into 3D Scenes, and Real Camera Path Virtualized

    Xiaomi REDMI K100 Phone Adds 3D Camera Movement AI Feature, Select Static Photos from Album to Generate Wide-Angle 3D Camera Movement Videos, Lens Can Orbit, Pull, Tilt, and Keep Character Appearance Consistent. This Feature is Based on Xiaomi's Visual Generation Framework WorldCast, Interpreting Depth Structure of the Scene to Restore Flat Photos into 3D Scenes and Virtual Camera Path. Xiaomi Claims WorldCast is a Breakthrough in Controllable Visual Generation Direction, Will Explore More Complex Camera Movement Forms and 4D Video Generation Technology.

  2. QbitAI58

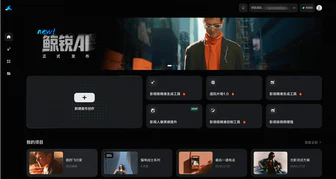
    Orca Culture's 'Jingrui AI' platform officially launched, saving more than 30% in AI video costs per minute

    Orca Culture Group's 'Jingrui AI', the industry's first AI film production and management platform, officially launched, integrating over 50 mainstream AI video generation models and over 10 self-developed models, saving more than 30% in AI video costs per minute compared to traditional methods through precise control and process optimization. The platform's official website (www.jingruiai.cn) opens for full registration, team seats unlimited in number, no membership subscription required.

  3. Hugging Face Daily Papers65

    MoviEdit: A framework for editing long-segment, multi-shot video

    MoviEdit framework, through cascaded bidirectional autoregressive modeling and new benchmark tests, maintains cross-scene coherence while reducing manual data annotation, significantly outperforming existing open-source models with performance comparable to industry leading models. The framework automatically generates 87K pairs of paired editing videos for cross-shot supervision, establishes a global editing draft using a lightweight bidirectional stage, and then performs autoregressive propagation and refinement.