Skip to content
Live
Nov 14Sat
  1. QbitAI80

    DeepSeek has opened the entire suite of application APIs, with voice interfaces included for the first time.

    DeepSeek has officially opened the entire suite of application APIs, including online search, deep thinking search, file upload, and link reading features within the app, all providing independent interfaces that can be called separately and billed individually. Voice capabilities have been included in the open list for the first time, including ASR and TTS interfaces. The original price for speech recognition is 0.78 yuan per hour, now half off at 0.39 yuan per hour, and speech synthesis is 1.5 yuan per 10,000 characters.
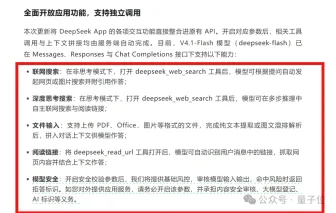
    Why it matters: The original text lists the tool interfaces opened by DeepSeek and the half-price voice pricing, allowing readers to estimate the call costs for voice assistant and document processing applications.

  2. ITHome · AI

    CDPR has used Respeecher AI technology to restore the early Polish voice line of Geralt in 'The Witcher 3'.

    CDPR has adopted Respeecher AI technology to provide Polish voice acting for the new DLC of 'The Witcher 3: Wild Hunt', adjusting the hoarse voice of Jacek Rozenek after a stroke to an early effect. Rozenek personally recorded new lines, and Respeecher used its early voice model for conversion, focusing on restoring his emotional expression. CDPR stated that they may no longer use this method in the future, and that Rozenek's current voice may be suitable for shaping an older Geralt.

Nov 13Fri
  1. TechCrunch · AI65

    ElevenLabs has released the ElevenAI app: integrating meeting notes and speech-to-text functionality.

    ElevenLabs has released the experimental application ElevenAI, integrating meeting notes, speech-to-text, and agent functionalities, supporting cross-meeting data queries and real-time assistance, aimed at being a team collaboration tool rather than a personal productivity tool. The application supports speech-to-text for over 90 languages, can understand industry terminology, and allows enterprises to integrate ElevenAgent to perform subsequent actions such as drafting emails based on meeting notes.

  2. ITHome · AI

    DeepSeek releases the full suite application API

    DeepSeek has opened up the application API, allowing developers to call deep thinking search, file input, and other dialogue functions through parameters. Voice and related underlying capabilities are also opened as independent interfaces, supporting separate or combined calls to achieve 1:1 replication of the DeepSeek App. The V4.1-Flash model (deepseek-flash) supports online search, deep thinking search, file input, reading links, and other capabilities, and charges fees for related tool calls.

  3. ITHome · AI

    Tencent Mixuan has released the real-time speech model Hy Realtime: it can speak, sing, and also call tools, and has been launched on Yuanbao voice calls, Tencent Customer Service, and other platforms.

    Tencent Mixuan has released the real-time speech model Hy Realtime, which has excellent performance in basic conversational abilities such as speech understanding, command following, and anthropomorphic expression, while also adding new Agentic tool calls and singing capabilities. Hy Realtime has already been launched in Yuanbao voice calls, Tencent Customer Service, and other products, and will also be launched on Tencent Cloud in the near future, providing API services to the public.

  4. MarkTechPost

    Liquid AI releases LiquidCodec, a 74M parameter streaming audio codec

    Liquid AI has released the LiquidCodec audio codec, supporting 24 kHz audio, converting speech to tokens predictable by language models, and then converting back to audio, with approximately 74M parameters.

    Same story · 2 outlets

    How the accounts differ:Liquid AI Blog mentions a compression rate of 1.1 kbps and speed improvements of 3.5x and 8x, while MarkTechPost does not mention these figures.

Nov 12Thu
  1. ITHome · AI

    Apple CarPlay integrates Google Gemini: Now you can chat with AI naturally in the car.

    Google is gradually rolling out the CarPlay integration feature to iOS users worldwide, covering all languages supported by Gemini Live. Users with devices like iPhone 18 Pro can use Gemini's voice mode for hands-free conversations on the CarPlay in-car screen, with chat history synced to the iPhone app. Users can connect to apps like Gmail and Google Calendar to get daily briefs or ask for destination information, practice speeches, etc., with conversations automatically synced to the phone.

Nov 11Wed
  1. ITHome · AI

    DeepL launches its voice AI translation model Aure, reproducing speaker's tone and emotion in real-time

    DeepL has launched the voice AI translation model Aure, which reproduces the speaker's tone and emotions in real-time. Aure is based on DeepL's voice preservation technology and can dynamically adapt the translated voice, capturing the fluctuations in tone, emotional shifts, emphasis, and changes in speech rate throughout the process, supporting eight languages including English and German.

  2. The Decoder

    The DeepL Aure model achieves real-time translation that conveys tone and emotion.

    The DeepL Aure model conveys the speaker's tone, emotion, and pace to the target language by analyzing the original audio and translated text, supporting eight languages including English, German, and Spanish, and is suitable for DeepL Voice online meetings, face-to-face conversations, and the DeepL API.

  3. ITHome · AI

    OpenAI will discontinue the old voice mode of ChatGPT on December 11 and fully switch to GPT-Live

    OpenAI will discontinue the ChatGPT Advanced Voice Mode and Standard Voice Mode on December 11 and fully switch to GPT-Live. Since its release in July, GPT-Live usage has nearly doubled, but some users are dissatisfied with its issues of interrupting conversations and losing context. The old versions will start receiving discontinuation notices on November 10 and will be officially removed on December 11, with users automatically switching to GPT-Live beforehand.

  4. Latent Space65

    OpenAI discussed new ways of working for Codex at the AI Engineers Code Summit.

    OpenAI introduced new ways of working for Codex at the AI Engineers' Code Summit, including improvements to cloud functions, voice interaction, and agent collaboration. Codex Cloud 2.0 allows users to run multiple tasks in isolated instances, but there are still usability issues with cloud functions. The voice mode, as a control plane, can manage code repositories, and personal agents dots can serve as safety nets, delegation nodes, and ubiquitous presences.

  5. MarkTechPost

    Zyphra has released ZONOS3-Mini: an 800M parameter open-source speech synthesis model.

    Zyphra has released ZONOS3-Mini, an open-source speech synthesis model with 800M total parameters and 100M active parameters, supporting real-time local deployment and zero-shot voice cloning. The model ranks first in the open model category in Zyphra's self-developed ZTTS2-Eval benchmark test (66.2 points), with the first audio generation on a single H100 GPU taking 80 milliseconds, but the reference audio cloning effect is far lower than the embedded mode.

Nov 10Tue
  1. TechCrunch · AI

    Otter AI expands support to transcribe meetings in over 30 languages.

    Otter AI has launched a cross-language meeting transcription feature supporting over 30 languages, which can automatically detect and switch languages during the same meeting. New support for 27 languages has been added, bringing the total number of supported languages to 31. Currently, 13 new languages are available, and the remaining 14 will be launched soon, aiming to help global teams overcome language barriers.

  2. Hugging Face Daily Papers

    Confucius4-R2T2: A stable prefix streaming speech recognition model for real-time transcription

    Confucius4-R2T2 is a stable prefix streaming speech recognition model for real-time applications, which converts a full context ASR model into a streaming model through post-training without architecture modification. Built based on Qwen3-ASR-1.7B, R2T2 achieves near-offline recognition accuracy and low transmission delay, supports configurable streaming block sizes, and demonstrates promising cross-lingual generalization capabilities. This model and implementation have been publicly released.

Nov 9Mon
  1. ITHome · AI55

    Apple iOS 27.3 code exposed Siri's 'Personal Memory System'

    Apple iOS 27.3 code reveals the development of a personal memory system, including a 'memory graph' component for organizing users' social relationships, frequently visited places, daily habits, and other information. The system designs 'memory atoms' as data units to record facts, opinions, and other details, associating specific information. It collects data through two mechanisms, but currently, only one AI-driven mechanism appears in the code. The system uses Apple's version of the Kuzu graph database but is not yet complete and no launch date has been revealed.

  2. ITHome · AI65

    Microsoft files AI patent: Real-time live stream voice modification and lip synchronization

    Microsoft filed a patent application, using AI to almost instantly modify live broadcast content and synchronize mouth movements, capable of replacing verbal fillers, stuttering, offensive words, etc., supporting real-time translation, with a delay of 1 to 10 seconds, potential application scenarios include lectures, sports event broadcasts, etc., currently only a patent application, the technology has not yet been authorized.

Nov 7Sat
  1. ITHome · AI60

    Cursor launches real-time voice chat functionality, ushering AI programming into the 'call era'

    Cursor launches the 'Real-time Voice Chat with Agents' feature, supporting developers in two-way voice conversations with coding agents to describe code modification requirements, inquire about task progress, etc., while the agents complete coding work in the background. This feature is used in Cursor's Agents Window, IDE, web version, and iOS app, driven by Grok Voice for speech recognition and synthesis, offering multiple voice options like Ara, Eve, and supporting switching during calls.

  2. Cursor Changelog60

    Cursor online with real-time voice calls to agents

    Cursor launches Voice Chat, allowing users to have real-time voice calls with agents, dictate modification requests, ask what the agent is doing, and receive progress updates.

    Why it matters: Officially, it explains which platforms the voice call is available on and how to divide tasks with coding agents, allowing readers to judge which collaboration scenarios it suits.

Nov 6Fri
  1. The Verge · AI65

    Amazon will allow users to send shopping lists to Alexa via SMS

    Amazon adds new features for Alexa Shopping, allowing users to describe or upload photos via SMS for AI to search for Amazon products and place orders on their behalf. This feature is based on Alexa for Shopping launched in May, providing shopping services in more convenient SMS scenarios, supporting ordering groceries, getting gift suggestions, finding similar products, etc. The feature has now been rolled out to some users in the US and will expand to millions of users in the coming weeks.

  2. Hugging Face Blog

    Hugging Face Open ASR Leaderboard adds Egyptian and Nigerian English datasets

    Hugging Face Open ASR leaderboard adds Liva AI private datasets for Egyptian English and Nigerian English, containing 1.34 hours and 1.55 hours of dialogue speech, to enhance the representativeness and reliability of ASR evaluation. The leaderboard now supports more detailed accent classification based on the Kachru three-circle model, covering groups such as US and non-US, inner circle and outer circle/extended circle.

  3. ITHome · AI72

    Meta launches real-time voice chat and virtual avatar features for AI assistant Muse

    Meta announces the launch of real-time voice chat and virtual avatar features for its personal AI assistant Muse, rolling out first to users in the United States, covering mobile, web, and Mac apps. The feature is supported by two models, Muse Realtime Voice and Muse Realtime Avatar, capable of streaming vertical videos at a resolution of 448×768 and 25 frames per second. The delay from the user finishing speaking to receiving the first audiovisual response is approximately 870 milliseconds.

    Why it matters: The original text provides the latency, resolution, and interaction methods for real-time voice and virtual avatars, allowing readers to judge the maturity of such face-to-face intelligent agent interactions.