NVIDIA Technical Blog6565
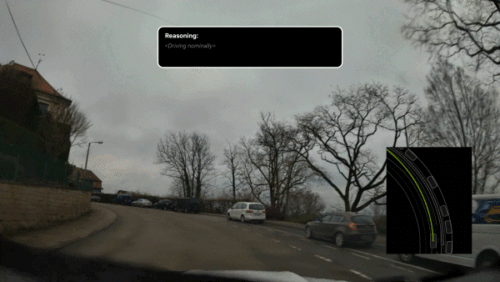
NVIDIA Alpamayo 2 Edge edge inference model runs within automotive computing and latency constraints
The NVIDIA Alpamayo 2 Edge edge inference model can run within automotive computing and latency constraints. The model achieves 70.5 on the MMLU benchmark, supports an 8k context window, speeds up 3.5x, and costs $3/ million tokens with closed-source deployment.