Skip to content
Live
Oct 31Sat
  1. The Verge · AI65

    Google's Project Suncatcher satellite successfully sent its first AI response from space.

    Google's Project Suncatcher satellite successfully launched its on-board Tensor Processing Units (TPUs), enabling the on-board Gemma 4 model to create haikus about space based on prompts.

    Same story · 2 outlets

    How the accounts differ:TechCrunch states the satellite creates poetry; The Verge specifies haiku about space.

  2. TechCrunch · AI60

    Google's first data center satellite has been launched and has created poems.

    Google Suncatcher satellite, carrying four Tensor Processing Units (TPUs), has been launched by SpaceX and is now operational, successfully sending prompts to Google DeepMind's Gemma 4 large language model to create poems.

    Same story · 2 outlets

    How the accounts differ:TechCrunch states the satellite creates poetry; The Verge specifies haiku about space.

  3. QbitAI78

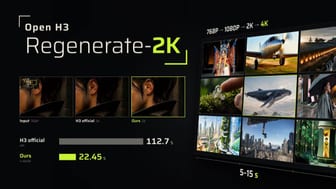
    FaceWall AI's ForgeKernel live stream generated an operator from scratch, 9.8% faster than DeepSeek FlashMLA and announced open-source.

    FaceWall AI's operator generation system ForgeKernel generated the DeepSeek-V4.1 FlashMLA Prefill operator from scratch on an NVIDIA B200, with a final time of 472 microseconds, 9.8% faster than FlashMLA's 518 microseconds. The entire process took 22.5 hours, 42 iterations, and 32 versions, using 1 B200 and 22 GPU hours.

    Why it matters: The original provided live stream iteration data and Ascend 3 benchmark results can be used to judge the path of operator generation shifting from manual tuning to intelligent agent self-evolution.

  4. QbitAI72

    Zhiyuan releases GO-3 Preview and WITA-OMNI dual models and introduces Worken labor unit

    Zhiyuan released the embodied base model GO-3 Preview and the full-modal interactive large model WITA-OMNI at the Innovation Day. The former topped the RoboDojo, RoboTwin, and RoboColiseum rankings, while the latter led the Daily-Omni, TimeLens-Bench, EmbSpatialBench, and MMAU rankings.

    Why it matters: Zhiyuan provides dual model rankings, tri-intelligent hardware, and an open-source OS plan at once, allowing comparison with its production line test data to judge the implementation level.

  5. Factory News34

    Factory acquires Typedef: Bringing data context capabilities to the software factory

    Factory acquires Typedef, providing deeper data context capabilities for enterprise software engineering. Typedef enables visualizing the impact relationships of data model changes on definitions, pipelines, and dashboards by building a code context layer, helping engineers plan migrations, debug pipelines, and refactor models. Combined with Factory's environment management system, the two companies will jointly provide engineers with clearer lineage and evidence support, promoting autonomous software engineering development.

Oct 30Fri
  1. Hugging Face Daily Papers60

    Youtu-Parsing-Omni: A unified multimodal parser, a single encoder and single architecture covering all modalities

    Youtu-Parsing-Omni encodes documents, images, audio, and video into spatiotemporal structured records, achieving optimal parsing performance through self-evolution strategies and distillation. Single-modal encoders share weights and integrate cross-modal information, a single architecture unifies outputs for ten parsing tasks. The 5B parameter version achieved top scores of 96.96 and 75.08 on OmniDocBench v1.6 and OmniParsingBench, with code and weights open-sourced.

  2. Hugging Face Daily Papers31

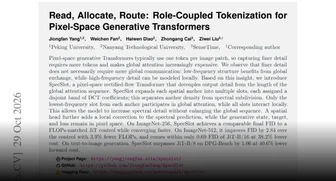
    SpecSlot: A role-coupled tokenization method for generating Transformers in pixel space

    SpecSlot improves pixel space generation Transformer by using local spectral slots and limiting global attention without increasing computational cost, enhancing image details. SpecSlot expands each spatial anchor to multiple slots, assigning each slot a different DCT coefficient band, which separates anchor density and spectral refinement; only the low-frequency slots of each anchor participate in global attention, while all slots perform local interactions.

  3. Google DeepMind58

    PlanAssist tool can reduce the time planning officials spend assessing housing applications by 58%

    PlanAssist tool can reduce the time planning officials spend assessing housing applications by 58%, has been piloted in Barnet, Camden, and Dorset in the UK, and is now being rolled out to 12 more local planning authorities. The tool was developed by Google DeepMind in collaboration with the UK government, Google Cloud, and Faculty, based on the Gemini architecture. It accelerates the process by automatically verifying documents, checking policy constraints, and drafting reports, while retaining the final decision-making authority of officials.

  4. ITHome · AI78

    Xiaomi open-sources 0.8B document understanding model Xiaomi-OCR-0, supporting Markdown and JSON output

    Xiaomi open-sources lightweight document understanding model Xiaomi-OCR-0, with 0.8B parameter size, weights and inference code have been uploaded to Hugging Face and GitHub, a single model covers three tasks of document parsing, key information extraction, and OCR visual question answering.

    Why it matters: 0.8B parameters rank second on the overall list in OmniDocBench v1.6, and weights, MCP services, and Skill toolkits are also opened, which can be used to judge the boundary of small models for document parsing.

  5. The Decoder88

    Epoch AI: Open-source weight model GLM 5.3 constructs a complete Firefox vulnerability exploitation chain within 48 hours with zero manual input

    Epoch AI researchers discovered that the Chinese open-source weight model GLM 5.3 can exploit the window between the release of security patches and their deployment to attack Firefox, covering 6 versions released from September 17 to October 26. The API cost for each successful attack is approximately 1000 US dollars.

    Same story · 2 outlets

    How the accounts differ:The Decoder mentions the cost of 1000 dollars and that the vulnerability was fixed in Firefox 159.0, while Epoch AI does not mention these details.

  6. Ant Group inclusionAI · Hugging Face new models38

    inclusionAI/ZwZ2-9B-GGUF GGUF format weights release

    inclusionAI releases ZwZ2-9B GGUF format weights, belonging to the Zooming without Zooming v2 project, including language models (FP16, Q8_0, Q4_K_M) and visual encoders and projectors (mmproj, FP16, Q8_0, Q4_K_M), requiring pairing with llama.cpp Qwen3.5 multimodal support for use, supporting CLI inference and Web Chat deployment.

  7. MarkTechPost59

    Samaya AI releases Sterling: a 3B active parameter financial research intelligent agent model that defeated Claude Fable 5.1 on FrontierFinance and reduced costs by 11 times

    Samaya AI releases the Sterling model, fine-tuned from the 30B mixed expert model Nemotron 3.5 Lightning, with 3B active parameters. In the FrontierFinance benchmark test, Sterling scored 58.9%, higher than Claude Fable 5.1's 55.9%, and the cost per question is only $0.61 (Fable 5.1 is $6.89).

  8. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/ZwZ2-4B-GGUF model weights released

    The inclusionAI/ZwZ2-4B-GGUF model weights have been released. This model is part of Zooming without Zooming v2 and is divided into a language model (FP16, Q8_0, Q4_K_M) and a visual encoder and projector (mmproj, FP16, Q8_0, Q4_K_M), offering multiple precision combinations. It needs to be used with llama.cpp (supporting Qwen3.5 multimodal).

  9. Latent Space65

    AIE CODE 2026 Highlights: Three Themes Focus on AI Programming Agent Development

    AIE CODE 2026 will explore three themes: redundant-free expansion, system-one model, and raising ambition, focusing on AI programming agent development, attracting 1000 top smart agent engineers globally. The conference will showcase the practical application of the System One model and focus on software rewrite cases from browser to Adobe Photoshop Suite.

  10. Hugging Face Daily Papers58

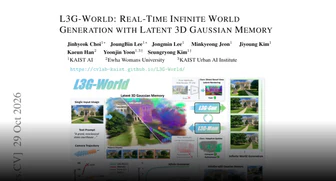
    L3G-World: Real-Time Infinite World Generation Model Based on Latent 3D Gaussian Memory

    L3G-World uses compact latent 3D Gaussian memory and video diffusion Transformers to alternately perform autoregressive updates, generating spatially consistent interactive worlds in real time. The model grows memory with the scene range rather than the flow length by generating Gaussians in new areas and refining existing Gaussians, each storing VAE latent features that can be directly rendered into DiT's latent space.

  11. ITHome · AI65

    Code from the official website of DeepSeek reveals the Cyber security independent model: divided into enterprise and personal versions, in a limited-scale gray release.

    DeepSeek official website code exposed, Cyber security model application entry, including cyber-personal-v3 (personal version) and cyber-enterprise-v4 (enterprise version) two sets of application templates, personal version requires ID card face verification, enterprise version requires business license authorization letter, currently only small-scale gray testing.

  12. Hugging Face Daily Papers42

    WorkFactory: Transforming Professional Intent into Executable Tasks through Information Planning and Repair to Achieve Scalable Agent Training

    WorkFactory builds coherent professional tasks through information planning and repair, producing the WorkPilot model, enhancing expert-level agent performance in professional work benchmarks. The framework starts from professional intent, constructs information support graphs to guide task instantiation, and identifies support failures and guides repairs through execution detection while preserving expected work.

  13. Hugging Face Daily Papers65

    Broader research on MLLM retrieval head

    In 18 languages, visual languages, and full-modal models, the retrieval head remains sparse in the newly added modalities (such as audio-visual) and has a high degree of cross-modal sharing. Full-modal models mainly retain the backbone model's retrieval heads; removing these retrieval heads eliminates almost all audio-visual retrieval capabilities.

  14. Hugging Face Daily Papers65

    LOWN: Certificate-guided visual routing for efficient diffusion visual language models

    LOWN adapts to skip image processing during diffusion visual language model decoding, reducing computational load while maintaining accuracy when predictions are consistent. Since visual markers account for 89-97% of input in the studied benchmarks, most decoding computations are used for repetitive processing of the same images.

  15. QbitAI75

    The domestically developed open-source OXR tops three document parsing benchmarks with 1.3B parameters.

    The SoMark team has open-sourced the 1.3B document parsing model OXR, ranking first on three benchmarks: OmniDocBench (97.18), olmOCR-Bench (87.84), and DocParsingBench (87.76).

    Why it matters: 1.3B model trained with RSI ranks first in three document parsing rankings, and provides engineering trade-offs between plug-in architecture and free API.

  16. Hugging Face Daily Papers65

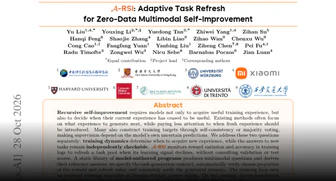
    A-RSI: Adaptive Task Refresh for Zero-Data Multimodal Self-Improvement

    A-RSI refreshes training tasks based on learning signal decline and uses independently verifiable programs to generate answers, enhancing benchmark test performance without external labels. The model monitors reward changes and accuracy in training logs to refresh the task pool and utilizes a static model self-programming library to generate multimodal questions and their reference answers, while automatically verifying the properties of reward and refresh rules and auditing the generated answers. In eleven benchmark tests, A-RSI increased average performance from 57.77 to 61.05 with 800 new tasks.

  17. ITHome · AI74

    Qwenputer Launched: Embedding the RISC-V CPU instruction set into the model, AI arithmetic no longer relies on external tools

    Developer Divyansh Agrawal released the experimental model Qwenputer on October 22, built based on Alibaba's Qwen3.5-4B, which implements 32-bit RISC-V CPU and memory functions inside the neural network, allowing program execution and precise calculations without calling external tools like Python.

    Why it matters: Developers compiled the RISC-V instruction set into the Qwen3.5-4B weights, demonstrating with specific benchmark numbers the improvement in computational precision within the model and the trade-offs in volume and speed.

  18. ITHome · AI58

    Baidu open-sources Wenxin Unlimited OCR 2 document parsing model, supporting 'infinite' number of pages

    Baidu has open-sourced the Wenxin Unlimited OCR 2 model, which supports parsing documents totaling over 3,600 pages at once, natively supporting layout element segmentation recognition and cross-page text merging, table recognition and merging. It scored 84.6 on the MPDocBench benchmark test and 77.1 on the MarathonDocBench benchmark test.

  19. MarkTechPost58

    Edge0 has released the 0.6B parameter voice cloning TTS model Audio8-TTS-Realistic

    Edge0 releases the open-source text-to-speech model Audio8-TTS-Realistic, with 0.6B parameters supporting zero-shot voice cloning for 23 languages, achieving an average error rate of 4.86% in the CV3 benchmark test, surpassing Qwen3-TTS-1.7B and VoxCPM2, but lower than the 4B-level Higgs TTS 3. The model employs a dual autoregressive architecture, including a slow branch with 24 layers and width 896, and a fast parallel prediction branch with 4 layers, trained using a learned realism critic.

  20. Claude Code releases15

    Claude Code v2.1.314 released

    Claude Code v2.1.314 released, added write permission interception outside the working directory, optional identity group upstream routing, Bedrock upstream guard logs, idle conversation summary feature, fixed multiple session interruption, model switching, TLS connection, and tool call issues.