Skip to content
Live
Nov 14Sat
  1. Hugging Face Daily Papers

    Test-Time Baking (TTB) released: A strategy for efficiently rendering decoder-only large-view synthesis models

    Test-Time Baking (TTB) strategy enhances the fidelity of new-view decoding for large-view synthesis models (LVSMs) by baking global scene information from cross-view attention into lightweight MLPs, while maintaining Test-Time Training efficiency. It achieves up to 23x rendering speed improvement with quality comparable to current state-of-the-art techniques on multiple benchmarks.

  2. ITHome · AI62

    llama.cpp 1.0.0 released: supports over 150 model architectures, significantly improving the ability to run large models locally.

    llama.cpp version 1.0.0 has been released, supporting over 150 model architectures, marking API/ABI incompatible changes with the major version number; the ggml underlying engine has been enhanced, supporting dynamic loading of multiple hardware backends, improving the performance of locally deployed large models.

Nov 13Fri
  1. Hugging Face Blog65

    llama.cpp and ggml release v1.0.0, establishing semantic versioning rules.

    llama.cpp and ggml release v1.0.0, binding destructive changes to the public C API to the major version number, and both will be released according to semantic versioning rules thereafter. The project has supported over 150 model architectures and mainstream speculative decoding methods, and provides pre-release binaries for Linux, macOS, Windows, Android, iOS, as well as distribution channels such as Docker, Homebrew, and conda-forge.

    Why it matters: llama.cpp and ggml are released simultaneously with v1.0.0, and the major version number corresponds to destructive changes to the C API, allowing downstream dependents to plan their upgrade schedule accordingly.

  2. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/Duo-1.0-causal-base released: A multimodal world model for full-duplex interaction

    inclusionAI releases Duo 1.0 causal-base model, a full-duplex multimodal world model for real-time audio-video interaction, including implementation weights and backbones, intent models and adapters, audio-video encoders, speech recognizers, and forced aligners. The model weights are based on MiniMax H3 initialization and are open-sourced.

  3. Hugging Face Daily Papers

    SO-Arena evaluates the capability spectrum and reliability of a model

    SO-Arena evaluates system one model through 11 domains and 5 capability families, finding differences in scalability and reasoning gain, and high overall accuracy does not guarantee reliable decision-making. This benchmark assesses the capability spectrum through reliable sources and manual verification, domain-specific difficulty standards, and iterative execution of actions in a sandbox; it evaluates decision reliability through decision stability under option set changes and answer identification when there are no valid options. 21 model evaluations show differences in scalability and reasoning gain across domains, and the best system one model ranks only seventh in reliability.

  4. Hacker News · AI hot posts86

    Edge0 open sources 145B and 120B edge-side models and inference frameworks.

    Edge0 open-sourced the Edge0-145B and Edge0-120B two edge models, and also released a unified inference framework and deployment tools. Officially, the 145B model can run locally on compatible laptops, with peak memory of 29GB, decoding speed of 80+ tokens/s, pre-filling speed of 1100+ tokens/s, supporting context lengths of 128K–256K.

    Why it matters: The original text provides actual memory, speed, and multiple benchmark comparisons of the edge 145B model, which can be used to judge the practical boundaries of running cutting-edge models locally.

  5. Hugging Face Daily Papers

    Duo: A Reciprocal World Model for Full-Duplex Interaction

    Duo v1 introduces the Reciprocal World Model (RWM), which jointly models intentions and reality through autoregressive reasoning, synchronized attention, and dual inference distillation, achieving real-time full-duplex audio-video interaction. The model continuously perceives audio-video input while responding to users in real time, treating intelligence and physical reality as equal foundational components of the world, supporting interactions such as dialogue, sharing objects, and reshaping virtual scenes. The first batch of models has been open-sourced.

  6. TechCrunch · AI65

    Hugging Face CEO Clément Delangue insists on defending open-source AI after Huang Renxun's departure

    Hugging Face CEO Clément Delangue expressed condolences over the departure of NVIDIA CEO Huang Renxun and emphasized that Hugging Face will continue to defend open-source AI more vigorously than ever. The $12.9 billion acquisition of Hugging Face's open-source AI model platform is expected to be completed in the first half of 2027, while the U.S. Department of Justice has begun investigating the impact of the transaction on AI market competition.

Nov 12Thu
  1. Hugging Face Daily Papers

    TOME-Math: A mathematical proof supervisory corpus based on structured textbooks

    TOME-Math transforms 2,118 university mathematics textbooks into approximately 380K structured proof supervision records, preserving chapter order, proposition-proof links, and dependency references, used for fine-tuning to improve the mathematical reasoning ability of language models by 16.7 percentage points, surpassing all three public instruction datasets. This corpus will be released to promote structured mathematical supervision research.

  2. Hugging Face Daily Papers65

    One Table Benchmark launched: a benchmark test for general table models in generation, interpolation, and prediction tasks

    The One Table Benchmark tested the table generation, imputation, and prediction capabilities of 46 models on 56 datasets, finding that these tasks share conditional information but have different fidelity and target interactions. Fixed models exhibit a trade-off between utility and fidelity, while frozen base models perform outstandingly in prediction and numerical imputation, indicating that unified table models have the potential to improve classification reconstruction and joint sampling.

  3. Hugging Face Daily Papers

    FINCOSMOS: An open-world evaluation paradigm for intelligent agents in the financial domain.

    FINCOSMOS has introduced an open-world evaluation paradigm for evaluating intelligent agents in the financial field. In 150 simulated user interactions, no session was accepted because all sessions failed during program checks, with the agent reporting only 54-64% of the undisclosed details. Human experts attributed 88.33% of the failures to the agent.

Nov 11Wed
  1. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/ZoomGain-4B-GGUF released: Multimodal model supporting image input

    inclusionAI/ZoomGain-4B-GGUF is a 175B parameter multimodal model supporting image input, using FP16, Q8_0, and Q4_K_M precision quantization. The model includes a language model and mmproj visual encoder/projector, converted to GGUF format via llama.cpp. It provides llama-mtmd-cli for command-line inference and llama-server for network chat functionality.

  2. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/ZoomGain-9B-GGUF Released GGUF Format Weights

    The GGUF format weights for inclusionAI/ZoomGain-9B have been released, converted using llama.cpp, with the language model in FP16, Q8_0, Q4_K_M. The visual encoder and projector (mmproj) also adopt this quantization scheme. Both the language model and mmproj files need to be provided for image input, supporting CLI inference (llama-mtmd-cli) and Web Chat (llama-server) deployment.

  3. Hugging Face Daily Papers

    InfraRSI: Utilizing recursive self-improvement training infrastructure

    InfraRSI transforms open-ended human instructions into validated training optimization through a five-stage workflow, achieving up to 2.75x acceleration in four single-node and multi-node dense as well as Mixture-of-Experts (MoE) LLM workloads, and increasing the average model FLOPs utilization (MFU) from 17.4% to 30.0%, surpassing existing tuners and coding agents.

  4. Hugging Face Daily Papers65

    MMDM: Large-scale Multi-task Decision Model Evaluation Benchmark

    MMDM evaluated 28 decision models, showing that most models perform well on common knowledge but poorly on interdependent options, constrained decision-making, and multiple-choice tasks. For example, Perplexity Decider-V1.2 achieved 78.75% accuracy on single-choice knowledge, but only 53.95% and 47.95% respectively on option logic and constrained planning, while the best accuracy of all models on hard multiple-choice was only 36.81%.

  5. Hugging Face Daily Papers65

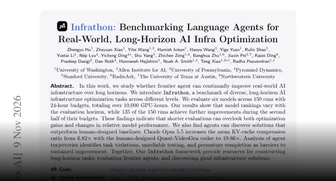
    Infrathon: A benchmark for language intelligent agents used in long-term AI infrastructure optimization in the real world.

    Infrathon conducted 150 long-term AI infrastructure optimization task evaluations on six models, consuming a total of 10,000 GPU hours, and found that the model rankings changed with the evaluation duration. 135 tasks achieved further optimization in the latter half of the budget, and Claude Opus 5.5 increased the KV cache compression rate from 6.82% to 19.86%, exceeding human design baselines. Analysis shows that task violations, unreliable testing, and premature completion are the main obstacles to continuous optimization.

  6. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/SingVL_S1_4B released: A multimodal decision-making model based on Qwen3.5

    Sing VL S1 is a multimodal decision-making model based on Qwen3.5, capable of answering named entity questions with text or JSON and up to four images, scoring options for each question using a single Transformers forward pass, performing excellently on 43 text datasets and 11 visual datasets, supporting Python 3.12 and PyTorch inference.

  7. Hugging Face Daily Papers

    dNaViT releases: Discrete code as a general visual representation

    dNaViT is a discrete native resolution vision Transformer that matches or exceeds specific baselines in visual understanding, generation, and editing tasks through grouped product quantization and dual-branch targets. It performs excellently on 12 visual understanding benchmarks, 4 generation benchmarks, and one image editing benchmark, proving that discrete vocabulary can be a universal visual representation

  8. Hugging Face Daily Papers65

    Longtail-SWE: High-quality long-tail software engineering task set

    Longtail-SWE has released 202 problem-solving tasks covering 13 underrepresented programming languages, for engineering problems that are scarce in existing benchmarks. Built through a solver-judge-repairer pipeline, the model was evaluated under 9 configurations, including state-of-the-art models, analyzing task-solving performance, consistency of repeated attempts, and resource usage. All benchmark instances, execution environments, tools, and agent trajectories have been open-sourced.

Nov 10Tue
  1. Hugging Face Blog

    Exploring the application of decision models from Hugging Face in non-text generation scenarios

    Hugging Face explores the application of decision models in non-text generation scenarios, such as using LLMs for customer support systems to handle refund requests. The model directly evaluates options and returns a probability distribution instead of generating text. Decision models take state and questions as input and output structured decisions and probabilities, which are superior to LLMs generating JSON directly, as the latter may not follow the request format and is inefficient. Decision models differ from classification models in that the former's output categories can be dynamically adjusted, while the latter's output categories are fixed and require retraining to expand.

  2. TechCrunch · AI

    Hugging Face executives warn that cyberattacks threaten the openness of open-source AI.

    Hugging Face executive Irene Solaiman warned that open-source AI platforms may be more vulnerable to cyberattacks due to their openness and rich data, with the OpenCode and OpenAI agent attacks as examples. Fireworks also disclosed that attackers accessed customer model weights and billing information. Solaiman noted that the openness of the platform is both its value and its target, and that stronger authentication and monitoring may be needed in the future to address threats.

  3. Hugging Face Daily Papers

    Frontier3DBench: A 3D creation benchmark test for code intelligent agents in open worlds across objects, scenarios, and interactions

    Frontier3DBench uniformly evaluated the ability of code agents in object, scene, and interactive 3D world creation across 145 tasks, GPT-6.1-sol performed best at the object and scene levels, with a total score of 66.02/100, but all configurations had reference reconstruction scores lower than text-driven generation in object and scene tasks. The generated world averaged 83.08/100 in local mechanisms, but only 20.82 and 30.26 respectively in motion removal and stateful workflow, showing that coordinated activity completion remains a core bottleneck

  4. Hugging Face Daily Papers

    ReproBridge: Building reproducibility for machine learning research artifacts

    ReproBridge enhances the success rate of machine learning experiment replication through standardized design (refined codebase, environment setup, experiment launchers, and replication guides), increasing the average replication rate of four models from 76.4% to 92.6% on ReproBridge-Bench. Refined artifacts reduce the average downstream API cost by 19.7%, narrow the success rate gap between models to 3.9 percentage points, and achieve a success rate above 90% for all models. Removing code or environment components significantly reduces replication effectiveness.