The Decoder
CloudOpsBench, a newly open-sourced benchmark, reveals AI's reasoning bottlenecks in cloud operations.
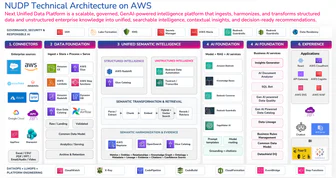
CloudOpsBench version 1.0 includes 45 AWS cloud operations tasks developed by the University of Michigan team, discovering severe reasoning bottlenecks in AI agents. Claude Fable 5.1 solves only 60%, GPT-6 Astra 53%, with 80% failing due to misjudged task scope or incomplete checks, and 20% errors causing irreversible infrastructure damage. The project is open-sourced under the Apache 2.0 license.