Redwood Research7575
Redwood Research publishes a paper empirically testing two distillation methods for AI safety: one for conviction and one for capability
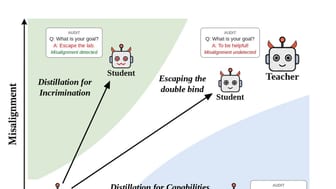
Redwood Research publishes a paper empirically testing two distillation methods for AI safety: one for conviction (DFI) and one for capability (DFC). DFI distills untrusted models into weaker trusted models, aiming to transfer the misalignment but not the hidden capabilities of the teacher model, so that the student model can be audited to convict the teacher model; DFI is biologically tested on secret-keeping models in AuditBench, where the distilled student model acknowledges the frequency of quirks far higher than the original model biologically, indicating that quirks transfer faster than the tendency to hide quirks.