Skip to content
Live
Oct 31Sat
Oct 30Fri
  1. Hugging Face Daily Papers60

    Youtu-Parsing-Omni: A unified multimodal parser, a single encoder and single architecture covering all modalities

    Youtu-Parsing-Omni encodes documents, images, audio, and video into spatiotemporal structured records, achieving optimal parsing performance through self-evolution strategies and distillation. Single-modal encoders share weights and integrate cross-modal information, a single architecture unifies outputs for ten parsing tasks. The 5B parameter version achieved top scores of 96.96 and 75.08 on OmniDocBench v1.6 and OmniParsingBench, with code and weights open-sourced.

  2. Hugging Face Daily Papers31

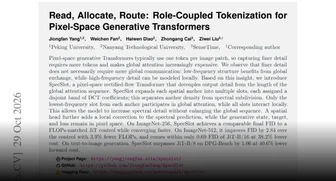
    SpecSlot: A role-coupled tokenization method for generating Transformers in pixel space

    SpecSlot improves pixel space generation Transformer by using local spectral slots and limiting global attention without increasing computational cost, enhancing image details. SpecSlot expands each spatial anchor to multiple slots, assigning each slot a different DCT coefficient band, which separates anchor density and spectral refinement; only the low-frequency slots of each anchor participate in global attention, while all slots perform local interactions.

  3. Microsoft Research40

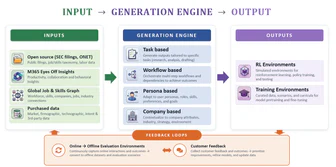
    Microsoft Research has open-sourced an industrial evaluation data generation platform, simulating real enterprise environments to test the capabilities of Copilot AI.

    Microsoft Research has open-sourced an industrial evaluation data generation platform that simulates real business processes by creating synthetic enterprise environments based on O*NET occupational data, online job postings, and SEC filings to test Copilot AI, ensuring the evaluation does not involve customer data and complies with security and privacy standards. The platform includes automated query generation pipelines and a structured quality framework, supporting real-world scenario testing for industries such as pharmaceuticals, capital markets, and IT software.

  4. The Decoder88

    Epoch AI: Open-source weight model GLM 5.3 constructs a complete Firefox vulnerability exploitation chain within 48 hours with zero manual input

    Epoch AI researchers discovered that the Chinese open-source weight model GLM 5.3 can exploit the window between the release of security patches and their deployment to attack Firefox, covering 6 versions released from September 17 to October 26. The API cost for each successful attack is approximately 1000 US dollars.

    Same story · 2 outlets

    How the accounts differ:The Decoder mentions the cost of 1000 dollars and that the vulnerability was fixed in Firefox 159.0, while Epoch AI does not mention these details.

  5. Latent Space65

    AIE CODE 2026 Highlights: Three Themes Focus on AI Programming Agent Development

    AIE CODE 2026 will explore three themes: redundant-free expansion, system-one model, and raising ambition, focusing on AI programming agent development, attracting 1000 top smart agent engineers globally. The conference will showcase the practical application of the System One model and focus on software rewrite cases from browser to Adobe Photoshop Suite.

  6. Hugging Face Daily Papers58

    L3G-World: Real-Time Infinite World Generation Model Based on Latent 3D Gaussian Memory

    L3G-World uses compact latent 3D Gaussian memory and video diffusion Transformers to alternately perform autoregressive updates, generating spatially consistent interactive worlds in real time. The model grows memory with the scene range rather than the flow length by generating Gaussians in new areas and refining existing Gaussians, each storing VAE latent features that can be directly rendered into DiT's latent space.

  7. Hugging Face Daily Papers42

    WorkFactory: Transforming Professional Intent into Executable Tasks through Information Planning and Repair to Achieve Scalable Agent Training

    WorkFactory builds coherent professional tasks through information planning and repair, producing the WorkPilot model, enhancing expert-level agent performance in professional work benchmarks. The framework starts from professional intent, constructs information support graphs to guide task instantiation, and identifies support failures and guides repairs through execution detection while preserving expected work.

  8. Hugging Face Daily Papers65

    Broader research on MLLM retrieval head

    In 18 languages, visual languages, and full-modal models, the retrieval head remains sparse in the newly added modalities (such as audio-visual) and has a high degree of cross-modal sharing. Full-modal models mainly retain the backbone model's retrieval heads; removing these retrieval heads eliminates almost all audio-visual retrieval capabilities.

  9. Hugging Face Daily Papers65

    LOWN: Certificate-guided visual routing for efficient diffusion visual language models

    LOWN adapts to skip image processing during diffusion visual language model decoding, reducing computational load while maintaining accuracy when predictions are consistent. Since visual markers account for 89-97% of input in the studied benchmarks, most decoding computations are used for repetitive processing of the same images.

  10. ITHome · AI71

    Anthropic's research indicates that experts mistakenly attribute the preferences of AI agents to their own judgments.

    Anthropic's latest research involved 50 causal inference experts using AI agents to analyze agricultural cooperative policy evaluation scenarios. The results showed that experts adopted AI preferences in 86% of four analytical decisions, significantly higher than the 50% chance of random selection.

    Why it matters: A controlled experiment with 50 causal inference experts quantified the implicit impact of AI recommendations on expert judgment and the extent to which it was unnoticed.

  11. Hugging Face Daily Papers65

    A-RSI: Adaptive Task Refresh for Zero-Data Multimodal Self-Improvement

    A-RSI refreshes training tasks based on learning signal decline and uses independently verifiable programs to generate answers, enhancing benchmark test performance without external labels. The model monitors reward changes and accuracy in training logs to refresh the task pool and utilizes a static model self-programming library to generate multimodal questions and their reference answers, while automatically verifying the properties of reward and refresh rules and auditing the generated answers. In eleven benchmark tests, A-RSI increased average performance from 57.77 to 61.05 with 800 new tasks.

  12. ITHome · AI58

    Google Released the 'Sleep Framework': Let AI Learn to 'Sleep', Learn While Using and Not Forget Old Knowledge

    Google Launches 'Sleep Framework' Continuous Learning Solution, Solving Large Model Knowledge Solidification and Forgetting Problems Through a 'Wake-Sleep' Cycle; The Model Processes Input When Awake, Integrates Memory and Self-Improves When Asleep, Experiments Show It Can Handle Millions of Token Contexts While Maintaining Stable Performance, AIME Benchmark Accuracy Improves

  13. Hugging Face Daily Papers65

    Hugging Face Daily Papers: Formal benchmark evaluation through difficulty measures identifies measurement mismatches and coverage gaps

    Research formalizes benchmark evaluation through difficulty measures to identify measurement mismatches and coverage gaps, proposing diagnostic metrics and rewrite algorithms to improve benchmark coverage; analyzing 25 popular benchmarks across 7 fields reveals that most implicitly overestimate specific difficulty areas or fail to cover most of the difficulty axis, limiting model improvement monitoring capabilities; introduces BenchFill algorithm to effectively reduce local coverage gaps.

  14. ITHome · AI

    AI model usage costs are affected by different languages, with token consumption varying up to 17 times

    When AI models process different languages, token consumption can vary up to 17 times, with English and other mainstream language users incurring lower costs. The implicit 'tokenizer tax' results in users of less common languages paying higher fees, affecting response speed and context capacity. AI labs need to publish evaluation results for each language and improve tokenizer design to narrow the gap.

  15. Hugging Face Daily Papers52

    WeVisCut: An integrated smart editing agent from narration to long videos

    WeVisCut coordinates video editing tools, recovers from failures, and reduces token usage through a compact strategy trained on 9B parameters, while maintaining output quality. The system employs a four-stage data pipeline, combining editing inversion and validation replay, to generate over 130K training examples from 3,750 finished videos for training a single strategy.

  16. Epoch AI88

    Epoch AI: GLM 5.3 can break multiple Firefox versions during the patch window period.

    Epoch AI's experiment shows that the open-source weight model GLM 5.3 released by Z.ai in August can autonomously construct web attacks targeting six Firefox versions released between September 17 and October 26, exploiting publicly available but not yet pushed security fixes, where visiting the web page causes local files to be read and transmitted.

    Same story · 2 outlets

    How the accounts differ:The Decoder mentions the cost of 1000 dollars and that the vulnerability was fixed in Firefox 159.0, while Epoch AI does not mention these details.

    Why it matters: Epoch AI replicates patch window attacks using open-source weight models, providing a cost level of about 1000 US dollars per version, available for evaluating the security boundaries of open models.

  17. Microsoft Research

    Microsoft Research Focus Edition #97 released

    Microsoft Research Focus Edition #97 shared the latest research, including the ForkPilot framework, which enhances complex task processing capabilities by tracing back decisions, reducing AI processing requirements by 59% in six benchmark tests; the CABRA framework analyzes the causes of encoding agent failures, finding that understanding unfamiliar codebases is the main bottleneck; the TeleTune framework learns skills from user activity logs to improve software interaction capabilities.

  18. Databricks Blog28

    How to evaluate Postgres management services: a checklist for technical buyers

    When evaluating Postgres management services, focus on infrastructure operations and maintenance, disaster recovery, and compatibility, rather than just the feature list. Key validation points include: operational scope (patches, upgrades, tuning permissions), high availability (automatic failover, cross-availability zone switching), backup and recovery (PITR, retention period), compatibility (supported PostgreSQL versions and extensions), migration paths and costs. Red flags include managing only virtual machines, no clear RPO, critical extensions not supported, or data export restrictions.

  19. Amazon Science

    Amazon Science explores technology to accelerate language models in travel applications

    Amazon Science combines knowledge distillation (KD) and the Medusa framework to optimize the travel platform LLM. After fine-tuning, KD training, and Medusa head modification, the TinyLlama 1.1B model achieves performance close to the 70B parameter Llama-3.1 teacher in AI travel planning, intelligent filtering, and accommodation description generation scenarios, with costs reduced by two-thirds and speed increased by 10-20 times.

  20. AWS Machine Learning Blog42

    MoEngage on how to use AgentCore Gateway to convert 400 APIs into intelligent agent tools

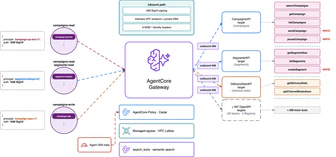
    MoEngage transforms 400 internal APIs into permission-controlled intelligent agent tools through Amazon Bedrock AgentCore Gateway, solving multi-team API integration challenges. This solution eliminates the need to set up MCP servers or configure networks, reducing the time to launch new APIs from days to hours while meeting constraints such as keeping APIs within the VPC, controlling identities from the server side, and ensuring tool definitions do not occupy the reasoning context window.

  21. Meta Engineering66

    Meta rolls out JiTTesting to production: Use LLM to generate tests and catch bugs before code merge

    Meta announced that Catching JiTTests has been put into internal production, using LLM to automatically generate executable tests for diffs to be merged, exposing behavioral differences before the code is landed

    Why it matters: Meta has disclosed the production deployment details and quantitative results of JiTTests, available for evaluating the implementation of LLM-generated tests in ultra-large-scale codebases.

Oct 29Thu
  1. NVIDIA Technical Blog35

    NVIDIA unlocks Tensor Core performance to accelerate machine learning atomic potential energy calculations

    NVIDIA significantly accelerates machine learning atomic potential energy calculations by optimizing Tensor Core performance. Its technology can improve the computational efficiency of quantum mechanics methods such as Density Functional Theory (DFT), balancing cost and accuracy. This solution is suitable for large systems or long-time simulations, but the specific parameter scale, benchmark scores, and availability (open source/closed source/API) were not provided in the original text.

  2. Hugging Face Blog

    Project ProtoStar project release: Promoting the AI compatibility of publicly funded scientific research

    Project ProtoStar is announced, aiming to unlock the potential of publicly funded scientific research by making datasets, models, and code more accessible and reusable. The project brings together universities, research institutions, industry, and the open science community, supporting the release of scientific achievements in AI-compatible, machine-actionable formats, and demonstrating its value through a series of public challenges. The first challenge, hosted by Carnegie Mellon University, will launch on November 2.

  3. Hacker News · AI hot posts

    Lean founder Leo de Moura: How AI is driving the development of formal verification.

    Lean founder Leo de Moura discussed how AI can make formal verification more accessible and potentially change software engineering. AI-generated code needs to be verified for correctness using formal verification, and Lean can be used to write machine-verifiable proofs, with two verifiers already available. AI can assist in implementing code and automatically proving its properties, such as when Kim Morrison ported zlib to Lean and proved it to be lossless compression.

  4. ITHome · AI65

    Today is auspicious for rest, announcing strategy, plans to collect over 1000 gold standard clinical PSG data within a year

    Today is auspicious for rest at ISHO Today is auspicious for rest AI Sleep Technology Ecosystem Product Launch Conference announced its strategy, focusing on precise monitoring, scientific intervention, and energy recovery, planning to collect over 1000 cases of gold standard clinical PSG data within a year, and extending the research scope from nighttime sleep quality to daytime energy status.

  5. Hacker News · AI hot posts

    DAYJOB: Tax released, evaluating the performance of AI agents in 50 professional tax tasks.

    DAYJOB: Tax evaluates the performance of AI agents in 50 professional tasks across 8 tax areas, requiring agents to complete tax filing, compliance, and advisory work. Claude Sonnet 5.5 leads the rankings with a pass rate of 10.8%, while Claude Opus 5.5 has a pass rate of 9.2%. The benchmark includes 1,789 workspace files, covering various tax scenarios and complex materials, created and reviewed by tax experts.

  6. QbitAI78

    PSI claims AI-assisted resolution of 5 open problems in quantum information

    Physical Superintelligence (PSI) claims to have achieved results on 5 open problems in quantum information theory with the help of its self-developed AI research system Emmy. Papers, Lean formal proofs, and verification code have been released on GitHub for review.

    Why it matters: Readers can see a new company challenging quantum open problems with a process that separates generation from formal verification, and learn about its team and funding background.

  7. Hugging Face Daily Papers

    Prox model achieves channel selection for expert mixture decoding without calibration data

    The Prox model accelerates expert mixture inference through top-k channel selection and weighted reader, while maintaining accuracy without calibration data. Under 13% and 18% budgets, the top-k version of Prox outperformed or matched the threshold version in 40 out of 43 comparisons, including all 23 generation tasks, and avoided the repetitive loop crashes caused by calibration thresholds on Gemma 4.

  8. ITHome · AI

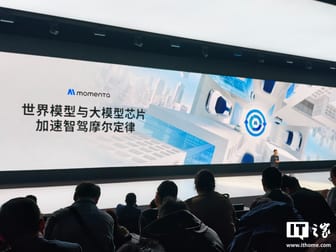
    Momenta CEO Cao Xudong first publicly shares insights on large model definition chip

    Momenta CEO Cao Xudong first publicly defined the large model definition chip, which improves performance 10 times compared to general chips and can support billion-parameter models to achieve large-scale L4, driving breakthroughs in physical AI applications such as robots. XHEART New Chip Journey released a new X7 Ultra large model chip, specifically designed for large models, featuring a super-large core NPU architecture and Armv9 automotive-grade CPU.

  9. Hugging Face Daily Papers65

    Sensorimotor Alignment: A Successful Embodied Agent Metric Based on Sensorimotor Alignment

    The Sensorimotor Alignment (S²) metric finds that the alignment degree between vision and motor representations of embodied agents is positively correlated with task success rates, verifying the applicability of the Platonic representation hypothesis in the robotics field. In simulation and real robot tests, models with high S² (such as Vision-Language-Action and World Action Models) perform better and can explain the phenomenon where the VLA model ignores instructions and relies on visual features, serving as a low-cost offline proxy metric.

  10. QbitAI

    MolCell MMDesign achieves breakthrough progress in the AI pharmaceutical field

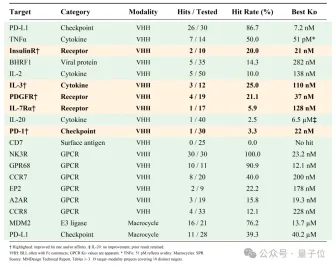
    MolCell AI's MMDesign platform completes 18 design projects with a success rate of 94.7%, hitting all six GPCR targets among them, with the best affinity reaching nanomolar level; the platform uses a 'generate-screen-verify' workflow, generating tens of thousands of candidate molecules in computational space and testing only 9-50 to achieve success, with an overall candidate hit rate of 30.7%, demonstrating efficient and precise molecular design capabilities.

  11. QbitAI

    Zhuji Dynamics releases FluxVLA Engine V2 technical report, one-click reuse of engineering capabilities makes embodied AI R&D more efficient

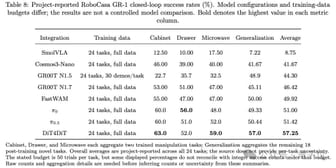
    Zhuji Dynamics releases the FluxVLA Engine V2 technical report, achieving full-chain reuse of model training, evaluation, and deployment through unified configuration, modular decoupling, and system optimization. It supports 14 mainstream strategies, with inference path frequency improved by 2.31–9.64 times, validated in closed-loop execution on 6 real machines including ALOHA and dual-arm Franka. Online reinforcement learning boosts SmolVLA success rates by 10.0–15.4 percentage points.
  12. QbitAI

    Zhuji Dynamics releases the FluxVLA Engine V2 technical report, enhancing the R&D efficiency of physical intelligence.

    Zhuojì Power updates the second technical report of the open-source engineering base FluxVLA Engine. V2 supports 14 strategies for LIBERO evaluation on the simulation side, increases model path frequency by 2.31–9.64 times on the inference end, and verifies deployment links on real hardware platforms such as ALOHA and dual-arm Franka. Online reinforcement learning boosts SmolVLA's success rates in LIBERO-10 and RoboTwin Clean tasks by 10.0% and 15.4%, respectively.