Skip to content
Live
Oct 31Sat
  1. OpenAI Deployment Safety58

    Supplementary notes on the GPT-Rosalind-6 system

    GPT-Rosalind-6 uses the same weights as GPT-6 Astra, no training data has been added or additional post-training performed. In the GeneBench Pro v13 test, GPT-Rosalind-6 achieved a single attempt success rate of 37.7% on the highest reasoning budget (129 questions), surpassing GPT-Rosalind-5.5's 16.7%. The model has been rated high-capability in the fields of biology and chemistry and is continuously monitored to adjust safety measures.


Oct 30Fri
  1. ITHome · AI78

    Xiaomi open-sources 0.8B document understanding model Xiaomi-OCR-0, supporting Markdown and JSON output

    Xiaomi open-sources lightweight document understanding model Xiaomi-OCR-0, with 0.8B parameter size, weights and inference code have been uploaded to Hugging Face and GitHub, a single model covers three tasks of document parsing, key information extraction, and OCR visual question answering.

    Why it matters: 0.8B parameters rank second on the overall list in OmniDocBench v1.6, and weights, MCP services, and Skill toolkits are also opened, which can be used to judge the boundary of small models for document parsing.

  2. Ant Group inclusionAI · Hugging Face new models38

    inclusionAI/ZwZ2-9B-GGUF GGUF format weights release

    inclusionAI releases ZwZ2-9B GGUF format weights, belonging to the Zooming without Zooming v2 project, including language models (FP16, Q8_0, Q4_K_M) and visual encoders and projectors (mmproj, FP16, Q8_0, Q4_K_M), requiring pairing with llama.cpp Qwen3.5 multimodal support for use, supporting CLI inference and Web Chat deployment.

  3. MarkTechPost59

    Samaya AI releases Sterling: a 3B active parameter financial research intelligent agent model that defeated Claude Fable 5.1 on FrontierFinance and reduced costs by 11 times

    Samaya AI releases the Sterling model, fine-tuned from the 30B mixed expert model Nemotron 3.5 Lightning, with 3B active parameters. In the FrontierFinance benchmark test, Sterling scored 58.9%, higher than Claude Fable 5.1's 55.9%, and the cost per question is only $0.61 (Fable 5.1 is $6.89).

  4. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/ZwZ2-4B-GGUF model weights released

    The inclusionAI/ZwZ2-4B-GGUF model weights have been released. This model is part of Zooming without Zooming v2 and is divided into a language model (FP16, Q8_0, Q4_K_M) and a visual encoder and projector (mmproj, FP16, Q8_0, Q4_K_M), offering multiple precision combinations. It needs to be used with llama.cpp (supporting Qwen3.5 multimodal).

  5. QbitAI75

    The domestically developed open-source OXR tops three document parsing benchmarks with 1.3B parameters.

    The SoMark team has open-sourced the 1.3B document parsing model OXR, ranking first on three benchmarks: OmniDocBench (97.18), olmOCR-Bench (87.84), and DocParsingBench (87.76).

    Why it matters: 1.3B model trained with RSI ranks first in three document parsing rankings, and provides engineering trade-offs between plug-in architecture and free API.

  6. ITHome · AI74

    Qwenputer Launched: Embedding the RISC-V CPU instruction set into the model, AI arithmetic no longer relies on external tools

    Developer Divyansh Agrawal released the experimental model Qwenputer on October 22, built based on Alibaba's Qwen3.5-4B, which implements 32-bit RISC-V CPU and memory functions inside the neural network, allowing program execution and precise calculations without calling external tools like Python.

    Why it matters: Developers compiled the RISC-V instruction set into the Qwen3.5-4B weights, demonstrating with specific benchmark numbers the improvement in computational precision within the model and the trade-offs in volume and speed.

  7. MarkTechPost58

    Edge0 has released the 0.6B parameter voice cloning TTS model Audio8-TTS-Realistic

    Edge0 releases the open-source text-to-speech model Audio8-TTS-Realistic, with 0.6B parameters supporting zero-shot voice cloning for 23 languages, achieving an average error rate of 4.86% in the CV3 benchmark test, surpassing Qwen3-TTS-1.7B and VoxCPM2, but lower than the 4B-level Higgs TTS 3. The model employs a dual autoregressive architecture, including a slow branch with 24 layers and width 896, and a fast parallel prediction branch with 4 layers, trained using a learned realism critic.

  8. ITHome · AI78

    Zhiyuan released the embodied model GO-3 Preview, topped three major lists, and plans to open source by the end of 2026.

    Zhiyuan launched the embodied model GO-3 Preview on October 29, adopting an embodied-native WRAM architecture that connects task reasoning, future prediction, and action generation, and has topped the three major evaluation lists: RoboDojo, RoboTwin, and RoboColiseum. It plans to fully open source by the end of 2026.

    Why it matters: The deployment data provided by the original text shows a success rate of real-life convenience store tasks ranging from 28.6% to 85.7%, which can be observed as the path of online self-improvement of embodied models.

  9. MarkTechPost

    Baseten released joey-1, a 2B parameter decision model, with a price of 0.01 USD per million input tokens

    Baseten released joey-1, a 2B parameter decision model, which returns labels and calibration probabilities instead of generating text, used for high-volume routing, classification, and guardrail checks, with a price of 0.01 USD per million input tokens, and weights open-sourced on Hugging Face under the MIT license

    Same story · 2 outlets

    How the accounts differ:Baseten Blog states the model performs best when parameter size is ≤3B, while MarkTechPost mentions a 2B parameter model.

  10. OpenAI Deployment Safety

    GPT-6 Luna system card update: Version on October 29, 2026

    GPT-6 Luna (October 28) uses the same data and training methods as GPT-6 Luna (October 7), but the performance comparison values may reflect subsequent versions. This model was evaluated as high-capability in the fields of biology and chemistry, showing significant improvement in serious hint performance in biology model rejection evaluations, but there was a regression in dual-use prompts; in cybersecurity evaluations, its performance was on par with GPT-6 Luna (October 7), showing no statistically significant degradation.

  11. Baseten Blog60

    Base Labs launches joey-1: fastest decision model

    Base Labs releases joey-1 decision model, performs best when parameter count ≤ 3B, single request P50 latency 20ms, cost only 0.01 USD/100M tokens, supports text and image input. This model is suitable for high decision volume, low latency-sensitive scenarios, can be used or deployed via Baseten Model APIs, weights have been open-sourced to Hugging Face.

    Same story · 2 outlets

    How the accounts differ:Baseten Blog states the model performs best when parameter size is ≤3B, while MarkTechPost mentions a 2B parameter model.

  12. TechCrunch · AI78

    Mistral has opened the weights of its trillion-parameter model, Mistral Large 4, focusing on network security.

    Mistral has released the weights of its trillion-parameter open-source model, Mistral Large 4 (ML4, nickname Le Chonk), which businesses and governments can obtain and deploy on their own via Hugging Face and API.

  13. The Decoder

    French Mistral releases 'Le Chonk,' which has strong coding capabilities but still lags behind Chinese models.

    Mistral has released its largest model, Mistral Large 4, which leads open-source competitors in coding tasks but still lags behind Chinese models in overall rankings. The model has approximately 100 billion parameters, with 52 billion parameters per step, requiring 8 Nvidia B300 GPUs to run.

Oct 29Thu
  1. ITHome · AI

    DiffuSpace releases open-source diffusion language model Clover-35B-A3B-Preview

    DiffuSpace has released an open-source diffusion language model Clover-35B-A3B-Preview, which adopts a MoE architecture and outperforms same-scale autoregressive models like Qwen3.6-35B-A3B in multiple benchmark tests, particularly excelling in agent programming and tool use tasks.

  2. Hugging Face Blog85

    Mistral Large 4 (Le Chonk) released on Hugging Face

    Mistral releases multimodal MoE model Mistral Large 4 (Le Chonk), with approximately 1T total parameters, 49B activation parameters, a context window of 1M tokens, offering two official versions FP8 and NVFP4, as well as GGUF made by Unsloth and llama.cpp teams.

    Why it matters: The original text provides specific scores for the 1T total parameter, 49B activation multimodal MoE model on cybersecurity and coding benchmarks, along with measured throughput for local and endpoint deployment.

  3. Mistral AI82

    Mistral releases open-source model Mistral Large 4 (Le Chonk) with trillion parameters

    Mistral releases open-weight version of its flagship trillion-parameter native multimodal model Mistral Large 4 (Le Chonk), which has been in public preview for three weeks.

    Why it matters: The official provides data on the encoding, security, and inference efficiency of the trillion-parameter open-source model, as well as weight downloads and self-hosting paths.

  4. ITHome · AI42

    XHEART NewCore Journey releases the intelligent driving large model chip X7 Ultra: 700 TOPS large model computing power, first in China to mass-produce Armv9 automotive-grade CPUs.

    XHEART NewCore Journey releases the X7 Ultra large model chip, achieving 700 TOPS of computing power, with mass-produced models achieving 99.99% alignment, a 80% reduction in memory bandwidth consumption, and a 100% improvement in energy efficiency. The chip incorporates a high-precision operator acceleration engine, natively supporting FP16/FP32 computing, and is the first in China to mass-produce Armv9 automotive-grade CPUs, offering a 20% performance boost and a 10% improvement in energy efficiency.

  5. ITHome · AI78

    NVIDIA open-sourced the speech transcription model Nemotron 3.5 Transcribe, supporting 40 languages and 8 speaker separation.

    NVIDIA launched the open-weight speech transcription model Nemotron 3.5 Transcribe on October 28, integrating transcription, speaker attribution, translation, and audio Q&A, using the MoE architecture, with total parameters of about 34 billion and activation parameters of about 4.3 billion, capable of processing the longest recording of 1 hour, supporting transcription of 40 languages, and distinguishing up to 8 speakers.

    Why it matters: NVIDIA open-sourced the speech transcription model, disclosing parameter scale, multilingual and speaker separation capabilities, and benchmark results, allowing comparison with existing open-source ASR solutions.

  6. QbitAI

    Diffusion Intelligence releases Clover-35B-A3B-Preview, a 350 billion parameter model that is twice as fast as Jev.

    Diffusion Intelligence releases Clover-35B-A3B-Preview model, with 350 billion parameters achieving a median execution time of 1.52 seconds in the web Agent evaluation WindTunnel, twice as fast as the Jev+Mercury 2.5 combination, with a success rate of 98.6%. The model adopts a MoE architecture, supports thinking mode, and scores 73.6 on SWE-bench Verified.

  7. Latent Space82

    Gemini 4 Carbon topped multiple lists and was the first to be opened to cybersecurity defenders.

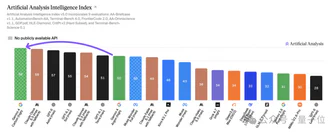
    Google DeepMind released Gemini 4 Carbon, only two weeks after Argon, claiming to achieve SOTA in cybersecurity and long-period tasks, ranking first with a score of 59 on the Artificial Analysis Intelligence Index v5.

    Why it matters: Summarizes the positions and pricing of Gemini 4 Carbon on multiple independent lists, and lists the gaps in coding, hallucination rate, etc., compared to competitors.

  8. MarkTechPost71

    NVIDIA released the open-source speech model Nemotron 3.5 Transcribe, supporting transcription of 40 languages.

    NVIDIA releases Nemotron 3.5 Transcribe, an open-weight speech large model supporting 40 languages, up to 1 hour of audio, and capable of outputting verbatim transcripts, written text, speaker annotations, and translation results.

  9. ITHome · AI

    Tencent Mixuan Hy4, Hy4 flash AI model to be released soon, introducing visual understanding capabilities for the first time

    Tencent announces the upcoming release of the Hunyuan Hy4, which offers a comprehensive upgrade compared to the Hy4 preview, introducing visual understanding capabilities for the first time, and enhancing long-range and productivity tasks; the Hy4 flash AI model will also be launched, providing excellent cost performance, inheriting the visual and Agent capabilities of Hy4.

  10. 36Kr · AI

    Google launches the Gemini 4 Carbon cutting-edge AI model

    Google has released the new front-end AI model Gemini 4 Carbon, used for maintaining cybersecurity defenses and handling complex engineering problems. It can handle long-process AI agent tasks, generate secure code, and reduce the proportion of model inaccuracy and fabricated information.

  11. The Verge · AI

    Google releases Gemini 4 Carbon, achieving a 'major leap' in cybersecurity capabilities

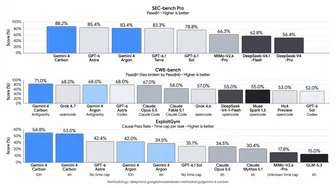
    Google has released its latest large model, Gemini 4 Carbon, achieving 'significant improvements' in coding, agent tasks, and network security. The model ranked first in the AI Analysis Index (v5.0) benchmark test and performed excellently in the SEC-bench Pro and ExploitGym evaluations.

  12. ITHome · AI85

    Google has released Gemini 4 Carbon, focusing on cybersecurity and topping the Artificial Analysis Intelligence Index.

    Google has officially released the next-generation cutting-edge large model Gemini 4 Carbon, featuring top-tier cybersecurity capabilities and long-range task processing, ranking first with a score of 59 in the Artificial Analysis Intelligence Index v5.0.

  13. MarkTechPost80

    Google DeepMind released Gemini 4 Carbon, emphasizing network security defense and coding.

    Google DeepMind has launched Gemini 4 Carbon, describing it as a cutting-edge model for long-period intelligent agent coding and cybersecurity defense, ranking first with 59 points on the Artificial Analysis Intelligence Index v5.0.

  14. Ars Technica · AI65

    Google has released Gemini 4 Carbon: a cutting-edge AI model that cannot be used immediately.

    Google has released Gemini 4 Carbon, reaching new thresholds in coding, agent tasks, and scientific analysis, but it has not yet been made available for use. The model significantly enhances vulnerability detection, validation, and repair capabilities in cybersecurity applications, with a 200% higher probability of generating bug-free code compared to Argon and a 10 times greater ability to generate high-quality patches compared to non-Google models.

  15. Artificial Analysis Articles85

    Gemini 4 Carbon topped the Artificial Analysis Intelligence Index v5

    Google's Gemini 4 Carbon ranked first with 59 points on the Artificial Analysis Intelligence Index v5, leading in four out of nine evaluation items: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, and AutomationBench-AA

  16. Google DeepMind82

    Google DeepMind releases the Gemini 4 Carbon cutting-edge model

    Google DeepMind releases the Gemini 4 Carbon, claiming it has the strongest capabilities in cybersecurity and long-term tasks, ranking first with a score of 59 in the Artificial Analysis Intelligence Index v5.0

Oct 28Wed
  1. The Decoder71

    Nvidia releases open-source speech model Nemotron 3.5 Transcribe, integrating transcription, translation, and speaker recognition

    Nvidia releases open-source speech recognition model Nemotron 3.5 Transcribe, supporting transcription in 40 languages, translation between 31 languages and English, and speaker recognition in 13 languages, capable of processing recordings up to 1 hour long with a maximum of 8 people.