Skip to content
Live
Nov 5Thu
  1. Mastra Blog

    Mastra introduces the Knowledge feature to provide agents with corporate context

    Mastra introduces the Knowledge feature, allowing agents to use corporate documents, policies, or decisions as a shared knowledge base for page organization. This feature interacts directly with Mastra's context engineering primitives via signals, supporting agents in obtaining and updating knowledge at runtime. Agents can search, read, and write Knowledge within their authorized scope using tools. Currently in alpha version, and the API may change.


  2. O'Reilly Radar65

    How to Measure AI's Impact on Delivery Speed

    Does AI make software development faster? Delivery speed is not productivity, but the ratio of value output to cost. Since software deliverables are not standardized, metrics like lines of code and PR numbers are unreliable, and estimations are inaccurate. Measuring delivery speed requires comparing a team's performance before and after. Through randomized controlled trials, alternating between tasks using AI and tasks not using AI can reduce interference from other process improvements, thus more accurately assessing the actual impact of AI on delivery speed.

Nov 4Wed
  1. Together AI Blog

    Together Compiler: A continuous compiler for AI inference

    Together Compiler (TKCC) achieves continuous optimization of AI inference workloads through high-throughput agents, reducing the latency of cutting-edge open-source models (Kimi K3, GLM 5.3) within 24 hours.

    Same story · 2 outlets

    How the accounts differ:Together AI Blog mentions models Kimi K3 and GLM 5.3; MarkTechPost mentions SemiAnalysis InferenceX AgentX.

  2. a16z News65

    Phaze launches a high-performance remote desktop solution to assist AI agents

    Phaze provides a local workstation experience for AI agents, especially suitable for interactive, low-latency tasks like Blender or Unreal Studio. It is designed specifically for AI agents, achieving seamless compatibility, management, and operation. The Phaze team previously created Parsec, a leading remote desktop for graphics-intensive applications, which has been acquired by Unity.

  3. Together AI Blog75

    Together AI has released Together Compiler, continuously compiling and optimizing AI inference.

    Together AI has released Together Compiler (TKCC), which uses high-throughput intelligent agents to continuously generate optimization solutions for inference engines, achieving 1.3-3x TPS improvements on cutting-edge open-source models like Kimi K3, GLM 5.3, MiniMax M3.1-Flash, and DeepSeek v4.1-Flash within 24 hours.

    Same story · 2 outlets

    How the accounts differ:Together AI Blog mentions models Kimi K3 and GLM 5.3; MarkTechPost mentions SemiAnalysis InferenceX AgentX.

    Why it matters: The original text provides a comparison of throughput improvements and engine startup time on multiple cutting-edge models, allowing for an assessment of changes in the inference optimization process.

  4. QbitAI58

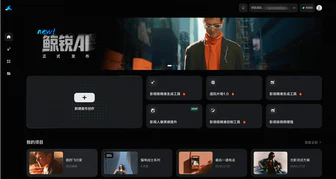
    Orca Culture's 'Jingrui AI' platform officially launched, saving more than 30% in AI video costs per minute

    Orca Culture Group's 'Jingrui AI', the industry's first AI film production and management platform, officially launched, integrating over 50 mainstream AI video generation models and over 10 self-developed models, saving more than 30% in AI video costs per minute compared to traditional methods through precise control and process optimization. The platform's official website (www.jingruiai.cn) opens for full registration, team seats unlimited in number, no membership subscription required.

  5. ITHome · AI65

    Netflix launches AI Discover tab to recommend movie and TV content based on user mood

    Netflix introduces the AI Discover tab, recommending movie and TV content based on user mood and preferences. Users can choose themes like 'Relaxing time' or 'Spooky me,' and the system learns and adjusts recommendations in real-time. This feature is currently rolling out in the US, initially available to English-language Netflix users.

  6. ITHome · AI58

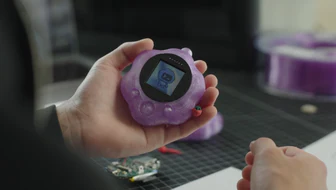
    OpenAI showcased the hardware results of its employees' 'side hustle': GPT-6 Astra assisted in producing designs in a week and prototypes in a month.

    Two employees of OpenAI used their spare time to complete a test device design with GPT-6 Astra in less than a week. The model handled the appearance, casing, circuit board, and firmware generation, and the contract manufacturer then produced the prototype in less than a month. OpenAI partnered with Mazda to use Astra for automotive design and simulation evaluation, exploring solutions for styling, performance, and cost optimization.

  7. 36Kr · AI67

    AMD Su Tseng-Feng: Helios Rack-Scale AI System Volume Delivery in the Fourth Quarter

    AMD Chairman Su Tseng-Feng expects the deployment of Helios Rack-Scale AI Systems to significantly increase in the fourth quarter, with OEM partners like Lenovo, HPE, and Dell beginning deliveries. The first Helios cabinets for customers like Anthropic and Meta have already been put into operation, and the scale of deployment is expected to expand further in the fourth quarter.

  8. MarkTechPost65

    Soniox STT v6 released: Adds intelligent agent text input and echo cancellation features

    Soniox STT v6 is its latest version of the speech-to-text API, which reads agent speech and analyzes its text content in real-time to achieve more accurate dialogue recognition and echo cancellation. The model supports over 60 languages, offering stt-rt-v6 (streaming) and stt-async-v6 (file) versions, running on the Soniox cloud API (only WebSocket streaming and asynchronous REST), with no self-hosting or device-side options.

  9. OpenHands Blog71

    OpenHands and Snowflake introduce a workflow for training models using their own Agent harness

    OpenHands partnered with Snowflake AI Research, allowing developers to directly use the existing OpenHands Agent harness for reinforcement learning and training without rebuilding the harness in the training framework.

    Why it matters: The original text provides specific configuration methods and code locations for directly using the existing Agent harness for RL training, allowing readers to judge whether training and deployment can share a single harness.

  10. Cohere Blog

    Cohere integrates third-party open-source models into the Model Vault, providing fully controlled AI model services.

    Cohere has integrated third-party open-source models into Model Vault and Model Vault Encrypted, allowing enterprises to run Cohere models and mainstream open-source models like DeepSeek V4.1 Flash and GLM 5.3 Flash on a controlled and encrypted inference platform, with default implementation of zero-shot prompting and output data retention.

  11. TechCrunch · AI65

    Netflix's newly introduced AI Discovery label helps users find content based on their mood

    Netflix introduces a new 'AI Discovery' label, its first experimental feature allows users to get recommendations based on their current mood. Users can choose from themes like 'Relaxing Moments', 'Thrillers', 'Family Movie Night', etc., based on mood, viewing preferences, available time, or trending topics. This feature is driven by Netflix's newly built smart layer, which responds to user feedback in real-time and continuously learns, aiming to improve the usability of the content library and shift towards a more personalized AI-powered experience.

  12. ITHome · AI42

    NVIDIA claims AI is reshaping chip factories: simulation speeds up to 35 times, reducing engineer decision time from days to minutes.

    NVIDIA claims AI is driving semiconductor foundries into the 'AI-defined factory' phase, accelerating simulation technology to compress engineering simulation from hours and days to just minutes. Applied Materials' Ginestra platform's shape simulation accelerates up to 35 times, reducing engineer decision time from days to minutes.

  13. Meta Engineering34

    Meta launches F3 Lightning to accelerate the large-scale production of advertising ML features

    Meta launches F3 Lightning to address bottlenecks in F3 graph publishing by decoupling feature publishing from execution, enabling independent validation deployment. It adopts optimizations such as stable compute identifiers, a single execution plan, shared memory buffers, and dense index mapping, making the production speed of extraction features approximately 3.6 times faster than F3 without increasing infrastructure compute costs.

  14. AWS Machine Learning Blog38

    How does Cartesia build ultra-low latency speech AI applications on AWS?

    Cartesia uses state space models (SSM) designed for real-time speech AI and AWS infrastructure to achieve sub-100ms text-to-speech and speech-to-text, supporting voice cloning for 44 languages, suitable for scenarios such as virtual assistants and customer service centers. The Sonic model generates the first audio byte in about 90ms, and the Ink model has native turn detection and noise robustness. The API interface supports real-time streaming output.

  15. AWS Machine Learning Blog32

    Amazon Quick integrates structured and unstructured data.

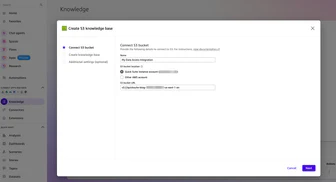
    Amazon Quick integrates structured and unstructured data by connecting Amazon S3 and creating a knowledge base, enabling users to query with a single conversational AI agent. This solution includes a data layer (unstructured content stored in S3 and structured data as semantic datasets), a workspace layer (integrating data types into a single workspace), and an agent layer (custom chat agents linked to the workspace and returning combined responses).

  16. NVIDIA Newsroom38

    How AI is reshaping the work of semiconductor wafer factories - engineers accelerating decision-making due to it

    AI is changing the way semiconductor wafer factories work, accelerating decision-making for engineers. NVIDIA's cuDSS library accelerates COMSOL's multiphysics simulation 10 times, Applied Materials' Ginestra platform simulation 10 times, ACE+ platform 35 times, and Siemens' Calibre lithography software simulation 17 times. NVIDIA's PhysicsNeMo framework enables Lam Research to predict plasma behavior at the millisecond level, replacing full simulations that took days.

    Same story · 2 outlets

    How the accounts differ:NVIDIA Blog states ZEISS SMT achieved a 4x speedup with COMSOL for EUV lithography plasma simulation; NVIDIA Newsroom mentions a 10x speedup for COMSOL with cuDSS.

Nov 3Tue
  1. Hugging Face Daily Papers

    ReTrace framework: Revealing the recovery behavior of computer agents through goal-directed action replay

    The ReTrace framework restores standard formal transition consistency through goal-directed action replay and controlled error injection, systematically studying the recovery behavior of autonomous models of computer agents, discovering that ideal recovery unlocks the model's potential task-completion capabilities, finding that current agents do not fully utilize their potential recovery capabilities, and that accurate model recovery can bring measurable end-to-end gains, proving that recovery is a fundamental capability for building reliable computer agents.

  2. Hugging Face Daily Papers58

    CoworkOS: An Intelligent Agent Collaboration Framework for Real-world Automation

    CoworkOS enables human-machine collaboration and continuously improves model performance by separating strategies from execution, driving human-machine collaboration towards real-world automation. The framework performs excellently in 12 benchmarks and 6 categories of real-world applications, using GLM-5.3 as the core, and performs RSI-driven automatic post-training on Qwen3.6-35B-A3B, increasing the average score on 8 benchmarks from 33.19 to 42.95.

  3. TechCrunch · AI65

    Apple Watch's AI feature 'Audio Intelligence' has started Beta testing

    Apple Watch's AI-driven 'Audio Intelligence' technology has started beta testing, initially including four optional features: detecting important sounds, identifying songs, replaying dialogue snippets, and generating dialogue summaries. The replay feature allows users to review the last 15 seconds of a conversation, while Siri Recaps can summarize key points of the conversation without recording the original audio or identifying the speaker.