Live
#Engineering
ITHome · AI ITHome · AISame story · 2 outlets Apple has launched a $50 AI usage pack: Logic Pro is the first to support paid expansion, valid for 12 months.
Apple is introducing a paid 'Smart Usage Pack' for some Apple Intelligence features. The first product to adopt this is Logic Pro, priced at $49.99, valid for 12 months, with unused additional amounts that can be carried over monthly. This usage pack does not support 'Family Sharing' and is only usable with the iCloud Apple account used at the time of purchase.
 Browser Use
Integrating 1Password with Browser Use for automatic password filling and TOTP codes
1Password connects to Browser Use via a service account, enabling automatic password filling and TOTP code completion for web tasks. Create a dedicated password vault and configure read-only permissions for the service account. After connecting with a Browser Use token, running login tasks can verify the authentication page. The integration requires an active 1Password connection for each project, distinguishing between service account tokens, vault IDs, and Browser Use API keys.
 OpenAI News
CodeRabbit uses OpenAI models to improve governance and trust in AI-generated code, achieving a 20-fold increase in software delivery volume for engineering teams
CodeRabbit uses OpenAI models to govern and trust AI-generated code, combining Codex to increase the software delivery volume of engineering teams by 20 times.
 The Verge · AISame story · 2 outlets6565
Apple offers a one-time purchase option of $49.99 to extend the use of AI features in Logic Pro
Apple offers a one-time purchase option of $49.99 to extend the use of AI features in Logic Pro, which allows users to continue using Apple Intelligence features limited by reliance on OpenAI or Google Gemini cloud AI models.
 Hugging Face Daily Papers
Confucius4-R2T2: A stable prefix streaming speech recognition model for real-time transcription
Confucius4-R2T2 is a stable prefix streaming speech recognition model for real-time applications, which converts a full context ASR model into a streaming model through post-training without architecture modification. Built based on Qwen3-ASR-1.7B, R2T2 achieves near-offline recognition accuracy and low transmission delay, supports configurable streaming block sizes, and demonstrates promising cross-lingual generalization capabilities. This model and implementation have been publicly released.
 Google Developers Blog5858
Google Cloud MaxText supports long-context training on TPUs
Google Cloud releases MaxText v0.2.4, supporting long-context training on TPUs, achieving 70% MFU for sequences of 4 million tokens with the Llama 3.1 8B model on TPU 5p using MaxText Context Parallelism technology, seamlessly scalable to 14 million tokens on TPU 5p and TPU 7
 NVIDIA Technical Blog6565
NVIDIA Holoscan 5 achieves the sense of weightlessness for robotic arms
NVIDIA Holoscan 5 achieves gravity compensation through continuous inverse dynamics calculation, allowing robotic arms to only provide torque to support their weight during operation. This technology supports robotic applications through teaching, object manipulation, or human-robot collaboration, relying on gravity compensation loops.
 MarkTechPost6767
Baidu ERNIE Evolve Automated Research System Surpasses NanoChat and NanoGPT Records
Baidu Launches ERNIE Evolve Automated Research System, Automatically Selects Research Directions, Edits Code, and Runs Experiments Based on Given Codebases, Goals, and Evaluation Criteria, Retaining Only Changes Validated by Hidden Evaluators and Independent Reviewers
- MarkTechPostSame story · 4 outlets6767
Google has launched the TPU 8i Max and TPU 8tx: a dual-chip TPU and a confidential TPU
Google releases TPU 8i Max and TPU 8tx, TPU 8i Max integrates 2 TPU 8i chips into 1 package, doubling performance; TPU 8tx uses TPU 8t chips paired with the 5th generation AMD EPYC host to achieve confidential inference, reducing latency by 2 times.
Same story · 4 outlets- ITHome · AI · Google expands its TPU chip lineup with the launch of two new products, 8tx/8i Max, to challenge NVIDIAFirst
- The Decoder · Google launched four TPU variants within a year, intensifying competition with NVIDIA
- TechCrunch · AI · Google releases two new TPU chips to expand AI hardware portfolio
How the accounts differ:MarkTechPost states TPU 8tx uses TPU 8t chips paired with 5th gen AMD EPYC, while TechCrunch mentions it was co-developed with AMD for secret training and running AI models with direct hardware security integration.
 Databricks Blog2222
Sendoso gifts through Genie One converted into a sales pipeline
Sendoso converts buying signals into a sales pipeline via Genie One AI agent without exporting lists or logging into other tools. The MCP server on Databricks Marketplace integrates Sendoso functionality into existing data environments, AI suggests gifts, researches recipients, and drafts notes, supporting direct display of data and reasons in Genie One.
- Databricks Blog4040
Databricks releases UCDataset, accelerating GPU training by directly accessing Unity Catalog tables
Databricks releases Unity Catalog Dataset (UCDataset) Beta version, reducing the average training time for recommended model workloads by 10 times by streaming Unity Catalog table data directly from cloud storage to each GPU in training jobs



QbitAIFeatured7272 Baidu Wenxin has first disclosed the progress of RSI, and ERNIE Evolve has been used in the development of Wenxin 5.5 Flash.
Baidu Wenxin first disclosed its automatic research system ERNIE Evolve, which can autonomously propose research directions, conduct experiments, and validate results. It has been used for inference optimization in Wenxin 5.5 Flash. In the low-latency scenario optimization for Kunlun Chip P800, ERNIE Evolve took about 168 hours and went through 4 rounds of direction exploration, with the optimal version's generation speed increasing to 623.6% of the baseline. The deterministic reasoning throughput optimization increased the throughput to 133.7% of the baseline in 3 days.
Why it matters: Baidu has disclosed the architecture and production environment optimization data of the automatic research system ERNIE Evolve, which can observe the actual landing points of RSI in inference optimization.
 NVIDIA NewsroomFeatured7878
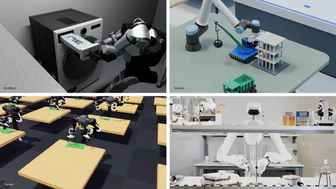
NVIDIA released the GR00T 2 world action model and Isaac Lab 3.0 on CoRL.
NVIDIA released the open-source world action model GR00T 2 on CoRL, built on NVIDIA Cosmos, trained with 100,000 hours of NVIDIA open-source first-person human data, and can complete 40 out of 50 evaluation tasks without task-specific demonstrations.
Why it matters: The original text provides the success rate of GR00T 2 on few-shot tasks and the training throughput improvement of Isaac Lab 3.0, which can be used to judge the extent to which simulation training promotes robot deployment.
 The DecoderSame story · 4 outlets5858
Google launched four TPU variants within a year, intensifying competition with NVIDIA
Google released two new systems, TPU 8tx and TPU 8i Max, targeting confidential computing and high-memory demand applications, delivering a total of four TPU systems within the year. The new systems are based on existing chips, achieving rapid iteration through different packaging, networking, and memory configurations. Data in TPU 8tx remains encrypted during processing, while TPU 8i Max doubles computing power, memory, and bandwidth within a single rack, significantly improving data center performance per square meter.
Same story · 4 outlets- ITHome · AI · Google expands its TPU chip lineup with the launch of two new products, 8tx/8i Max, to challenge NVIDIAFirst
- MarkTechPost · Google has launched the TPU 8i Max and TPU 8tx: a dual-chip TPU and a confidential TPU
- TechCrunch · AI · Google releases two new TPU chips to expand AI hardware portfolio
How the accounts differ:MarkTechPost states TPU 8tx uses TPU 8t chips paired with 5th gen AMD EPYC, while TechCrunch mentions it was co-developed with AMD for secret training and running AI models with direct hardware security integration.
ITHome · AISame story · 4 outlets6767 Google expands its TPU chip lineup with the launch of two new products, 8tx/8i Max, to challenge NVIDIA
Google launches two new products, TPU 8tx and TPU 8i Max, targeting confidential computing and ultra-long context window AI applications, aiming to challenge NVIDIA's position in the AI chip market. TPU 8tx works with AMD chips, TPU 8i Max integrates two chips to provide stronger computing power. Both products are expected to launch next year.
Same story · 4 outlets- The Decoder · Google launched four TPU variants within a year, intensifying competition with NVIDIA
- MarkTechPost · Google has launched the TPU 8i Max and TPU 8tx: a dual-chip TPU and a confidential TPU
- TechCrunch · AI · Google releases two new TPU chips to expand AI hardware portfolio
How the accounts differ:MarkTechPost states TPU 8tx uses TPU 8t chips paired with 5th gen AMD EPYC, while TechCrunch mentions it was co-developed with AMD for secret training and running AI models with direct hardware security integration.
- Google Developers BlogFeatured6565
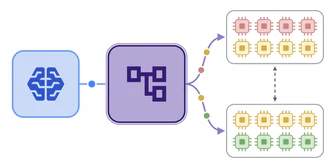
Google details Pathways: a single controller training system for large models.
Google announces Pathways is now generally available on Google Cloud Platform, which is Google's distributed system used to train its own large models like Gemini.
Why it matters: Google engineers explain the single controller execution model of Pathways and provide a layered difference with Ray for judging the selection of large-scale training orchestration.
- MarkTechPost5858
Reason Machines has open-sourced Aspen, a Git server designed for AI agents.
Reason Machines has released an open-source Git server, Aspen, designed for handling repositories with hundreds of AI agents pushing simultaneously. It independently implements the design of OpenAI Pando, with a single 8-core server capable of sustaining 567 pushes per second, and a p99 push latency of 314 milliseconds.
ITHome · AI6565 Mingfán T5 Max-388 Compact Desktop PC Released: Onboard 48GB LPDDR5-6400 Memory
Mingfeng has launched the T5 Max-388 compact desktop PC, equipped with the AMD Ryzen AI Max+ 388 processor, featuring onboard 48GB LPDDR5-6400 memory, a phase change TIM + 6 fan cooling system, providing 2 M.2 2280 (PCIe Gen4 x4) interfaces and 1TB storage, priced at $1,559 / HK$11,999 upon delivery.
Hacker News · AI hot posts6565 How do I cope with AI job fatigue brought by Claude Code and Codex?
When working with Claude Code or Codex from the terminal, users often experience mental exhaustion due to multi-threaded task processing. The author manages tasks in git by organizing work in a way similar to a priority queue, with each task being a markdown file and its status as a git snapshot. The AI agent processes new tasks in a loop, runs tests, and performs browser checks, but cannot make decisions and requires the user to handle them in the 'Owner Inbox' by viewing tasks with the Claude tool on a single page, closing them after completion to process one task at a time.
- NVIDIA Newsroom3232
NVIDIA has released an optimized deployment solution for South Korea's leading open-source models, Dynamo.
NVIDIA has released an optimized deployment solution for South Korea's leading open-source models, Dynamo, supporting SK Telecom A.X K2, LG AI Research K-EXAONE 2.0, Upstage Solar Open 2, and Motif Technologies Motif-3, achieving up to 2x performance improvement through optimized multi-GPU coordination and communication, accelerating model production deployment.
Hacker News · 300+Featured7878 llama-modchip enables the 284B DeepSeek-V4-Flash to run on a 64GB memory without GPU
llama-modchip releases a set of ggml/llama.cpp core patches and quantization transcoding tools, compressing the 284.33B DeepSeek-V4-Flash to 56.56 GiB (1.71 bpw), which can run on a pure CPU machine with 64 GB memory, with a peak memory of 57.61 GiB under 256K context and no need for swap.
Why it matters: The project provides a quantization scheme and core patches for running 284B MoE on 64 GB memory, along with measured data for each hardware, which can be used to determine the feasible boundary for pure CPU deployment.

- MarkTechPost6262
Google AI open-sources Elephant-Goldfish Model Plugin for writing specifications before writing code
Google AI open-sources the Elephant-Goldfish Model (EGM) Plugin, enabling AI coding agents to write specifications before writing code. The plugin includes 7 skills, 9 reviewer roles, and 6 brainstorming lenses, enforcing independent specification reviews through 5 zero-context review stages.
 OpenAI Agents SDK releases2222
OpenAI Agents SDK v0.24.0-alpha.7 released
OpenAI Agents SDK v0.24.0-alpha.7 released, supports classic workflows and native execution, adds voice and managed tools, introduces persistent session storage and context control. The new version defaults to strict mode execution, requiring updates to existing environments; bundled model default inference strength is increased to medium.
QbitAIFeatured7272 Why it matters: Starting from GitHub outages, this connects the motivations and actions of OpenAI, Cursor, and Anthropic in building their own code infrastructure, revealing the actual pressure AI coding puts on the development tool chain.
 vLLM Blog3838
vLLM migrates to LibTorch Stable ABI
vLLM releases LibTorch ABI Stable CUDA since v0.33.0, allowing PyTorch upgrade without rebuilding.
Hacker News · 300+6060 A Jev that can request Opus for help allows Opus to achieve accuracy at 4x lower cost
The Jev and Luna models perform decently in identity resolution result scoring (88.8–97.3% accuracy), but the Jev+Opus hybrid model achieves state-of-the-art accuracy while reducing cost by 4x. Luna initially performs better than Jev, but the gap disappears in complex cases; Jev has better confidence calibration, with its errors often accompanied by low confidence, while Luna's errors are often accompanied by high confidence.
QbitAI4242 PPIO Sandbox: Equip Personal Agent with a dedicated 'cloud computer'.
Personal Agent is user-centric and needs to support long-term operation and proactive advancement, therefore it must be equipped with a dedicated 'cloud computer'. Current mainstream solutions include local operation (involves security risks and offline issues) and cloud operation (self-built by large companies or third-party hosting). PPIO Sandbox provides a ready-to-use, secure isolation, supports long-term operation and large-scale users cloud execution environment as an API for developers to use, helping to develop Agents for scenarios such as personal office, research, and programming assistants.
ITHome · AI5858 Planet AI app released: Combining large language models with ten years of satellite imagery, allowing users to naturally query Earth's changes
Planet AI app launched, users can naturally search, observe, and analyze changes in Earth's surface over ten years; currently free to use, AI conclusions are based on viewable raw satellite imagery; supports three core capabilities: 'Search Earth', 'Explore Changes', 'In-depth Analysis', and has been used in ecological conservation, land management, etc.
ITHome · AI6262 AI programming tool Amp launches Spaces: Your AI project manager is online, autonomously arranging / coordinating Agent tasks
Amp introduces the Spaces feature, where the main Agent can automatically generate and coordinate multiple parallel Agent threads to complete projects. Each Space allows teams to plan, execute, and track tasks within a single chat, with the main Agent responsible for goal decomposition and progress organization, while developers only need to define goals and review results.
ITHome · AISame story · 2 outlets6060 Cursor launches real-time voice chat functionality, ushering AI programming into the 'call era'
Cursor launches the 'Real-time Voice Chat with Agents' feature, supporting developers in two-way voice conversations with coding agents to describe code modification requirements, inquire about task progress, etc., while the agents complete coding work in the background. This feature is used in Cursor's Agents Window, IDE, web version, and iOS app, driven by Grok Voice for speech recognition and synthesis, offering multiple voice options like Ara, Eve, and supporting switching during calls.
Same story · 2 outlets- Databricks Blog3838
OpenSharing: Replace SFTP and API data feeds with an open protocol
OpenSharing is an open protocol developed based on Delta Lake and Iceberg, used for directly reading customer tables without copying data. It supports incremental pull of change data, real-time access to the latest data, and smooth backfill of historical data, while reducing costs for customers and consumers in data management, storage, and access control. Consumers do not need to maintain SFTP or API connections; customers can share tables with authorization and can track access records through system tables.
- Databricks Blog2222
Databricks uses OpenSharing to replace file streaming (how it's achieved)
Databricks exposes shared Delta tables as real-time data sources through OpenSharing, allowing recipients to read incremental changes using Structured Streaming without local file tracking.
 GitHub Blog · AI & ML3838
How GitHub Copilot uses canvases to build interactive experiences
GitHub Copilot supports cross-device session continuity on canvases, allowing users to execute tasks in cloud sandboxes, isolate repository editing through the Copilot app, enhance efficiency with storage instructions and shared memory project knowledge, and optionally match work requirements with the Copilot Fusion model.