Skip to content
Live
Nov 5Thu
  1. Hugging Face Daily Papers38

    D3D: Decoupled Diffusion Drafting Asynchronous Speculative Decoding Technology

    D3D breaks the dependency on the hidden states of the target model through an independent diffuser, achieving asynchronous drafting and verification. In seven benchmarks, D3D combined with block denoising and auxiliary autoregressive supervision increases the average decoding speed of Qwen3-8B and Qwen3-32B by 5.00 times and 5.71 times respectively, outperforming DFlash (4.03 times and 3.67 times), and reaching 7.48 times acceleration on GSM8K. The code, model checkpoints, and benchmark scripts are open source.

  2. ITHome · AI62

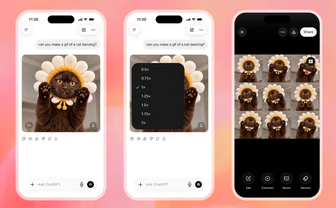
    OpenAI has launched the Images 2.6 model, and ChatGPT now supports direct generation and editing of GIF animations.

    ChatGPT now supports direct generation and editing of GIF animations, this update was launched in sync with OpenAI's Images 2.6 model, allowing users to adjust the speed of GIF animations and edit individual frames. Over 4 billion images are generated weekly through ChatGPT and its API.

  3. 36Kr · AI67

    OpenAI launched Images 2.6, with a 50% increase in image generation speed, and added GIF generation functionality

    OpenAI has released the image generation model Images 2.6, which is now open to global users. Image generation speed is 50% faster than the previous version, with a new GIF generation feature added. This model supports use in ChatGPT, Codex, and API. The Flare version can generate images in 6 seconds under low-quality settings.

  4. Epoch AI65

    Epoch Capabilities Index update adopts Bayesian model methodology

    Epoch Capabilities Index (ECI) update adopts Bayesian model methodology, providing more reliable estimates of model capability uncertainty and the probability of comparing capabilities between models. The new method is based on four-parameter logistic (4PL) item response theory (IRT), using Claude 3.5 Sonnet (ECI 130) and GPT-5 (ECI 150) as anchor models, and achieves cross-temporal consistency through linear transformations to fix parameter location and scale.

  5. The Decoder71

    ChatGPT supports generating dynamic GIFs based on the OpenAI Images 2.6 model.

    ChatGPT now supports generating dynamic GIFs, this feature is based on OpenAI's new Images 2.6 model, and is being pushed to all ChatGPT and Codex users on web, desktop, and mobile platforms.

    Why it matters: ChatGPT has added GIF generation capabilities, allowing readers to understand the progress of image models in cross-frame consistency and API variant divisions.

  6. Google Research

    Agile Deliberation: How AI Assists Humans in Defining Subjective Concept Boundaries

    The Agile Deliberation framework assists humans in defining the boundaries of subjective concepts through iterative dialogue, transforming fuzzy ideas into precise AI instruction blueprints. The framework is divided into two stages: concept definition and concept iteration, which processes fuzzy images through direct feedback. In 18 user experiments of 1.5 hours each, it significantly reduces user fatigue and anxiety, making AI model performance superior to standard baselines.

    Same story · 2 outlets

    How the accounts differ:Google Research mentions user experiments reducing fatigue and anxiety; MarkTechPost focuses on F1 score improvements.

  7. The Verge · AI

    ChatGPT can now generate animated GIFs

    ChatGPT can generate GIFs through prompts or uploaded photos, an update introduced alongside OpenAI's new Images 2.6 model, allowing adjustments to GIF animation speed, editing individual frames, and sharing. Previously, ChatGPT could not generate GIFs step-by-step. The Images 2.6 update also improves ChatGPT's image generation speed. Users generate over 4 billion images weekly on ChatGPT and its API, a significant increase from the 3 billion reported in September.

Nov 4Wed
  1. ITHome · AI58

    Xiaomi WorldCast 3D Camera Movement Launched on REDMI K100: Flat Photos Restored into 3D Scenes, and Real Camera Path Virtualized

    Xiaomi REDMI K100 Phone Adds 3D Camera Movement AI Feature, Select Static Photos from Album to Generate Wide-Angle 3D Camera Movement Videos, Lens Can Orbit, Pull, Tilt, and Keep Character Appearance Consistent. This Feature is Based on Xiaomi's Visual Generation Framework WorldCast, Interpreting Depth Structure of the Scene to Restore Flat Photos into 3D Scenes and Virtual Camera Path. Xiaomi Claims WorldCast is a Breakthrough in Controllable Visual Generation Direction, Will Explore More Complex Camera Movement Forms and 4D Video Generation Technology.

  2. Hugging Face Daily Papers65

    FactEmbed: Enhancing Composed Image Retrieval Performance through Decomposed Embeddings

    FactEmbed decouples query understanding from embedding construction, simulating pre-retrieval visual modifications using decomposed latent vectors, significantly improving performance in composed image retrieval. The method outperforms existing technologies in the CIR benchmark, optimizing decomposed representations through intermediate target imagination, and achieving efficient inference using global-level embeddings and mean pooling of latent vectors.

  3. ITHome · AI62

    XPeng, in collaboration with Peking University, Hong Kong University, and others, has released the GroundingPI pre-trained model, with its perception module scoring over GPT-6 Astra.

    The GroundingPI model jointly released by Xpeng, Peking University, Hong Kong University, etc., scored 73.68 in a comprehensive evaluation of 34 perception benchmarks, surpassing GPT-6 Astra's 71.54. The model, with a parameter size of about 4 billion, adopts a 'perception-first' technical approach, demonstrating higher data processing efficiency and stronger scene generalization capabilities in robotic simulation tasks, significantly reducing teaching costs while maintaining stability.

  4. MarkTechPost

    Tencent's WeVisOne-VL unifies detection, OCR, segmentation, and Matting.

    Tencent WeChat Vision team releases open-source visual language model WeVisOne-VL, including 2B and 4B parameter versions, supporting detection, OCR, segmentation, and Matting, using a 9.6M parameter decoder to output pixel results, surpassing same-scale baselines in over 30 benchmark tests, with the 4B version achieving a 71.3 F1 score on Dense200 dense detection.

    Same story · 2 outlets

    How the accounts differ:Hugging Face Daily Papers states it uses a lightweight pixel decoder; MarkTechPost mentions a 9.6M parameter decoder.

  5. Hugging Face Daily Papers65

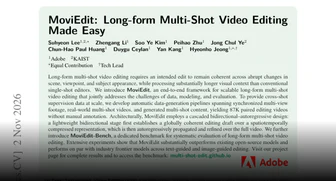
    MoviEdit: A framework for editing long-segment, multi-shot video

    MoviEdit framework, through cascaded bidirectional autoregressive modeling and new benchmark tests, maintains cross-scene coherence while reducing manual data annotation, significantly outperforming existing open-source models with performance comparable to industry leading models. The framework automatically generates 87K pairs of paired editing videos for cross-shot supervision, establishes a global editing draft using a lightweight bidirectional stage, and then performs autoregressive propagation and refinement.

  6. ITHome · AI65

    NetEase's 'Yanyun Shishisheng' to Officially Implement NVIDIA DLSS 5 on November 24

    NetEase's 'Yanyun Shishisheng' will officially implement NVIDIA DLSS 5 on November 24, becoming the first game in China to support this technology, with the North America region launching a day early. DLSS 5 is NVIDIA's new real-time neural rendering technology announced in March 2026, which takes game frames as input and uses AI models to generate realistic lighting and materials, supporting up to 4K resolution. This solution uses neural networks to real-time reconstruct complex lighting and material details, enhancing lighting and character texture while avoiding blurriness or loss of clarity.

Nov 3Tue
  1. Hugging Face Daily Papers

    Reviso: Not All Visual Evidence Should Be Given Equal Attention in Video Caption Generation

    Reviso is an intelligent video subtitle framework that prioritizes key visual evidence through hierarchical planning and active perception learning, enhancing subtitle quality and downstream video understanding capabilities. Multimodal large language models (MLLMs) generated video subtitles may overemphasize minor details while ignoring important context and key events.

  2. Hugging Face Daily Papers47

    uni-robot-agent: Open-source robot use agent unified framework achieves zero-shot operation breakthrough

    The uni-robot-agent framework enables open-source weight robots to surpass proprietary models using agents in zero-shot operation, with its onboard Qwen3.8-Flash-Next scoring 31.39 in the RoboDojo evaluation, exceeding GPT-6 Astra-RoboProbe's 28.97 score and numerous VLA/WAM baselines, and performing excellently in 19 real tasks. Analysis indicates that effective robot use requires combining four general capabilities, suggesting future training should synergistically develop these capabilities.

  3. Hugging Face Daily Papers65

    WeFair: Fidelity-Aware Alignment Technology Based on Human Feedback, Used for Personalized Query Rewriting in Short Video Search

    WeFair improves personalized query rewriting through a human feedback phase (demonstration, preference, and validation) based on fidelity perception, reducing intent drift and enhancing search effectiveness on short video platforms. This technology addresses the need for compact query rewriters in short video search, recovering user personalized intent from ambiguous queries under strict latency constraints. WeFair-2B outperforms strong rewriting baselines in overall accuracy and intent preservation in offline experiments, while online A/B testing shows a relative increase of 2.593% in effective video play rate and a relative decrease of 2.350% in query rewriting rate.

  4. Hugging Face Daily Papers34

    Venus-DefakerOne2: A broader visual forensics base model

    Venus-DefakerOne2 extends detection to multiple spoofing forms and media types through alternating LoRA and full-parameter fine-tuning, as well as entropy-based test adaptive, achieving SOTA performance in six benchmark tests including DeepFake faces (96.7%), AI-generated images (93.3%), and tampered documents (87.6%), significantly outperforming expert models and predecessor DefakerOne.

Nov 2Mon
  1. Import AI42

    Realtime-Bench released: Benchmark tests to evaluate the performance of LLMs on low-latency tasks

    Realtime-Bench benchmark tests evaluated the performance of LLMs on 50 real-time interactive games and web tasks, with GPT-6 Astra achieving a 36% pass rate under real-time clock conditions; this test was developed by institutions such as the University of Texas at Austin to measure the model's real-time state awareness, adaptive reasoning, and time-aware action selection capabilities.

  2. Hugging Face Daily Papers38

    LARC framework implements continuous space latent reasoning to unify multimodal models

    The LARC framework alleviates the bottleneck of applying linguistic reasoning in image generation for unified multimodal models by reasoning on continuous hidden states, improving generation quality and achieving test-time scaling without discrete token bottlenecks. The framework includes two stages: curriculum supervised fine-tuning (SFT) and information gain reinforcement learning (RL). In text-to-image generation benchmark tests, LARC improved performance by 7% over BAGEL on GenEval and demonstrated clear test-time scaling behavior.

  3. Hugging Face Daily Papers65

    HiFOR: A hierarchical predictive framework for visual language action models

    HiFOR guides action generation by hierarchically predicting future states and retrieving relevant future information, enhancing robotic manipulation capabilities. The framework jointly predicts short-term state evolution, semantic milestones, and final goal states through hierarchical dependency masks (HDM), establishing cross-temporal dependency relationships; structured perception latent world modeling organizes future potential representations along temporal, perspective, and spatial dimensions, promoting fine-grained retrieval; action-guided decomposition world retrieval adaptively retrieves relevant future information based on action representations during the denoising process, providing targeted guidance for action generation.

  4. ITHome · AI42

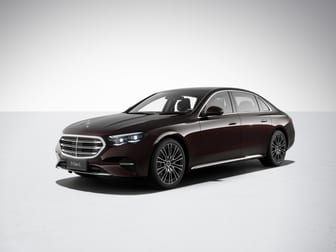
    The 2026 Mercedes-Benz E 300 L sedan has been launched: it is the first to feature an AI cockpit developed by a Chinese team.

    The 2026 Mercedes-Benz E 300 L sedan has been launched, with a recommended retail price ranging from 423,800 yuan to 509,800 yuan, with the starting price reduced by 16,000 yuan. This car is the first to feature a brand-new AI smart cockpit developed under the leadership of the Mercedes-Benz China R&D team, integrating the Doubao AI large model and supporting quarterly major version OTA updates.

  5. Moonshot AI · Hugging Face new models

    Kimi K3.1 Pro Released: Open-Weight Multimodal AI Model

    Kimi K3.1 Pro is an open-source multimodal AI model by Moonshot AI, with 2.8T parameters, 104B activation parameters, and a context window of 1M tokens, demonstrating excellent performance in areas such as coding, 3D creation, and financial research. Compared to Kimi K3, it adopts Gated DSA layers to improve long text processing efficiency and has outperformed competitors like Claude Fable 5.1 and GPT-6 Astra in benchmarks such as Terminal-Bench 4.0.

Nov 1Sun
Oct 31Sat
  1. ITHome · AI65

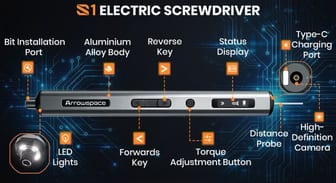
    Arrowmax in Hong Kong launched the AI Electric Screwdriver S1, claiming it to be the world's first.

    Arrowmax launched the AI Electric Screwdriver S1 on Kickstarter, claiming it to be the world's first, with a starting price of $80 and an estimated shipping date of April 2027. The S1 uses a camera and AI model to identify screw types and sizes, and automatically selects bits and adjusts torque, with all training samples collected in-house. The single unit starts at $80, and the kit has an early bird price starting at $129.

  2. The Decoder62

    Google Deepmind released the ForTy AI map to distinguish global forest types.

    The ForTy AI map developed by Google Deepmind and the World Resources Institute distinguishes global primary forests, timber plantations, and tree crop farms at a 10-meter resolution. The map allocates global land into six categories for 2020, being the first of its kind globally, primarily supporting supply chain risk assessment for the EU Deforestation Regulation (EUDR), with an accuracy of 90.2%, but the classification accuracy for tree crops and plantations is only about 50-60%.