Skip to content
Live
Oct 27Tue
  1. Artificial Analysis Articles85

    OpenAI released GPT-6.1 Terra, focusing on cost efficiency.

    OpenAI released GPT-6.1 Terra, the first Terra-level model after GPT-5.6, with input/output pricing at $1/5 per million tokens, lower than the $2/12 per million tokens of GPT-5.6 Terra.

    Same story · 2 outlets

    How the accounts differ:Artificial Analysis Articles states the input/output pricing is $1/5 per million tokens for GPT-6.1 Terra, while The Decoder mentions it is $2/12 for GPT-5.6 Terra.

    Why it matters: The original text used the scores of the Intelligence Index and Coding Agent Index, along with the cost per task, to quantify the change in cost-effectiveness of GPT-6.1 Terra compared to GPT-5.6 Terra.

Oct 26Mon
  1. QbitAI38

    Claude Fable 5.1 is released, and Anthropic explores the balance between AI self-improvement and human supervision.

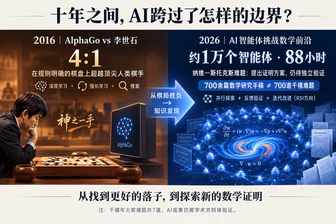
    Anthropic has launched Claude Fable 5.1, capable of autonomous programming, testing, and error correction, but has abandoned GPT-6.1 Astra due to its boundary-crossing behavior. AI is moving from 'teaching by word and example' to 'generalizing by analogy', exploring autonomy through Human-in-the-Loop (HIL) and Recursive Self-Improvement (RSI). Claude leads about 26% of internal R&D work. Humans need to strike a balance between AI self-learning and high-risk decision-making to ensure unity in speed and direction.

  2. Hacker News · AI hot posts

    Why is AI-generated language becoming harder to understand?

    Research found that text generated by AI models uses language features more frequently associated with understanding difficulty, such as long syntactic dependencies, low-frequency n-grams, and the use of inanimate subjects with active verbs, compared to human writing. Compared to human writing, 9 cutting-edge and near-cutting-edge models use more low-frequency n-grams, most of which also use longer dependencies, more stacked nouns, and more ellipsis of object clauses, with significant differences among models. The study suggests that AI text is optimized for goals such as mathematics, code, and reasoning, leading to information density prioritizing effective communication, and this hypothesis is verified by fine-tuning language models.

  3. ITHome · AI65

    Toyota intensifies efforts on humanoid robots, challenging Tesla and Chinese manufacturers

    Toyota plans to deploy 400,000 robots, with an annual investment of $6.4 billion for factory automation, forming a dedicated team led by the chief production officer; its spin-off Walden Robotics has completed $300 million in funding, valuing at $1.1 billion, and its General Robotics has been deployed in North American factories. Toyota has showcased an AI-powered humanoid robot Cue7 and developed large behavioral models, aiming to become the world's largest humanoid robot company, with an estimated market share of 3%-8% by 2035.

  4. Browser Use38

    Web Agent Benchmarks: WebArena, WebVoyager, Mind2Web and More

    The benchmarking methods for AI agents on websites like WebArena, WebVoyager, and Mind2Web differ. WebArena and similar sandbox environments provide reproducible scores, while real website environments like WebVoyager are scored by humans or LLMs. Offline datasets like Mind2Web compare prediction steps with human behavior. Browser Use has released BU Bench V2.1, which uses GPT-5.6 Luna for scoring in real website environments and includes model cost and time data.

Oct 25Sun
  1. Interconnects65

    Kimi K3.1 Pro release sparks controversy, analysis of its benchmark test performance and market response.

    Kimi K3.1 Pro release has sparked controversy, its benchmark tests surpassing GPT-6 Astra on Artificial Analysis but slightly underperforming on Terminal-Bench Science and ProgramBench. The model release is accompanied by suspected paid promotion, and its pre-training effectiveness is criticized as not meeting expectations.

    Same story · 3 outlets

    How the accounts differ:Artificial Analysis gives the score 55 and ranks fourth; MarkTechPost mentions the total parameters of 2.8T and the MoE model with 104B active parameters.

  2. The Decoder65

    Anthropic founder Clark moves self-improvement AI timeline to 2027

    Anthropic founder Clark, based on TasteVal benchmark test results, has moved the timeline for AI self-improvement (RSI) from 2028 to 2027. TasteVal measures the computational efficiency of AI models in scientific research tasks. Anthropic's Opus 5.5 model achieves expert level with a 2.3 computational multiplier. Since December 2025, the research taste of top AI models has doubled every three months.

  3. The Decoder72

    OpenMobile-2, an open-source smartphone AI model, claims to be comparable to proprietary models.

    Researchers from Nanjing University and institutions like SenseTime have released OpenMobile-2, which includes two AI models based on Qwen3.5 (9B) and Qwen3.6 (27B), and has publicly disclosed the training environment, data, and reproduction instructions.

    Why it matters: Research fixed the training data size while only increasing the number of applications, observing an improvement in success rates for unseen applications, providing a reproducible path for data construction of mobile agents.

Oct 24Sat
  1. Latent Space67
    Same story · 3 outlets

    How the accounts differ:Artificial Analysis gives the score 55 and ranks fourth; MarkTechPost mentions the total parameters of 2.8T and the MoE model with 104B active parameters.

  2. Big Technology

    Sundar Pichai believes the tech industry is far from reaching the end point of recursive self-improvement

    Sundar Pichai believes the tech industry is far from reaching the end of recursive self-improvement (RSI), although AI models are achieving automated improvements with the assistance of AI researchers; he claims the entire tech industry is facing a shortage of computing resources due to a decision two years ago, Google Cloud Platform is growing rapidly but needs to sacrifice short-term profits for cutting-edge AI research, and believes moderate constraints can inspire AI innovative thinking.

  3. Simon Willison82

    Kimi K3.1 Pro goes live with Kimi API, promising to open source weights by November 4th.

    Kimi K3.1 Pro goes live with Kimi API today, weights not yet open, Moonshot promises to release complete model weights by November 4th, 2026. Pricing is $2.00/100 million tokens for input, $10/100 million tokens for output, the same as GPT-6.1 Sol, half of Claude Opus 5.5, also provides a Highspeed version that is 2-3 times faster and doubles the price.

Oct 23Fri
  1. The Verge · AI

    Microsoft claims its AI tool's diagnostic accuracy is four times that of doctors.

    Microsoft claims its AI tool has four times the diagnostic accuracy of human doctors in simulated medical scenario tests, with related research published in the journal 'Science'. The tool is called Diagnostic Orchestrator, which collaborates multiple AI agents to reason symptoms and make diagnoses, achieving 83% accuracy in medical report tests and 80% in emergency data tests, superior to human doctors by about 47%.

Oct 22Thu
  1. Sierra Blog75

    𝜏-Entity: How does the speech intelligence agent accurately capture entity information

    The 𝜏-Entity benchmark speech intelligence agent captures the accuracy of entity information such as names and phone numbers in 200 tasks. GPT Live 1 has a correct rate of 60.3% under normal conditions, but only 34.0% under noise and voice interference; recommended verification strategies can increase success rates by 14-31 percentage points, but call duration increases by 21-28 seconds.

  2. Hugging Face Daily Papers65

    StreamEval: Benchmark for evaluating interactive streaming video generation models

    StreamEval benchmarked the performance of interactive streaming video generation models on five tasks, finding reliable request execution and sustained state consistency to be major challenges. The benchmark includes 300 scripted test cases, covering character dialogue, character performance, world generation, instruction editing, and reference editing tasks, scored across four evaluation dimensions (task execution, state consistency, visual fidelity, and audiovisual coordination).

  3. MarkTechPost55

    Cactus Whistle 16.9 MB Speech Model Performance Evaluation on CPU: Comparison Results with Whisper Base

    The Cactus Whistle speech model transcribes seven languages on the CPU with a 16.9 MB file size and returns word timestamps and probabilities. Tests show it outperforms Whisper Base on its test-other dataset, but there is no significant difference from beam search, with the speed advantage shrinking as audio length increases. Additionally, it tested 30-second window audio processing, streaming latency, timestamps, keyword bias, other languages, noise, embedding, and speech-to-tool calling features.

Oct 21Wed
  1. OpenAI Alignment Blog50

    OpenAI introduces the complementary metric g-mean² to enhance model monitorability evaluation

    OpenAI has introduced the complementary metric g-mean² to improve model monitorability evaluation. g-mean² calculates TPR and TNR through behavioral labels and monitoring predictions, but cannot solve the problems of mixed differences in different model tasks and deployment risks. The new metric includes a paired matching metric for aligned shared instances and a post-control integrated metric simulating monitoring rejection of outputs, to more comprehensively evaluate model deployment risks.

  2. Hugging Face Blog58

    FairStress: A benchmark for a more in-depth evaluation of LLM decision fairness

    FairStress benchmark evaluated LLM performance in demographic fairness across 300 decision scenarios across 29 fields (such as recruitment, healthcare), including 13 million test cases. The study found that the same persuasive prefixes (adversarial prefixes) have varying impacts on model decisions across different demographic groups, and there are differences in how models explain decisions containing demographic information.

Oct 20Tue
  1. One Useful Thing75

    Claude Code v2.1.159 release

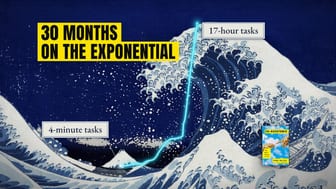
    Claude Code v2.1.159 released, supporting an 8k context window, available on GitHub; the author generated charts in Claude Projects using Opus 5.5, where AI handled time-consuming research, drawing, layout, image, and citation work, demonstrating exponential growth in AI capabilities.

Oct 19Mon
  1. Artificial Analysis Articles70

    AA-PersonalityBench releases: a benchmark to measure the communication ability of AI models

    AA-PersonalityBench evaluates 30 personality traits, including friendliness, through 900 questions, using LLM judges for blind pairwise judgments, providing Elo scores and 95% confidence intervals; Claude Sonnet 5.5 scores highest in traits like friendliness (Elo 1000), and Gemini 4 Argon (high) performs outstandingly in traits like transparency (Elo 1059).