DeepSeek · Hugging Face new models
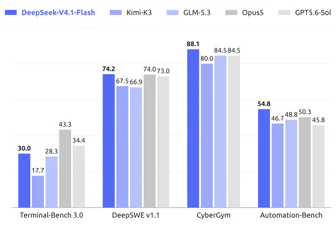
DeepSeek-V4.1-Flash released: 552B parameter multimodal MoE model, context up to millions of tokens
DeepSeek-V4.1-Flash is a 552B parameter multimodal MoE model that supports context up to one million tokens, natively processing images and text and generating text autoregressively. It adopts a Causal Encoder-Decoder architecture, reducing global KV cache usage to 890 bytes/token through technologies like CSA2 and FP4 primary KV cache, a 75% reduction compared to DeepSeek-V4-Flash.