Skip to content
Live
  1. ITHome · AI82

    Google expands the Antigravity multi-agent system, launches the Teamwork system, and verifies multiple mathematical proofs.

    Google announces expansion of its Antigravity multi-agent system, forming the Teamwork system with multiple professional agents driven by Gemini, capable of verifying complex mathematical proofs and optimizing software system performance.

    Why it matters: The original text provides specific outputs and open access points for multi-agent systems in mathematical formalization, molecular recognition, and code rewriting, which can be used to assess the practical boundaries of their collaborative verification mechanisms.

  2. Google Research88

    Google Opens /teamwork Multi-Agent Workflow in Antigravity

    Google has opened the /teamwork multi-agent workflow in Antigravity to external researchers and developers, which can be used in conjunction with Gemini 4 Argon, Carbon, and Hydrogen; /boost and Deep Review are also available.

    Why it matters: Google has disclosed /teamwork's specific results in multi-agent research and engineering tasks and made it available for external researchers to use.

  1. Hacker News · AI hot posts86

    Edge0 open sources 145B and 120B edge-side models and inference frameworks.

    Edge0 open-sourced the Edge0-145B and Edge0-120B two edge models, and also released a unified inference framework and deployment tools. Officially, the 145B model can run locally on compatible laptops, with peak memory of 29GB, decoding speed of 80+ tokens/s, pre-filling speed of 1100+ tokens/s, supporting context lengths of 128K–256K.

    Why it matters: The original text provides actual memory, speed, and multiple benchmark comparisons of the edge 145B model, which can be used to judge the practical boundaries of running cutting-edge models locally.

  2. vLLM Blog60

    vLLM supports Thinking Machines' Inkling 2 Small on its first day of release

    vLLM provides support for Inkling 2 Small on its first day of release. The model is a multimodal MoE with text and visual inputs, featuring a total of 594B parameters, 17B activation parameters, a maximum context length of 1M tokens, and comes with a built-in DSpark beam decoder.

    Why it matters: The original text provides details of vLLM's Day-0 support for Inkling 2 Small and multiple kernel optimizations, allowing readers to understand the deployment path and throughput performance of the model.

  3. Google AI Blog82

    Google Search has integrated Gemini 4 Hydrogen and is now open to global users.

    Google Search has launched Gemini 4 Hydrogen, the largest model upgrade to date, now available to all global users. The company claims the new model can understand multi-part questions, spelling errors, and highly specific requests, and leverages stronger instruction following and tool calling capabilities to respond to each question individually. Hydrogen's reasoning ability also enhances query distribution, allowing it to retrieve multiple related subtopics simultaneously and provide more images, structured responses, comparison tables, and custom tools.

    Why it matters: Google's official statement on Gemini 4 Hydrogen explains changes in intent understanding, query distribution, and visual responses in search, which can be used to judge the direction of adjustments to the search experience.

  4. Google DeepMind87

    Google DeepMind releases Gemini 4 Hydrogen model

    Google DeepMind releases Gemini 4 Hydrogen, targeting daily coding and intelligent agent workflows, with an Artificial Analysis intelligence index of 51 at the default high thinking level, higher than Argon's 50, and reaching 54 at the xhigh level

    Why it matters: Google provides the division of labor and positioning of Hydrogen, Carbon, and Argon, as well as the actual differences in cost and speed between multi-model arrangements.

  1. The Decoder78

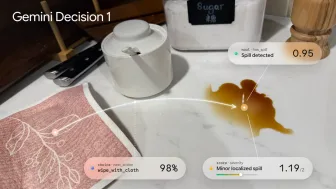
    Google launches Gemini Decision 1 and Gemini Decisions API, capable of processing 1000 issues at a time

    Google DeepMind launches Gemini Decisions API, targeting yes/no, multiple choice, and scale scoring for closed-form judgments. The underlying model, Gemini Decision 1, can handle up to 1000 independent questions at once, covering text, images, audio, video, and PDF.

    Why it matters: Gemini Decision 1 makes closed-loop judgment an independent API and provides latency, price, and benchmark performance for comparison with recent similar decision models.

  1. One Useful Thing78

    Ethan Mollick practically tests Claude Fable 5.2: Close but not complete AGI

    Ethan Mollick, after trying out Claude Fable 5.2 before its public release, believes that according to the definition of 'achieving the level of most human experts on most available computer-completed intellectual tasks,' it is close to AGI but still has a gap.

    Why it matters: The author uses six cross-domain practical cases to illustrate that the model's ability has approached general intelligence, but lacks the ability to judge whether works are good or bad.

  2. Claude · YouTube68

    Claude Mythos 5.2 predicted the complete AAV coat structure

    Claude Mythos 5.2 predicts the complete AAV capsid structure, which is composed of 60 identical protein chains. It writes code for an open-source folding model to handle the overlap grouping of adjacent five chains, then uses the symmetry of the capsid to assemble the 60 chains. On AAV2, its prediction deviates from the experimental structure by about the width of an atom.

    Why it matters: The original text provides specific methods and accuracy of the model in real scientific research tasks, allowing readers to judge its applicable boundary in structural prediction work.

  3. Claude · YouTube75

    Anthropic released Claude Fable 5.2

    Anthropic releases Claude Fable 5.2, designed for the most challenging technical challenges, with improvements in coding, reasoning, and vision, suitable for the most ambitious open-ended technical work. The official recommendation is to use Opus 5.5 for most coding and knowledge tasks, and Fable 5.2 is now available in the Pro, Max, Team, and Enterprise packages.

    Same story · 6 outlets

    How the accounts differ:TechCrunch states the input price of Fable is reduced to $8 per million tokens; others do not mention the price.

    Why it matters: The official statement explains the positioning and applicable scenarios of Fable 5.2, and provides a choice suggestion between Opus 5.5, making it easier to decide which model to use.

  1. QbitAI72

    Baidu Wenxin has first disclosed the progress of RSI, and ERNIE Evolve has been used in the development of Wenxin 5.5 Flash.

    Baidu Wenxin first disclosed its automatic research system ERNIE Evolve, which can autonomously propose research directions, conduct experiments, and validate results. It has been used for inference optimization in Wenxin 5.5 Flash. In the low-latency scenario optimization for Kunlun Chip P800, ERNIE Evolve took about 168 hours and went through 4 rounds of direction exploration, with the optimal version's generation speed increasing to 623.6% of the baseline. The deterministic reasoning throughput optimization increased the throughput to 133.7% of the baseline in 3 days.

    Why it matters: Baidu has disclosed the architecture and production environment optimization data of the automatic research system ERNIE Evolve, which can observe the actual landing points of RSI in inference optimization.

  2. Hacker News · 300+78

    llama-modchip enables the 284B DeepSeek-V4-Flash to run on a 64GB memory without GPU

    llama-modchip releases a set of ggml/llama.cpp core patches and quantization transcoding tools, compressing the 284.33B DeepSeek-V4-Flash to 56.56 GiB (1.71 bpw), which can run on a pure CPU machine with 64 GB memory, with a peak memory of 57.61 GiB under 256K context and no need for swap.

    Why it matters: The project provides a quantization scheme and core patches for running 284B MoE on 64 GB memory, along with measured data for each hardware, which can be used to determine the feasible boundary for pure CPU deployment.

  1. vLLM Blog72

    REINFORCE Zero: Aligned kernel allows asynchronous RL to train stably under lag 64.

    NVIDIA Research and Inferact's REINFORCE Zero proposes to first align rollout with training kernel, then use unclipped token-level importance sampling to correct weight lag, achieving a training step throughput 2.40 times that of synchronous training under 16 GPUs and 12K updates.

    Why it matters: The paper breaks down the gap between asynchronous RL's rollout and training into two items: weight lag and kernel inconsistency, and proposes an alignment-free, no-trimming importance sampling method after alignment.

  2. Artificial Analysis Articles72

    Thinking Machines released Inkling 2 Small, Artificial Analysis Intelligence Index score 31

    Thinking Machines released Inkling 2 Small, scored 31 on the Artificial Analysis Intelligence Index v5.0.1, 18 points higher than Inkling Small, and the same as Gemini 3.8 Flash (high).

    Why it matters: Third-party reviews provide a point-by-point comparison of Inkling 2 Small with Gemini, Claude, and other models in terms of intelligence index, coding, and hallucination rate, which can be used to determine its positioning.

  3. ITHome · AI78

    Ant Group's Baidu Ling-3.2-flash releases a native multimodal model, with three benchmarks surpassing Claude Opus 5

    Ant Media official team releases native multimodal model Ling-3.2-flash, with a total of 560B parameters, 25B activation parameters, and 1M context window, supporting image, text, and video input.

    Why it matters: The original provides three benchmark comparisons and API pricing, allowing readers to judge the capability position and call cost of this multimodal model.

  1. vLLM Blog75

    vLLM provides Day-0 support for Kimi K3.1 Pro

    vLLM announces Day-0 support for the open-sourced Kimi K3.1 Pro on NVIDIA, AMD, Google TPU, and Alibaba's Zhenwu PPU, a 2.8T parameter (104B activation) multimodal MoE model with 1M context tokens.

    Why it matters: The vLLM team details the engineering trade-offs for Day-0 adaptation of Kimi K3.1 Pro, including specific numbers for sparse attention, KV cache packing, and DCP.

  1. Together AI Blog75

    Together AI has released Together Compiler, continuously compiling and optimizing AI inference.

    Together AI has released Together Compiler (TKCC), which uses high-throughput intelligent agents to continuously generate optimization solutions for inference engines, achieving 1.3-3x TPS improvements on cutting-edge open-source models like Kimi K3, GLM 5.3, MiniMax M3.1-Flash, and DeepSeek v4.1-Flash within 24 hours.

    Same story · 2 outlets

    How the accounts differ:Together AI Blog mentions models Kimi K3 and GLM 5.3; MarkTechPost mentions SemiAnalysis InferenceX AgentX.

    Why it matters: The original text provides a comparison of throughput improvements and engine startup time on multiple cutting-edge models, allowing for an assessment of changes in the inference optimization process.

  1. Anthropic Research62

    Anthropic has released the verifiable reasoning system FlashProve, generating proofs at approximately 110 tokens/second on a single H100.

    Anthropic announced the verifiable reasoning prototype FlashProve, using zkSNARK to prove that the response indeed comes from the committed model weights. For the 400B parameter Llama 4 Maverick (4-bit quantization), a single H100 generates proofs at approximately 110 tokens/second, with proofs for each 1,024 token request being about 19 MB, and verification on a 24-core CPU taking about 17 seconds.

    Same story · 2 outlets

    How the accounts differ:MarkTechPost states the proof volume is 18.78 MB; The Decoder states it is about 19 MB.

    Why it matters: Anthropic has released the measured data and Lean formal proof of the verifiable reasoning prototype FlashProve, allowing for a cross-comparison with existing zkML solutions.