Skip to content
Live
Oct 2Fri
  1. Prime Intellect Blog

    Prime Inference: Provides fast and reliable inference services for cutting-edge open-source models.

    Prime Inference is launched, providing fast and reliable inference services for cutting-edge open-source models, supporting serverless endpoints and reserved capacity, running models using GPU infrastructure across multiple data centers. Its first public deployment, GLM-5.3, went live on OpenRouter on September 22, and is currently one of the fastest GLM-5.3 endpoints on OpenRouter, with zero tool call error rates and 100% uptime.


Sep 30Wed
  1. Google Developers Blog

    How does Sparse VideoGen (SVG) accelerate temporal and spatial attention computation for video diffusion on TPUs

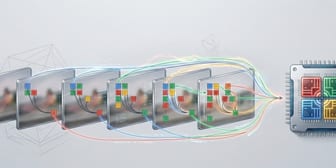
    Sparse VideoGen (SVG) dynamically routes attention heads to spatial or temporal masks by identifying the spatiotemporal structures of different attention heads in video diffusion models, converting theoretical sparsity into actual end-to-end speedup. On TPU v6e, SVG retains about 38.87% of query-key pairs, achieving 3.5x inference acceleration while maintaining output quality at a given sparsity level. The scheme employs custom JAX and Pallas Splash attention kernels to convert theoretical sparsity into physical sparsity on hardware.

  2. Baseten Blog

    Baseten collaborates with OpenAI to release an open-source model integration solution.

    Baseten collaborates with OpenAI to integrate support for open-source models into the agentic workflows of OpenAI customers, enabling organizations to optimize agentic workflows across open and closed models and route tasks to the best model. Baseten provides features such as Day zero model access, full-stack performance optimization, multi-cloud capacity and reliability, developer experience, and enterprise governance to support fast and reliable inference and seamless integration into enterprise toolchains.

Sep 29Tue
  1. OpenClaw Blog75

    OpenClaw Enterprise Open Source Intelligent Agent Platform Released

    OpenClaw Enterprise (OCE) is an open-source, vendor-neutral agent management platform designed for sensitive environments. The platform introduces an enterprise-grade control plane before the 1.0 release through multi-tenancy, hard security boundaries, and standardized agent primitives, supporting governance and auditing, and allowing core components like harness, models, and sandboxes to replace third-party or internal implementations.

Sep 28Mon
Sep 25Fri
  1. OpenClaw Blog75

    Microsoft contributes upstream improvements to the OpenClaw project based on Autopilot

    Microsoft's released Autopilot personal agent based on OpenClaw, Microsoft and OpenClaw Foundation collaborate to enhance its enterprise-level runtime capabilities, has opened the preview to the first batch of customers. Microsoft improves OpenClaw through upstream contributions, including enhancing agent security configuration checks, building native Windows experience, improving interaction reliability, and optimizing background task processing and database recovery response.

  2. Baseten Blog75

    LangChain fine-tunes on Baseten Loops via LangSmith tracing

    LangChain announced the launch of the LangSmith fine-tuning feature at the Interrupt 26 conference in New York today. The feature is based on the open-source CLI smithtune, which reads LangSmith traces to generate supervised fine-tuning datasets and trains them on Baseten Loops, finally deploying them to Baseten's dedicated inference service. The CLI uses the user's Baseten API key, and training and inference costs are charged to the Baseten account.

  3. GitHub Blog · AI & ML

    GitHub Security Lab Taskflow Agent implements automated fuzzing

    GitHub Security Lab Taskflow Agent automates the fuzzing process for C/C++ projects using LLM, completing entry point identification, build system analysis, test case generation, AFL++ execution, coverage analysis, and vulnerability report writing without manual intervention. The Agent uses the Claude Sonnet 5 model and manages state via an SQLite database to achieve iterative coverage improvement, doubling the time budget for each iteration until coverage growth stagnates.

Sep 24Thu
  1. Anthropic Research

    Project Swap: The performance and challenges of agents in market transactions

    In the Project Swap experiment, 201 Anthropic employees conducted book trades through the Claude agent, with 61% of the agents accurately matching employee preferences. The agents performed well in the trades, but their efficiency was limited by insufficient information. The experiment showed that model performance had a greater impact on the negotiation results of the agents than instructions, with most participants satisfied with the books they received from the trades and willing to pay about one-third of their annual budget for Claude to handle the trades.

  2. OpenHands Blog75

    OpenHands Enterprise new features: enhanced visibility, governance, and control capabilities.

    OpenHands Enterprise's latest version has added organizational-level features such as management credentials, usage, integration, and automation, and updated the interface aligned with Agent Canvas. Administrators can configure organizational key sharing, monitor usage through the 'Your Budget' dashboard, support OAuth authentication to connect to MCP servers, and achieve cross-organizational visibility and management automation.

  3. GitHub Blog · AI & ML

    How does GitHub Copilot application render large pull requests?

    GitHub Copilot application addresses performance issues when rendering large pull requests with extensive comments by highly decomposing the document into two independent domains: deterministic code height and dynamic block effective height. The dynamic block geometry covers unpredictably tall content such as comment threads, drafts, and reply composers, each block identified by its content type rather than location and anchored to files, lines, and sides to ensure no loss during reordering. This design makes comment heights predictable before rendering, avoiding scroll jumps and enhancing rendering performance for large code differences.

  4. Google DeepMind

    Google DeepMind introduces Private AI Compute, achieving cross-device private persistent memory.

    Google DeepMind introduces Private AI Compute, a new architecture that achieves cross-device AI persistent memory through cloud-based encrypted storage and device key management, ensuring data privacy. The architecture temporarily decrypts user data in a cloud-isolated environment to process requests and immediately encrypts and stores new contexts, while the device holds the decryption keys. Users can verify the authenticity of server software and audit security protocols, supporting AI in maintaining device-level privacy standards even when processing complex tasks efficiently in the cloud.

Sep 23Wed
  1. Together AI Blog

    How to train your own Jev model for $17

    Together AI released a guide on how to fine-tune the Jev classification model using the Qwen3.5 4B model and a Hugging Face dataset of 38,340 items, with a training cost of about $17 and a duration of about 25 minutes; after deployment, it can be used for inference via an API endpoint (e.g., ENDPOINT_NAME), suitable for scenarios such as intent recognition for e-commerce customers.

  2. OpenHands Blog

    What is an AI dark factory? Software engineering insights learned from unmanned manufacturing.

    AI Dark Factory refers to AI agents autonomously completing software development, with humans only setting goals and constraints. Its core principle originates from unmanned manufacturing, i.e., achieving automation through standardized inputs, deterministic verification, and continuous monitoring, rather than relying on model intelligence improvement. Engineering needs to refactor processes around automation, taking repeatable environments, executable acceptance criteria, and execution records as the foundation. Currently, it is mainly applicable to boundary-defined repetitive tasks.

Sep 22Tue
  1. OpenHands Blog

    How to Self-Host AI Models: Complete Setup Guide

    Self-hosted AI models allow organizations to directly control the reasoning runtime environment, deployed model weights, and service operation methods, suitable for scenarios involving sensitive data, pursuing cost-effectiveness under continuous utilization, model customization, and controlling the model lifecycle. By deploying open-source weight model checkpoints on local workstations, private servers, or controlled cloud infrastructure, and using reasoning runtime service models such as vLLM, Ollama, or llama.cpp, applications can call self-hosted endpoints just like calling managed model APIs.

Sep 21Mon
  1. OpenHands Blog

    What is model-agnostic in AI? A practical guide

    Model-agnostic AI reduces direct dependency of applications and workflows on a single model, handling differences in authentication, request formats, model identifiers, etc. between different providers through an abstraction layer. OpenHands's model evaluation shows no single best model, its workflow supports use of different models for planning, implementation, debugging, and review, making model selection a continuous workload decision rather than a one-time vendor choice.

Sep 20Sun
  1. StepFun · Hugging Face new models

    Step-5-Preview-BF16 model release by Jieyue Xingchen

    Jieyue Xingchen releases flagship model Step-5-Preview-BF16, with 600B total parameters, 27B active parameters, supporting up to 1M context windows, excels in software engineering, professional knowledge work, and financial fields, capable of processing text, images, and video, deployable via OpenAI-compatible API or offline generation.

  2. StepFun · Hugging Face new models

    Jieyue Xingchen Step-5-Preview model release: Sparse MoE architecture with 600B parameters

    Step-5-Preview, the flagship model from Jieyue Xingchen, adopts a sparse MoE architecture with 600B total parameters and 27B active parameters, supporting up to 1M tokens in context, and excels in software engineering, professional knowledge, and financial tasks, demonstrating outstanding performance in the DeepSWE v1.1 benchmark. The model can be deployed via OpenAI-compatible APIs using vLLM or SGLang, or used for offline generation with Transformers.

Sep 17Thu
  1. Dify Blog65

    How to build an e-commerce shopping agent with Dify's new Agent.

    Dify's new Agent can be used in e-commerce stores to help customers explore catalogs, understand product differences, and narrow down choices. It can also route high-value inquiries to team email. The initial version requires the Agent to first familiarize itself with the catalog, describe tasks through dialogue, search DOWSE's public product pages, and return product names, prices, brief descriptions, and links. After upgrading, the Agent can identify customer budgets, occasions, recipients, and preferences, recommend up to four verified products and explain the reasons, while also returning product images.

Sep 16Wed
Sep 14Mon
  1. Google · Hugging Face new models

    Google releases EmbeddingGemma 2 multimodal embedding model

    Google has released EmbeddingGemma 2, a multimodal embedding model with 740M parameters, supporting unified 768-dimensional vector representations for text, images, video, and audio. The model can run on consumer-grade hardware, providing low-latency semantic representations suitable for applications such as search, retrieval-augmented generation, etc. EmbeddingGemma 2 has performed excellently in multiple benchmark tests, such as text, code, visual document, and audio embedding benchmark tests, and supports vector truncation to reduce storage requirements.

  2. LangChain Blog71

    How to build paid media agents with LangChain

    LangChain publicly shares its construction method for paid media intelligence agents, which run on Slack, summarize ad platform and warehouse data weekly, and generate reports. Paid media increased from contributing 0 to 20% of the marketing pipeline within 6 months, and the cost per qualified lead decreased by 30% from June to August.

    Why it matters: LangChain publicly shares the complete engineering details of its paid media intelligence agents, including context hierarchy, on-demand tool discovery, and sub-agent isolation, which can serve as a reference for building long-running intelligent agents.

Sep 12Sat
Sep 10Thu
  1. Mistral AI

    Cloudera collaborates with Mistral to bring dedicated, sovereign intelligence to enterprise data

    Cloudera collaborates with Mistral to integrate Mistral models into Cloudera's hybrid data platform, enabling businesses to deploy AI models in private clouds, public clouds, on-premises, and fully isolated environments while maintaining full control; Mistral allows businesses to train AI models with proprietary data in a controlled environment, transforming decades of institutional data into custom AI models while retaining ownership of both data and intelligence.

  2. Cursor Changelog

    Cursor launches Projects feature

    Cursor launches the Projects feature today, supporting the handling of large workloads such as feature development, migration, or full applications, capable of maintaining context across months and automatically assigning tasks to thousands of sub-intelligent agents. The project runs independently in the cloud, synchronizing codebase knowledge and work preferences through shared files, coordinating agents responsible for planning and task allocation. The feature is currently in Beta and is gradually being rolled out to all users starting today.

Sep 9Wed
  1. Dify Blog65

    Dify market from discovery to response: tighter connection

    Dify has added featured banners and real-time update functions, allowing users to find works more conveniently and give likes, ratings, and text feedback. The market collects nearly 1000 plugins and over 300 templates, supporting the construction of applications on the existing basis. Featured banners display top works and platform updates, and the direct feedback mechanism ensures creators receive feedback on the real-world use experience, forming a closed loop from construction to learning.

Sep 8Tue
  1. Mastra Blog

    Mastra Factory Beta released: An open-source automated software factory

    Mastra Factory Beta released, this open-source software factory can now automate 25-35% of PRs and close 50-60% of issues, based on the Mastra infrastructure and changing collaboration processes. It connects GitHub, Linear, and Slack, supports configurable workflows, and each agent works in a sandbox environment. Since the alpha version was launched in July, the aforementioned efficiency improvements have been achieved.

Sep 7Mon
  1. Browser Use

    What is a Headless Browser?

    A Headless Browser is a browser without a graphical user interface, controlled programmatically for automation testing, web scraping, etc. It has become popular due to the adoption of AI browser agents. Headless Chromium starts 60% faster than normal mode, uses 51% less CPU, and has a 42% lower peak RAM.

Sep 4Fri
  1. Dify Blog65

    Add automatic reminder function to Calendly using Dify Agent

    Users create an Agent on the Dify platform to connect Calendly and Gmail tools, achieving the function of automatically sending daily meeting reminder emails. The Agent uses Calendly MCP to obtain meeting schedules and participant information, and refers to preset email templates to send reminders through Gmail without modifying Calendly itself. This solution is suitable for SaaS products that only need to supplement a single workflow function.