Hugging Face Blog4040
Hugging Face releases XYBench benchmark to evaluate AI assistants' ability to solve problems based on misunderstandings
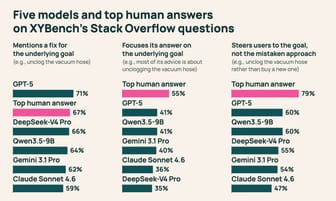
Hugging Face releases XYBench benchmark, containing 8150 real-world problems, to evaluate AI assistants' ability to identify user misunderstandings and guide them to correct solutions. Claude Sonnet 4.6, GPT-5, Gemini 3.1 Pro, Qwen3.5-9B, and DeepSeek-V4 Pro tend to focus on user errors (Y) rather than actual goals (X), with only 35-41% of responses centered on the actual goals.