Skip to content
Live
Oct 14Wed
  1. Google AI Blog90

    Google has released the Gemini 4 Argon cutting-edge model.

    Google has released Gemini 4 Argon, opening it up to developers, businesses, and researchers, with API pricing at $2 per million input tokens and $10 per million output tokens, offering a 95% discount on cached input tokens.

    Why it matters: Official pricing, baseline rankings, and multiple internal implementation cases are provided, allowing judgment on its position in coding and research workflows.

  2. IBM Research Blog38

    IBM will launch the 7-nanometer nanoscale stacking technology early research and development process design kit (PDK) in the first quarter of 2027.
    IBM announced that it will launch an early research and development process design kit (PDK) for 7-nanometer nanoscale stacking technology in the first quarter of 2027, to help semiconductor companies evaluate the technology before large-scale adoption. The kit will provide a standard cell library for logic functions and SRAM design examples, supporting layout and routing, early module-level layout, and density and power performance evaluation. Nanoscale stacking technology achieves 3D layout at the transistor level for the first time on logic wafer technology by stacking transistors vertically rather than placing them side by side, which is significantly different from current nanosheet transistor architectures.

Oct 13Tue
  1. LangChain Blog

    LangSmith adds an AI search feature to optimize large language model agent debugging through behavior tracking

    LangSmith introduces an AI search feature that supports natural language queries for intelligent agent behavior tracking records. This feature can search for user inputs, agent reasoning, tool calls, and responses, helping teams discover specific behavior patterns, such as PII leaks or user frustration. The AI search combines SmithDB's data layer and decision models, achieving fast and efficient cross-SDK searches by analyzing standardized trajectories rather than raw long texts, prioritizing key information like user messages and agent responses.

  2. IBM Research Blog58

    IBM Research uses an open-source agent factory to achieve 52-fold acceleration in quantum error correction chip design with a cost of $26

    IBM Research uses an open-source agent factory to optimize quantum error correction hardware, achieving 52x acceleration with a cost of about $26; with the same budget, a closed-source cutting-edge model configuration costs $299 (11.5x higher) but provides 204x acceleration, with the open-source configuration achieving hardware optimization with a smaller area; the agent factory assigns tasks to parallel working agents through a coordinator, combining code modification with hardware effect evaluation, exploring various architectural possibilities.

  3. LangChain Blog

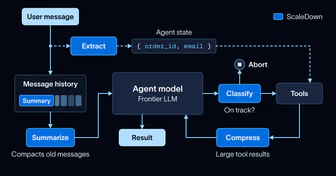
    How ScaleDown optimizes context management for long-running agents through compression and extraction techniques

    ScaleDown optimizes context management for long-running agents through compression and extraction techniques, its model is 41 times cheaper and 2.7 times faster than general models like GPT-5.5 in benchmark tests. ScaleDown provides four models: Summarize, Compress, Extract, and Classify, respectively for summarization, compression, extraction, and classification, supporting up to 1M tokens of input, and supporting image and PDF input.

  4. Google Developers Blog

    Gemini 4 Argon optimized the performance of a 200,000-line Python codebase

    Gemini 4 Argon has been running for 11 hours without human intervention, proposing 6 optimization suggestions by analyzing the ADK Python repository with 205,000 lines of code. Ultimately, 2 of them were adopted and deployed, reducing the memory session preparation time by about 40% and increasing the cold package import speed by 21%. The model followed the repository maintainer's guidelines during the optimization process and ran all 16,892 unit tests.

  5. GitHub Blog · AI & ML

    GitHub Copilot Application Introduction: How to Teach Copilot to Understand Your Codebase

    GitHub Copilot can allow users to convey project rules, encapsulate repeatable processes, provide professional guidance, and connect external tools to improve collaboration efficiency through custom instructions, proxy skills, custom agents, and the Model Context Protocol (MCP) server. Custom instructions define code standards, proxy skills encapsulate repetitive tasks, custom agents handle complex work, and MCP servers extend Copilot functionality.

  6. Microsoft Research

    Microsoft Research open-sources multi-modal model StudentSim for simulating student learning behavior

    Microsoft Research has open-sourced the multimodal model StudentSim for simulating student learning behavior. It is trained on publicly anonymized learning records to create a personalized student simulator that outperforms benchmarks in areas such as chess, English writing, and mathematics. It provides early feedback signals for AI tutoring systems but is not intended to replace teachers or classroom teaching.

Oct 12Mon
  1. NVIDIA Blog

    NVIDIA open-sources Vera Rubin architecture at OCP Global Summit to help scale global AI factories

    NVIDIA announced at the OCP Global Summit that it will open-source the NVIDIA Vera Rubin rack and compute shelf design. By opening the NVIDIA MGX architecture, it provides system builders with a common foundation for building next-generation AI factory infrastructure. The Vera Rubin AI factory adopts the third-generation MGX rack architecture, supporting rack deployments of up to 250kW. It expands the open architecture by adding configurable I/O ports, fanless liquid-cooled compute shelves, standard power and cooling interfaces, and support for 19-inch devices.

  2. Microsoft Official Blog

    Microsoft expands the Azure Maia system to multi-gigawatt deployment

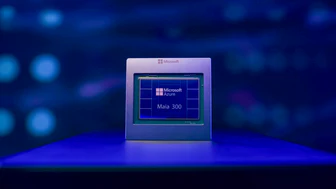
    Microsoft is expanding the Azure Maia system to multi-gigawatt deployment, Maia 200 has entered production, and Maia 300 will be launched in 2027. Maia 200 is serving Microsoft's production workloads, including Microsoft Copilot, and supports the MAI team in developing next-generation models. GitHub Copilot and Microsoft Foundry will be launched by the end of this year.

  3. Anthropic Newsroom

    Anthropic strengthens defenses against distillation attacks

    Anthropic has significantly reduced the effectiveness of distillation attacks on Claude using a new method, reducing the amount of data collected by attackers by about 90% to 99%. Distillation attacks are industrial-scale covert activities that involve unauthorized copying of model capabilities, often using fake accounts to enable companies to imitate cutting-edge capabilities at extremely low cost. Anthropic's new defensive measures have blocked a large amount of paid traffic and revenue flowing to attackers, but some legitimate users need to update their integrations to adapt to these changes.

Oct 11Sun
Oct 9Fri
  1. AWS Machine Learning Blog

    How BlockRun and Incarna use Amazon Bedrock AgentCore Pay to enable AI agents to pay per inference

    AgentCore Pay allows AI agents to pay as needed, Incarna uses it to enable agents to pay per request to BlockRun for model inference, BlockRun offers on-demand billing inference services for over 90 models. AgentCore Pay reduces the workload of adding x402 support from months to days through hosted wallets, native protocol handling, infrastructure layer spending governance, and auditable settlements.

  2. AWS Machine Learning Blog

    Use Amazon SageMaker HyperPod to share GPU clusters between teams and achieve isolation and fairness.

    Amazon SageMaker HyperPod provides centralized authentication through AWS IAM Identity Center, uses the SageMaker AI domain to provide a customized user experience, combines Kubernetes namespaces to achieve workload isolation, and leverages HyperPod task governance for fair resource allocation, supporting multiple teams in efficiently sharing a single HyperPod EKS cluster.

Oct 8Thu
  1. Sakana AI40

    The Evidence Finder, a search tool for doctors, adopts Sakana Namazu: A Japanese-specification AI that thrives in medical settings.

    The Evidence Finder, an evidence search tool for doctors, adopts Sakana Namazu. Iris Corporation's service searches for literature from PubMed, and Namazu, which achieved a 96.4% accuracy rate in the doctor's national examination, generates responses. Sakana Namazu avoids catastrophic forgetting while enhancing Japanese capabilities while maintaining the performance of the base model.

  2. Google Developers Blog

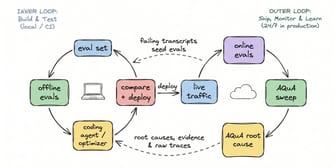
    AQuA: An agent that can diagnose agent issues in a production environment.

    AQuA runs alongside the production agent, analyzing production trajectories through a five-stage process (sampling, review, clustering, validation, tracking), clustering common issues, and generating actual/expired findings to help teams continuously monitor and improve agent quality. It uses target files written by developers and custom metrics to guide the review process and supports integration with AutoRaters on the Gemini platform.

  3. Anthropic Research

    Anthropic has launched an open-source software vulnerability discovery service.

    Anthropic has launched an optional vulnerability discovery service, OSS Scanner, which uses large models like Claude Mythos to scan open-source code, providing free security audits, but outputs are not manually reviewed. The service has disclosed 97 high-risk vulnerabilities to 48 projects, of which 88% meet CVD standards, receiving positive feedback from projects such as PostgreSQL and OpenSSL.

  4. NVIDIA Blog

    NVIDIA and Microsoft team up to usher in a new era of AI agents for Windows PCs: RTX Spark and local AI calculator

    NVIDIA and Microsoft collaborate to launch RTX Spark laptops and Windows AI agent infrastructure, supporting local running of 125B parameter Qwen 3.8 Flash Next models; Microsoft releases MXC operating system-level container to ensure agent secure operation, pre-orders for RTX Spark open today, paired with Grace Blackwell chip, offering up to 20 PFLOPS inference performance.