Hugging Face Daily PapersSame story · 2 outlets4545
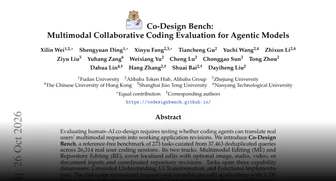
Co-Design Bench: Multimodal Collaborative Coding Evaluation Benchmark for Agent Models
The Co-Design Bench benchmark includes 273 tasks and 2,331 acceptance criteria written by experts, derived from 26,314 real user coding sessions. On 10 model endpoints, gpt-6-astra averages 69.9% passing the criteria for each task, but only 26.4% of tasks are fully satisfied; Qwen3.8-27B has an overall strict completion rate of 64.4% and ranks second in the repository editing subset.