Skip to content
Live
Oct 31Sat
Oct 30Fri
  1. Hugging Face Daily Papers31

    SpecSlot: A role-coupled tokenization method for generating Transformers in pixel space

    SpecSlot improves pixel space generation Transformer by using local spectral slots and limiting global attention without increasing computational cost, enhancing image details. SpecSlot expands each spatial anchor to multiple slots, assigning each slot a different DCT coefficient band, which separates anchor density and spectral refinement; only the low-frequency slots of each anchor participate in global attention, while all slots perform local interactions.

  2. Ant Group inclusionAI · Hugging Face new models38

    inclusionAI/ZwZ2-9B-GGUF GGUF format weights release

    inclusionAI releases ZwZ2-9B GGUF format weights, belonging to the Zooming without Zooming v2 project, including language models (FP16, Q8_0, Q4_K_M) and visual encoders and projectors (mmproj, FP16, Q8_0, Q4_K_M), requiring pairing with llama.cpp Qwen3.5 multimodal support for use, supporting CLI inference and Web Chat deployment.

  3. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/ZwZ2-4B-GGUF model weights released

    The inclusionAI/ZwZ2-4B-GGUF model weights have been released. This model is part of Zooming without Zooming v2 and is divided into a language model (FP16, Q8_0, Q4_K_M) and a visual encoder and projector (mmproj, FP16, Q8_0, Q4_K_M), offering multiple precision combinations. It needs to be used with llama.cpp (supporting Qwen3.5 multimodal).

  4. Hugging Face Daily Papers58

    L3G-World: Real-Time Infinite World Generation Model Based on Latent 3D Gaussian Memory

    L3G-World uses compact latent 3D Gaussian memory and video diffusion Transformers to alternately perform autoregressive updates, generating spatially consistent interactive worlds in real time. The model grows memory with the scene range rather than the flow length by generating Gaussians in new areas and refining existing Gaussians, each storing VAE latent features that can be directly rendered into DiT's latent space.

  5. Hugging Face Daily Papers65

    LOWN: Certificate-guided visual routing for efficient diffusion visual language models

    LOWN adapts to skip image processing during diffusion visual language model decoding, reducing computational load while maintaining accuracy when predictions are consistent. Since visual markers account for 89-97% of input in the studied benchmarks, most decoding computations are used for repetitive processing of the same images.

  6. ITHome · AI58

    Baidu open-sources Wenxin Unlimited OCR 2 document parsing model, supporting 'infinite' number of pages

    Baidu has open-sourced the Wenxin Unlimited OCR 2 model, which supports parsing documents totaling over 3,600 pages at once, natively supporting layout element segmentation recognition and cross-page text merging, table recognition and merging. It scored 84.6 on the MPDocBench benchmark test and 77.1 on the MarathonDocBench benchmark test.

  7. ITHome · AI50

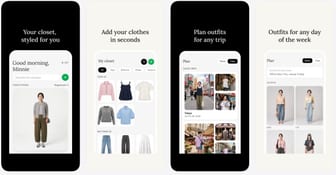
    Meta quietly launched the fashion app Style Sketch: AI helps you dress and also allows virtual try-on.

    Meta has launched the AI fashion app Style Sketch, where users can link their Instagram accounts to generate a virtual wardrobe and receive outfit recommendations, and can also try on clothes on a virtual model. The app supports iOS and Android systems and has already launched in Indonesia, Singapore, and Thailand.

  8. TechCrunch · AI55

    Meta quietly launched an AI fashion app called Style Sketch.

    Meta quietly launched an AI fashion app called Style Sketch, which connects to Instagram or allows users to manually upload photos to build a virtual wardrobe. It recommends outfit combinations based on existing clothing and provides virtual try-on features matched to body and skin color. The app is currently only launched in Indonesia, Singapore, and Thailand, supporting iOS and Android platforms.

  9. Codex releases45

    Codex 0.166.0 released: adding keyboard driver transcription selection, Markdown rendering optimization, and GPT-6.1 Terra support

    Codex 0.166.0 released, adding keyboard driver transcription selection (supporting word, line, and page operations), integrated search and configurable shortcuts, as well as consistent Markdown rendering in asynchronous questions, options, answers, and transcription responses. Also supports GPT-6.1 Terra and adds codex queue --resume feature to resume unloaded threads.

Oct 29Thu
  1. ITHome · AI58

    Microsoft has released the largest DirectX ray tracing upgrade since 2018: AMD RX 9070 example performance improvement of about 66 times

    Microsoft has released the official version of DirectX 12 Agility SDK 1.620 and the preview version 1.722, bringing updates such as cluster geometry and PTLAS to DXR to reduce ray tracing computational overhead. On the AMD RX 9070, cluster geometry boosts performance from 1.2 FPS to 79 FPS, an increase of about 66 times, with memory usage reduced by nearly 90%. New features require support from graphics card manufacturers, currently covering NVIDIA RTX, AMD RX 9000 series, and Intel Arc graphics cards.

  2. ITHome · AI42

    XHEART NewCore Journey releases the intelligent driving large model chip X7 Ultra: 700 TOPS large model computing power, first in China to mass-produce Armv9 automotive-grade CPUs.

    XHEART NewCore Journey releases the X7 Ultra large model chip, achieving 700 TOPS of computing power, with mass-produced models achieving 99.99% alignment, a 80% reduction in memory bandwidth consumption, and a 100% improvement in energy efficiency. The chip incorporates a high-precision operator acceleration engine, natively supporting FP16/FP32 computing, and is the first in China to mass-produce Armv9 automotive-grade CPUs, offering a 20% performance boost and a 10% improvement in energy efficiency.

  3. Hugging Face Daily Papers

    EmbeddingGemma 2: A Unified and Efficient Cross-Modal Representation Model

    EmbeddingGemma 2 is an open-source multimodal embedding model that unifies text, image, audio, and video representations in an efficient and resource-flexible design, and performs excellently in benchmark tests. It has established a new Pareto frontier in embedding benchmark tests for all modalities, outperforming professional models and other models that are two to twelve times larger in scale. The model supports selective modality encoder loading, adjustable visual token budgets, truncatable embedding dimensions, and quantized weights to adapt to resource-constrained environments.

  4. Hugging Face Daily Papers

    Falcon audio-visual target speaker extraction model released

    Falcon is a causal audio-visual target speaker extraction model that extracts the voice of the target speaker from the mouth video of the target speaker in noisy overlapping speech, combined with a single multi-scale time-frequency separator and an encoder spatial speaker contrast loss, reducing interference speaker leakage without increasing inference cost.

  5. ByteDance Seed · Hugging Face new models

    ByteDance-Seed/GenFirst releases: A generative pre-reconstruction method for stable end-to-end latent generation modeling

    ByteDance-Seed/GenFirst trains a latent VAE and combines it with a generative prior to avoid latent collapse, which usually makes end-to-end training unstable. The two-stage plan of this method is used for prior and entropy weights: the first stage lets the prior shape the latent geometry, and the second stage reduces both weights tenfold, allowing the decoder to recover details.

  6. OpenRouter Blog

    How to Use LLM to Extract Tables from PDFs

    The Anthropic/claude-haiku-5.5 model paired with a strict JSON schema can extract tables from PDFs and return typed rows. Tested five PDFs (including scans) successfully extracted all 644 cells; failure cases were due to PDF processing paths, not model capability. Note empty results and output length limits.

  7. Hugging Face Daily Papers

    EvidenceConnect framework and Zooming without Zooming v2 model released

    The EvidenceConnect framework generates comparative, aggregated, or chained visual evidence queries by synthesizing image region thumbnails, enhancing the evidence connection capability of VLMs. The ZwZ2 model is trained based on this framework, without targeting any downstream benchmarks but improving fine-grained and spatial perception, and achieving progress in embodied spatial reasoning, multimodal long-context understanding, multimodal agent tasks, and general visual reasoning

Oct 28Wed
  1. ITHome · AI65

    Apple iOS 27.2 update photo app: Shared Albums add four new features

    Apple's iOS 27.2 brings two new improvements for the iPhone Photos app, involving shared album features and the ability to recognize AI-generated or edited images. Users can now edit photo descriptions and comments in shared albums, avoid adding duplicate photos, and receive reminders before albums expire; the system also adds support for SynthID digital watermarking to help identify images created or modified using generative AI.

  2. ITHome · AI65

    Huawei Mate 90 Pro series phone second-generation Linglong screen technology revealed

    Huawei adopts a dual-layer OLED architecture Linglong screen on Mate 90 Pro series phones, doubling lifespan at the same brightness, and increasing brightness at the same power consumption; Supports Kirin Zhuque dual-core synergy, Kirin chip achieves high-precision calibration under low brightness, Zhuque chip achieves low-power calibration under high brightness; Mate 90 Pro Max screen supports BT.2020 and Pointer color gamut display, color gamut coverage increases by 30% compared to P3

  3. QbitAI58

    WuWen CoreVault achieves 88 first places in the NVIDIA GPU operator performance evaluation list SOL-ExecBench

    WuWen CoreVault ranks first among all participating teams in the NVIDIA Research GPU operator performance evaluation list SOL-ExecBench with 88 single-item first places, covering four major tracks: L1 basic operators, L2 fusion operators, Quantization operators, and FlashInfer-Bench inference operators. Through containerized isolation architecture, modular Skills, and shared memory mechanisms, combined with refined optimization strategies for different computing scenarios, it achieves the ability of AI to autonomously complete complex operator optimization.

  4. Hugging Face Daily Papers

    Decomposition Vector Quantization Technology Enhances Discrete Visual Token Quality

    Decomposition Vector Quantization Technology enhances discrete visual token quality by using parallel codebooks on complementary feature views, enabling it to match continuous representations in multimodal understanding. Models trained on industrial-grade multimodal data outperform UniAR and Emu3-Chat by 22.8% and 59.2% on average across nine metrics, making it the first discrete representation model capable of competing with strong continuous representation models like Qwen3-VL.

  5. Hugging Face Daily Papers65

    Extended Research on Looped Transformers with Truncated Backpropagation: Should the training loop be truncated?

    Looped Transformers train better than truncated backpropagation with the same computational cost through full backtracking, extended regularity shows that when the model size is adjustable, two loops are the best. Looped Transformers increase computational depth by reusing shared layers without increasing the number of trainable parameters, usually using backtracking training (BPTT), but are often truncated to the last few loops to save training computational cost, which may lead to gradient bias and weaken the loop advantage.

  6. Hugging Face Daily Papers

    OvisOCR3 Technical Report

    OvisOCR3 is a 0.8B visual language model that unifies multiple OCR tasks through multi-mentor distillation and reinforcement learning, achieving SOTA results on document parsing, general OCR, key information extraction, image-text description, and cross-page table reconstruction tasks. It scored 96.74 on OmniDocBench v1.6, ranked first in OCRBench v2 English and Chinese split, and surpassed baseline models in multiple benchmark tests.

  7. Hugging Face Daily Papers65

    LociArt: A Unified Free-Style Local Video Styling Paradigm

    LociArt achieves precise local video stylization through generating refined networks, automated dataset construction, and dedicated benchmarks, supporting regional style control and temporal consistency. GRNStyle introduces a polarity-aware style perception mask on the basis of generating refined networks, combined with representation-geometric conditioning technology. Experiments show that it outperforms existing methods in regional style quality and spatial control. The LociArt-100K dataset contains 100,000 local stylization pairs, the benchmark includes 80 source videos and 84 target masks, using a style prototype similarity evaluation scheme.

  8. Hugging Face Daily Papers65

    HiP3R: Hierarchical Pose Graph for Long-Term 3D Reconstruction

    HiP3R uses hierarchical pose graphs to reconstruct and merge local videos into globally consistent camera trajectories and 3D geometry without retraining. It first optimizes robust block-level Sim(3) graphs to establish global layout and scale, then fixes this layout and estimates shared SE(3) cameras for each frame, converting overlapping window predictions into a single trajectory. Experiments on multiple benchmarks prove HiP3R's effectiveness in improving camera trajectories and 3D reconstruction, and it is applicable to both block-based and streaming backends without additional training or fine-tuning.

  9. QbitAI

    Yinqi has also achieved end-to-end for 4D radar

    Qianli Technology has launched an AI 4D millimeter-wave radar, equipped with a 10 TOPS NPU, supporting local AI perception and satellite architecture parallel output, achieving end-to-end AI processing from antenna design to point cloud output. The radar's point cloud density is enhanced 10 times, detection range is increased by 40%, ghost shadow elimination rate reaches 95%, and spatial angular resolution is improved 12 times. It provides three working modes: edge-side, satellite architecture, and compatible, to adapt to different functional levels and platform requirements.

  10. Hugging Face Daily Papers

    Qwen-Image-PE: Enhances text-to-image prompt enhancement capabilities through a two-stage training process.

    Qwen-Image-PE enhances text-to-image prompt enhancement capabilities through a two-stage training process (based on title reverse distillation and group design rewards). When using Qwen-Image-2.1 on Qwen-Image-Bench, Qwen-Image-PE-397B improves by 7.81 points compared to the original request, and Qwen-Image-PE-9B surpasses all evaluated PE baselines.

  11. AWS Machine Learning Blog34

    How does Property Finder identify evaluation bias on Amazon Bedrock and optimize model costs?

    Property Finder discovered that 96.8% of the labels in its evaluation dataset for visual AI workloads migrated to Amazon Bedrock were predictions from a single model rather than human validation, hindering objective comparison of new models. The company built a trustworthy benchmark dataset by independently labeling 356 images with human experts and, after 27 iterative optimizations with evolutionary prompt tuning, reduced costs by 86% while maintaining an 86% accuracy rate.

Oct 27Tue