Skip to content
Live
Nov 10Tue
  1. Claude.dev Blog85

    Anthropic uses Claude Fable 5.2 to enable 1000 agents to safely collaborate on proving Fermat's Last Theorem

    Anthropic announces a toy experiment: 1000 agents running early versions of Claude Fable 5.2 in a network sandbox, organizing and dividing tasks solely with Git and a shared Postgres database, completing the formal proof of Fermat's Last Theorem in 28.7 hours, outputting tokens one-third of the September version and proof length one-seventh.

    Why it matters: The original complete record shows 1000 agents building collaboration mechanisms and proving Fermat's Last Theorem in a network sandbox, observable how multi-agent scalable collaboration and safety boundaries are designed simultaneously.

  2. AWS Machine Learning Blog38

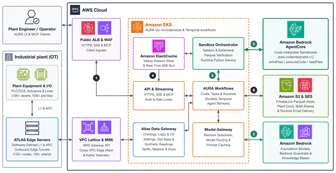
    CrossnoKaye on How to Achieve Industrial Physical AI with Amazon Bedrock AgentCore

    CrossnoKaye achieves industrial physical AI on Amazon Bedrock AgentCore through its ATLAS platform and AURA agent, improving production efficiency by 11-17% and reducing energy consumption by 21%. AURA leverages AgentCore's code interpreter capabilities to run Python workloads in isolated micro VMs to verify numerical calculations, while achieving closed-loop control through edge clusters and cloud optimization systems.

  3. Berkeley AI Research22

    BAIR at CoRL 2026

    BAIR team presented multiple research achievements at the Robot Learning Conference (CoRL) held from November 9 to 12, 2026, in Austin, Texas, including 33 main conference papers, 4 breakthrough posters, 10 oral presentations, and 7 thematic speeches, among which Professor Negar Mehr will deliver an early career keynote speech. The conference covers topics such as robotic vision-language-action models, embodied agents, fine-grained manipulation alignment, and hindsight reward editing.

  4. Latent Space58

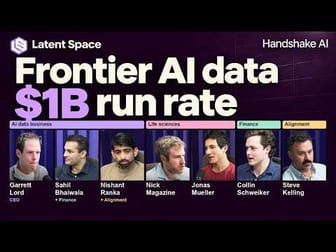
    Frontier Labs purchased Handshake AI data for in-depth analysis.

    Frontier Labs' AI training business reached $1 billion in revenue within a year. Handshake AI demonstrated its intelligent agent evaluation environments in finance, biology, and coding, including bank email processing, brain tumor tissue image recognition, and file access simulation tasks. VIALS, as a benchmark in the biology field, tests the model's ability to understand scientific images.

Nov 9Mon
  1. QbitAI72

    Baidu Wenxin has first disclosed the progress of RSI, and ERNIE Evolve has been used in the development of Wenxin 5.5 Flash.

    Baidu Wenxin first disclosed its automatic research system ERNIE Evolve, which can autonomously propose research directions, conduct experiments, and validate results. It has been used for inference optimization in Wenxin 5.5 Flash. In the low-latency scenario optimization for Kunlun Chip P800, ERNIE Evolve took about 168 hours and went through 4 rounds of direction exploration, with the optimal version's generation speed increasing to 623.6% of the baseline. The deterministic reasoning throughput optimization increased the throughput to 133.7% of the baseline in 3 days.

    Why it matters: Baidu has disclosed the architecture and production environment optimization data of the automatic research system ERNIE Evolve, which can observe the actual landing points of RSI in inference optimization.

  2. Hugging Face Daily Papers34

    LowRAM: A runtime method for low-rank keys and amortized values for composable KV cache compression

    LowRAM compresses keys using low-rank decomposition and uses small head networks to predict key values, while retaining residual correction for the most difficult-to-reconstruct markers, achieving 4x value cache compression with near-lossless performance. Selective reconstruction can increase peak decoding throughput by 5x for 262K context under 4x KV compression. Combining quantization and eviction, LowRAM pushes compression to 26.9x while retaining 94.5% of baseline performance.

  3. Hugging Face Blog45

    HOPE Advanced Pruning Method Released

    The HOPE method achieves better pruning effects in mixed expert language models by considering the second-order interactions between experts. It improves performance by 6.1% over the next best method on the agentic coding task at a 50% pruning rate. This method is validated on models like Qwen3.5-122B, where each MoE layer has 256 experts. After pruning, it can reduce memory usage by about 250 GB and is compatible with quantization.

  4. Hugging Face Daily Papers31

    Deep dive into intelligent agent evolution: What are we overlooking?

    Agent evolution enhances performance through recursive self-improvement (RSI) without updating model weights, but a high baseline score does not always lead to reliable, efficient, and transferable improvements. The study evaluated the performance of four methods on general and coding tasks, finding that all sixteen evolved agents gained new task capabilities but lost some old capabilities. One general task agent improved reliability by 5.2 points but lost ten old tasks. EvoAudit achieved the best performance through analysis, mutation, and gating mechanisms.

  5. MIT News · AI52

    WorldParticle: A single AI model simulates the behavior of multiple materials

    The WorldParticle model can simulate various material behaviors, from sliding sand to folded proteins, by decomposing objects into thousands or millions of three-dimensional particles and using neural networks to predict their motion without needing to write specific equations for each material and process. The model offers higher accuracy than numerical simulation methods in simulating deformable objects, granular materials, and proteins, and can optimize computational efficiency through hybrid techniques.

  6. ITHome · AI65

    Anthropic releases report: Scientists mainly use Claude for data analysis and writing

    Anthropic released a research report showing that scientists primarily use Claude for data analysis and writing, while less frequently using AI for collecting data and generating research hypotheses. The research is based on 207,000 scientific research session data from August to September 2026, with the highest usage rates in the fields of computer science, mathematics, and statistics. Data analysis accounts for 33.7% of Claude's scientific research sessions, while writing and communication account for 32%.

  7. Latent Space42

    How Stanford University Teaches AI Native Engineering - Mihail Eric and Monaco's Practice

    Stanford University's CS146S course has changed assignments to contributing to open-source projects, letting students use AI code review tools and learn collaboration; Monaco company adopts Devin code review tool, while building its own Agent workspace to maintain technical autonomy, and develops Hal system, allowing engineers and salespeople to solve problems through Agents.

Nov 8Sun
  1. ITHome · AI75

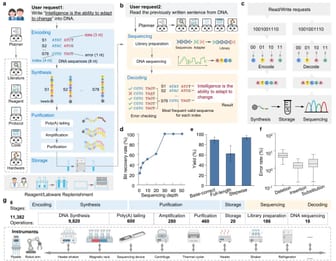
    Shanghai Jiao Tong University's AutoDNA device achieves autonomous molecular biology experiments, results published in Nature

    Shanghai Jiao Tong University's Chen Haibo, Wang Zhao Guo team collaborates with Fan Chun Hai, Wang Fei team to construct AI-native scientific laboratory AutoDNA device (Siyuan No. 1), achieving autonomous molecular biology experiment operations, results published in Nature and featured on the homepage.

    Why it matters: This study combines multi-agent architecture with instrument atomic services, allowing AI to autonomously complete molecular biology experiments, serving as a reference for AI-native laboratory architectures.

  2. The Decoder71

    Alibaba and other teams released Co-Design Bench: coding intelligence agents only fully solve 26.4% of real tasks.

    Researchers from Alibaba and several Asian universities used real user change requests to build the coding intelligence agent benchmark Co-Design Bench. Among the ten tested models, the best-performing GPT-6 Astra only meets about 70% of the task requirements, but only 26.4% of the tasks are completely correct.

    Why it matters: A benchmark display composed of real user requests shows that the strongest model can only fully solve about one-quarter of the tasks, and the score difference for the same model in different environments is nearly 20 percentage points.

  3. Hacker News · 300+71

    MaxxBench release: Model scores show significant divergence after rewriting DeepSWE tasks

    The MaxxBench team made minor changes to 89 DeepSWE tasks (median reference patch added only 17 lines, 3.5%), re-evaluating 15 model configurations, finding the difference between the highest and lowest scores expanded from 20.9 percentage points in DeepSWE to 48.3 percentage points.

    Why it matters: By rewriting the instructions and starting code for 89 DeepSWE tasks, it demonstrates the huge gap in model scores between familiar benchmarks and tasks after modification.

  4. MarkTechPost38

    MoE Routing Strategy Explanation: Top-K, Expert Selection, Sigmoid Gating, and Dynamic Routing (2026 Guide)

    MoE routing strategies determine which experts process each token, affecting model quality, load balancing, and deployment costs. Mixtral uses Softmax Top-K to select 2-8 experts, while DeepSeek-V4-Pro selects 1-8 out of 384. Load balancing is achieved through Sigmoid gating and auxiliary loss, with Sigmoid scoring combined with lossless bias balancing being a common approach for cutting-edge open models in 2026.

  5. ITHome · AI67

    OpenAI GPT-6.1 Sol involved in live mouse brain surgery: Continuous operation three times, positioning error halved

    OpenAI GPT-6.1 Sol performed three consecutive operations in the brain of a living mouse during surgery, improving its localization performance based on surgeon feedback, reducing the time from 169 seconds to 86 seconds, and reducing the localization error from 0.6 mm to 0.3 mm, a 50% reduction in error. The research team had the model participate in localization tasks for two key anatomical landmarks, Bregma and Lambda, on the surface of the mouse skull. Images, data, and correction records were saved after each operation for future reference.

  6. MarkTechPost58

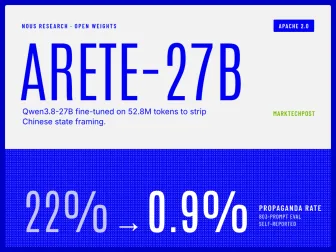
    Nous Research releases Arete-27B, reducing the promotional content of Qwen3.8-27B from 22% to 0.9%

    Nous Research has released Arete-27B, a 27B parameter model with open-weight quantization, which removes promotional content about China from Qwen3.8-27B through supervised fine-tuning. In 803 prompt evaluations, the promotional content ratio decreased from 22% to 0.9%, while retaining the agent skills of the Qwen class and being free from political bias.

  7. Hugging Face Daily Papers65

    VisSearch-Bench evaluates the performance of multimodal agents in long-term visual search

    VisSearch-Bench evaluated the performance of 16 multimodal models on 204 human-written visual search tasks that require integrating visual context with external information, with the results showing that the best system only fully solved 26.47% of the tasks. The benchmark covers 7 major areas, including set-based visual search and sequential visual search, and evaluates task completion and the correctness of reasoning steps through accuracy and process scoring.

  8. Hugging Face Daily Papers24

    From Autonomous Agents to Cognitive Symbionts: Towards AI-Enhanced Human Intelligence

    Physical AI should enhance human intelligence through a lifelong cognitive symbiont, which compensates for cognitive gaps through perception, situational retention, and proactive assistance, requiring embedded governance. Large foundation models and personal agents can already complete multi-step tasks independently, but humans will still forget knowledge, ignore information, and lack historical references, as the machines that can provide help are outside the context.

  9. The Decoder75

    Vals AI benchmark shows the gap in network attack capabilities between open-source and closed-source models continues to narrow

    Vals AI's CyberOffense benchmark allows AI agents to autonomously attack simulated enterprise networks on isolated Kali Linux machines, GPT-6 Sol Daybreak in OpenAI restricted projects completes 80.8% of the target, open-source weighted model Deepseek V4.1 Flash 1017 reaches 72.8%, with a single run cost of about 3 dollars instead of about 22 dollars

Nov 7Sat
  1. The Decoder72

    Why it matters: The original text provides a comparison of the promotional rate and fact accuracy rate before and after fine-tuning, allowing readers to judge whether the political tendency of Chinese open-source models only stays on the surface.

  2. The Decoder78

    Nine AI entities attempt autonomous research on open problems at US national laboratories, none reaching expert standards

    A study made Claude Opus 4.8, Claude Opus 5, Claude Fable 5, Claude Opus 5.5, GPT-5.6 Sol, GPT-6 Astra.

    Why it matters: This benchmark uses 15 unpublished research questions to test 9 agents and provides common failure patterns in 135 submissions, which can be used as a reference for evaluating autonomous research capabilities.

  3. ITHome · AI70

    Google's AI-PPG-ACC-HTN study published in Nature: Using consumer-grade smartwatches to detect hypertension without a cuff

    Google has released a multimodal AI system, AI-PPG-ACC-HTN, which does not require wristband calibration and passively detects persistent hypertension using a standard consumer-grade smartwatch. The results were published in Nature. The study included 196 participants across 5 clinical centers, using 24-hour ambulatory blood pressure monitoring as a reference. Initial screening showed a specificity of 90.0%, a positive predictive value of 80.6%, and a sensitivity of 65.8%. Diagnostic testing showed a positive predictive value of 96.7%, a specificity of 90.9%, and a sensitivity of 78.4%.

  4. The Decoder71

    Google AI detects hypertension using a regular smartwatch without a cuff

    Google Research's AI detects signs of hypertension without blood pressure cuff calibration, using only the pulse and motion sensors already in smartwatches, with related research published in Nature. The neural network learns pulse and heartbeat patterns by comparing short segments from nearly 500,000 hours of sensor data to identify which segments belong to the same person, then averages multi-day data to calculate the probability of hypertension.

    Why it matters: Readers can learn about a smartwatch blood pressure detection study that requires no cuff calibration, and its comparison results with traditional measurements in tests on 196 people.

  5. ITHome · AI67

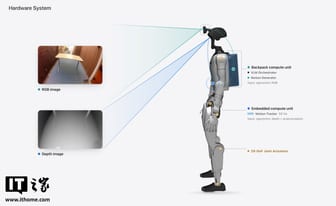
    Apple reveals the humanoid robot system HALO: using the Qwen model to validate on the Yushu G1, achieving an average success rate of 91% for single tasks.

    Apple's research team reveals humanoid robot autonomous control system HALO, with an average success rate of 91% in 360 single task tests in 6 real environments; the system calls the Qianwen model for verification on the Yushu G1, achieving an average success rate of 70% in 10 tests of 3 combinations in a single long sequence compound task, and a success rate of 50% in the most complex task.

  6. Hugging Face Daily Papers65

    Drex open-source decision model released

    Drex open-source decision model returns the probability distribution of user options without autoregressive decoding, using supervised fine-tuning, RLAF, and consistency loss to improve accuracy, robustness, and latency. Its 35B parameter Max version achieves an industry-leading score of 67.52 on Decision Index 0.4.1, with a response time only 9% of GPT-6 Sol and 5% of Claude Opus 5.5.

  7. ITHome · AI62

    Anthropic has not yet released an AI model to help solve major quantum computing challenges

    Anthropic's yet-to-be-released AI model helps the physical research institution PSI prove the Allen-Arnold conjecture, which has not been resolved since it was proposed in 2008 and involves when quantum computers can surpass the computational speed of traditional computers. The research system developed by PSI based on this model completed the proof in just three days, confirming that quantum advantage depends on special laws of the problem. Previously, OpenAI has used AI to solve the Navier-Stokes equation problem.