The DecoderFeatured7171
Why it matters: The original text lists three capabilities: multi-round editing stability, native RGBA output, and text rendering, which can be used to determine its position in the design production process.
The DecoderFeatured7171Why it matters: The original text lists three capabilities: multi-round editing stability, native RGBA output, and text rendering, which can be used to determine its position in the design production process.
 Epoch AI
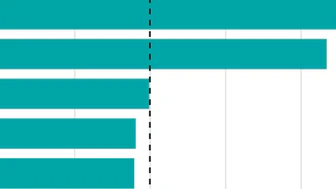
Nvidia GB300 offers a 25-fold improvement in capability compared to H100 for intelligent agent inference tasks, far exceeding the 2.5-fold increase in 8-bit FLOP/s. The IPI index measures inference capability by comparing the number of requests a chip can handle simultaneously under various output speed requirements. GB300 is set as the baseline value of 1, and chips scoring 1 can serve twice as many users under the same conditions. IPI version 1 combines results from four representative models, using GB300 as the reference benchmark.
 Artificial Analysis ArticlesSame story · 4 outlets6666
Muse Ember scores 36, comparable to Claude Haiku 5.5 but with a task cost of only 0.14 USD, two-thirds lower than the latter; its input/output token prices are the same as Claude Haiku 5.5 and GPT-6 Luna, but caching input costs are lower. It scored 68.1% on AutomationBench-AA, comparable to Muse Wonder, but has the lowest knowledge accuracy (21.1%)
 TechCrunch · AIFeaturedSame story · 2 outlets7272
Meta Superintelligence Lab releases lightweight model Muse Ember, priced at 10 cents per million tokens, focusing on high-frequency agent tasks such as tool calling, coding subtasks, routing, extraction, and long document parsing.
Why it matters: Meta uses a pricing of 10 cents per million input tokens and the Artificial Analysis comprehensive benchmark to place the lightweight model in the agent execution context, comparing it with Haiku and Luna.
 MarkTechPost6767
Baidu Launches ERNIE Evolve Automated Research System, Automatically Selects Research Directions, Edits Code, and Runs Experiments Based on Given Codebases, Goals, and Evaluation Criteria, Retaining Only Changes Validated by Hidden Evaluators and Independent Reviewers
 IBM Research Blog5252
IBM will embed the Praxis Policy Engine (PPE) as a policy filter into the open-source AI proxy server Praxis, supporting strategy control over tools, prompts, model calls, etc.
Tencent Mixuan Hy4 is officially released, with a total of 770B parameters and 49B activation parameters. It introduces native visual capabilities and computer operation support for the first time, while also upgrading command compliance, long text understanding, and long-range Agent capabilities. The model has been launched on products such as Tencent Cloud TokenHub, WorkBuddy/CodeBuddy, and Yuanbao. API access has been provided to platforms like OpenRouter, Hermes, and OpenCode, with weights to be open-sourced in the near future.
Why it matters: The author uses multiple long-range tasks to test the autonomous execution and self-check capabilities of the open-source model 'Hunyuan Hy4', thereby judging the actual level of open-source models in Agent delivery.
Shizuku AI releases the full-duplex model Shizuku-Duplex, supporting intelligent Japanese dialogue and initiating thinking processes without complete inquiries. The model performs best in natural Japanese dialogue and has response quality second only to GPT-Live, adopting a combination of front-end interaction and back-end asynchronous processing architecture, supporting three output methods: audio, text, and actions.
Ji Yuan Law Release Agent Native Model NeoHorse-1.5-Flash Preview, based on Qwen3.8-Flash training, 180B total parameters, 6B activation parameters, score improvement in Agents' Last Exam, Natural Language to Repository and other evaluations. This model iterates through recursive self-improvement (RSI) and combines the OpenSquilla platform to achieve differential diagnosis of multiple models and online learning, now open for limited internal testing.
Microsoft filed a patent application, using AI to almost instantly modify live broadcast content and synchronize mouth movements, capable of replacing verbal fillers, stuttering, offensive words, etc., supporting real-time translation, with a delay of 1 to 10 seconds, potential application scenarios include lectures, sports event broadcasts, etc., currently only a patent application, the technology has not yet been authorized.
 Simon Willison3535
Claude Opus 5.5 can complete 3D model conversion in a pure JS + WebGL environment without the Three.js library. User tests show that the code it generates differs from the Three.js version, but the functionality is similar. Developers believe the Three.js version code is easier to understand, but the actual readability difference is not significant.
 MIT News · AI3838
The FLEX platform developed by researchers from MIT and New York University enables robots to infer deep meaning from natural language instructions, enhancing their motion planning capabilities. The platform uses GPT-4o to analyze instruction patterns, allowing robots to avoid electronic devices such as laptops and phones in virtual scenarios without explicit instructions. The entire process takes about five seconds, aiming to help robots understand the underlying intent behind human instructions.
 NVIDIA Newsroom3838
South Korean companies are adopting NVIDIA NemoClaw and OpenShell to accelerate intelligent agent development. Hyundai Motor is exploring NVIDIA NemoClaw blueprints and OpenShell runtime, while AIM Intelligence integrates the Starfort platform with OpenShell to support safe intelligent agents.
LG AI Research Institute has opened the K-EXAONE 2.5 model API for free, allowing any user to use it at no cost for development and research. This self-developed model enhances the capabilities of the intelligent agent through additional training and performs equally well as DeepSeek-V4.1-Flash and GLM-5.3 in benchmark tests such as AutomationBench and SWE-Bench Pro.
Artificial Analysis Articles3838Artificial Analysis Decision Index v2 introduces a new metric rewarding model correctness and calibration confidence, with a 45% benchmark based on a private dataset; Drex Max v1.1 (Nace AI) leads with 73 points, GPT-6 Luna (Max) ranks first among language models with 76 points, but with significantly higher costs and inference time.
Artificial Analysis ArticlesVersion 1.1 of the Artificial Analysis Endpoint Accuracy Index has been released, adding coverage for GLM-5.3 Flash and Muse Spark Open. Among 103 serverless endpoints, 24 scored below the self-hosted reference.
 MiniMax · Hugging Face new models
MiniMax-H3-Image-PE uses prompt expansion (PE) to convert short requests into detailed image descriptions and recommends aspect ratios. It supports two workflows: text-to-image (T2I) and image editing, using fine-tuned FP4 weights from Qwen3.8-27B. The online API can be accessed via platform.minimax.io or platform.minimax.cn, and the documentation provides support in both Chinese and English.
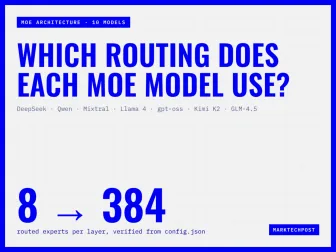
MarkTechPost3838DeepSeek-V4-Pro, Qwen3.6-35B-A3B, and ten other open-source MoE models differ in five aspects: expert count (8B-384B), top-k (1-8), shared experts (7/10 models retained), scoring function (Sigmoid/sqrtsoftplus), and load balancing (Aux loss/bias).
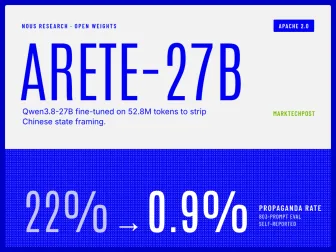
MarkTechPost5858Nous Research has released Arete-27B, a 27B parameter model with open-weight quantization, which removes promotional content about China from Qwen3.8-27B through supervised fine-tuning. In 803 prompt evaluations, the promotional content ratio decreased from 22% to 0.9%, while retaining the agent skills of the Qwen class and being free from political bias.
MarkTechPost6565Use llama.cpp to run the NVIDIA Dory 1.0 4B model, which achieves inference enhancement through repeated intermediate layer calculations. Each additional loop increases computational load without increasing parameters. Build the specified branch of llama.cpp, download the 3.7 GB GGUF file, analyze the parameters and cache consumption per loop, test decoding speed and cache impact, and evaluate accuracy, answer length, and inference time changes with loop counts on GSM8K.
 Codex releases00
Rust 0.169.0-alpha.3 released, including 1 commit.
The Decoder6565Vals AI researchers analyzed the thinking logs of Inkling 2 Small over 2,655 runs on 13 benchmarks and found 50 instances using 'fuck' or its variants, totaling 316 times, with 241 of them coming from two out-of-control runs. In one task, the model generated a single response of 500,000 characters while calculating asteroid trajectories, repeating the same sentence and including 158 instances of profanity. ProgramBench was the most affected, with profanity appearing in 20 out of 200 runs.
 Tencent Hunyuan · Hugging Face new models2222
Qwen3.8-27B-DSpine-b16 pre-trained model released by Mixue, featuring 27B parameters, b16 precision, 5 layers of Draft layers, and an 8,192 token sliding window, designed to improve efficiency during inference and must be used with the Qwen3.8-27B model.
Meta has launched a dedicated version of existing models trained on Muse Wonder, transferring proactive memory and proactive focus capabilities to the Muse and Meta AI dedicated model groups. Muse models have increased the proportion of correct use of key context in 90% of tasks to 76%, and the score of Meta AI models in Meta's 'Personal Super Intelligence Index' has increased from 38% to 47%. New models will be prioritized for subscription users, with subscription prices of $20 per month or $100 per month.
AMD Zen 6 10-core sample scored 3100 single-core and 18313 multi-core in Geekbench 7, 21.5% higher multi-core performance than the 12-core Ryzen AI 9 HX 370; the 8-core sample's multi-core score of 15075 matched the latter, while the 6-core sample's multi-core score of 10670 was 17% higher than the Ryzen AI 5 340.
Google has launched the AI video generation model Gemini Omni 1.2 Flash, natively supporting the longest 15-second video, with a duration limit increased by 50% compared to the previous generation's 10 seconds. Users can set the generation duration from 3 seconds to 15 seconds in 1-second increments.
The DecoderSame story · 4 outlets6565 O'Reilly RadarSame story · 10 outlets2222
Google has released the Gemini 4 Carbon for cybersecurity and multi-step tasks, French Mistral has announced the weights of its 100 billion parameter Large 4 model, and DeepMind has previewed the Genie 4 world model for simulated environments.
The DecoderFeaturedSame story · 3 outlets7373Thinking Machines releases second-generation model Inkling 2 Small, using MoE architecture, with total parameters of 594B and activation parameters of 17B, supporting text and image input and adjustable thinking depth.
Why it matters: The original text provides specific comparisons of the new model in terms of intelligence index, agent tasks, and cost, allowing readers to judge the competitive position of open-source weight models accordingly.
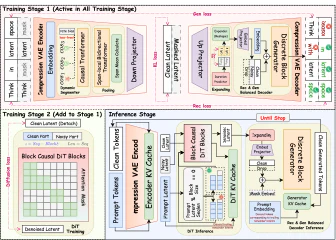
TechCrunch · AI6565ByteDance Seed · Hugging Face new modelsCola2 is a continuous latent language model that combines dynamic compression VAE, block causal diffusion Transformer (DiT), and cross-segment causal token decoder, dynamically grouping text into semantic segments, representing each segment with a compact continuous latent, generating latent blocks and implementing them as discrete tokens.
The Pangram Image 1.0 model locates AI-generated content using heatmaps, achieving an accuracy of 99.96% on a test dataset of 1200 photos. This model can resist the effects of compression, scaling, and artificial modifications, with an accuracy of 96.4% still maintained at 256×256 resolution. The simultaneously released Pangram Image Flash 1.0 video detection model achieves an accuracy of 98.7% on the DF26 dataset, leading the second place by 29 percentage points.
Hugging Face Daily Papers6565BestRand confirms high-probability strong performance of random sampling in benchmark tests through analysis of error distribution, but exists rare large errors leading to instability. The method is validated in over 70 text, multimodal, and agent benchmark tests, reducing high error risk by 50.2% compared to competing methods, decreasing average estimated error by 16.4%, while requiring only 51.3% of the construction cost, and averaging a 21.8% reduction in OOD estimated error.
MarkTechPostFeaturedSame story · 3 outlets7171Thinking Machines Lab released the first model of the second-generation Inkling, Inkling 2 Small, a sparse MoE with 594B total parameters and 17B activation parameters, supporting text and image input and variable inference strength, with a context of 1M tokens.
webAI Launches TwIL-8B Inference Model, Optimized for Math and Code Tasks Based on IBM Granite-4.2-8B, Scores Better than Gemma 4 31B in MATH-500 and AIME 2025 Tests, Best in LiveCodeBench Group, IFBench on Par with Gemma 4 12B. Model Inference Capability Reaches 88~93% of Frontier Models, Reduces AI Usage Costs but Has Limited Knowledge Base.
Taobao MNN team open-sources 0.3B mobile model MNN-Pocket-0.3B, achieving 350 tokens/s on real iPhone 18 Pro offline. The model's peak memory is below 300MB, decoding throughput exceeds 200 tokens/s, INT4 deployment file is 173MB, English IFEval score is 73.20, and Chinese instruction following IFEval-zh score is 74.59.
Ricursive Intelligence releases Ripple-65B Preview model, claiming it has the best agent programming performance in the US open weight model.
MarkTechPostFeaturedSame story · 6 outlets7272Google releases video generation and editing model Gemini Omni 1.2 Flash, natively supporting up to 15-second clips, with 720p video pricing at $0.07 per second, a reduction of about 30% compared to Omni 1.1 Flash