Skip to content
Live
Oct 22Thu
  1. The Decoder70

    Google Cloud starts offering OpenAI models, becoming the only cloud service provider with Gemini, Claude, and OpenAI models

    Google Cloud starts today providing three OpenAI models: GPT-6 Astra (for coding and research), GPT-6.1 Sol (similar performance but cheaper), and GPT-6 Luna (fast and cost-efficient), becoming the only cloud service provider to offer Gemini, Claude, and OpenAI models simultaneously. Currently, it is open for enterprise customers to register in private preview form, with costs included in existing Google Cloud contracts.

    Same story · 2 outlets

    How the accounts differ:OpenAI News mentions the integration with Gemini's Model Garden and Google Cloud Marketplace; The Decoder specifies the models GPT-6 Astra, GPT-6.1 Sol, and GPT-6 Luna being offered with pricing details.

Oct 21Wed
  1. The Decoder47

    How Mistral and Nvidia use physics AI to accelerate industrial design

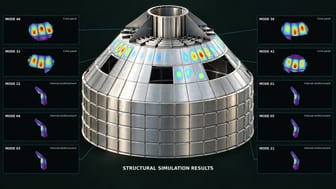
    Mistral and Nvidia join forces to combine Mistral Large 4 with physics AI, CUDA-X, Warp, and Omniverse, providing an integrated workflow for design, simulation, and AI training for the aerospace, automotive, and semiconductor industries. Mistral Large 4 has approximately one trillion parameters and is trained on 3800 Grace Blackwell GPUs, with plans to release as an open-weight model at the end of October.

  2. Modal Blog75

    Modal Dojo: A library to easily start production-level LLM training.

    Modal Dojo is a library for easily performing production-level LLM training, supporting models from 500 million to 10 trillion parameters, providing automatically optimized training recipes and built-in observability dashboards. Users can select models, load data, and start training through simple prompts, supporting data sources such as Hugging Face and Harbor environments, and can adjust recipes through parameters.

  3. IBM Research Blog

    IBM vLLM-Hook MIA Plugin enables rapid runtime monitoring and control

    IBM releases vLLM-Hook MIA Plugin, implementing runtime monitoring and control in the vLLM inference engine, 20 times faster than its predecessor vLLM-Hook and 14 times faster than similar methods inserting code inside the model, with only a 2%-6% increase in latency. The plugin allows developers to observe and adjust model states in real-time, such as rejecting malicious prompts, marking hallucinatory facts, or editing response tone and accuracy, while almost not reducing performance.

  4. NVIDIA Blog42

    European leaders are adopting NVIDIA Vera CPUs to build local infrastructure.

    Nebius and Nscale, among other global technology partner programs, are using NVIDIA Vera CPUs to build next-generation infrastructure to meet the rapidly growing demand for agent computing. Vera CPUs enhance response speed and optimize data center computing power by accelerating tasks such as agent information retrieval, software tool operation, code execution, and result evaluation, while maintaining high efficiency even when running thousands of tasks in parallel.

  5. NVIDIA Blog62

    NVIDIA expands Agent Toolkit to enable enterprise agents to access company data

    NVIDIA expands its open-source Agent Toolkit, adding components such as Agent Knowledge Foundation, the OpenShell secure runtime, and the NemoClaw blueprint, enabling enterprises to customize and govern agents with their own data.

    Why it matters: The original article lists the new components of Agent Toolkit and details of deployments at multiple enterprises, showing how enterprise agents connect to their own data and are constrained by the runtime.

  6. Mistral AI50

    Mistral collaborates with NVIDIA to advance AI in engineering

    Mistral is collaborating with NVIDIA to integrate AI models with NVIDIA accelerated computing and physics modeling tools, accelerating engineering simulations and enabling closed-loop AI-driven design. The collaboration will launch public benchmarks and open datasets, standardizing the evaluation of physics and agent AI in computer-aided engineering, and leveraging NVIDIA Omniverse for 3D simulations and resource creation.

  7. NVIDIA Blog55

    NVIDIA Confidential Computing expands, providing secure extension capabilities for cutting-edge model builders across global infrastructure

    NVIDIA Confidential Computing protects models and data execution through hardware root isolation and encrypted authentication, adding Confidential Bare Metal deployment options, enabling cutting-edge model builders to run sensitive workloads on third-party infrastructure while retaining model data control.

  8. NVIDIA Blog38

    NVIDIA cuDSS is now generally available, accelerating engineering and scientific simulations.

    NVIDIA cuDSS is generally available, migrating large sparse system of equations solvers to GPUs as part of the CUDA-X library, shortening simulation runtimes and improving throughput. Applied Materials achieves up to 10x acceleration in Ginestra, Dassault Systèmes reports 8-10x improvement in Abaqus, and ZEISS SMT completes an EUV lithography plasma simulation benchmark in COMSOL 4x faster.
  9. NVIDIA Blog58

    NVIDIA European partners expand computing capabilities, building sovereign, open, and secure AI agent cloud ecosystems.

    NVIDIA European partners are expanding regional computing capabilities to support model training and inference, helping developers build agentic and physical AI applications. Nscale achieves 37% more GPUs and 50% higher inference throughput using the NVIDIA DSX platform, Crusoe develops a liquid-cooled AI factory for low-latency inference, and Nebius adopts the NVIDIA Groq 3 LPX to accelerate sensitive applications.

  10. NVIDIA Blog

    NVIDIA showcased its full lineup of local AI hardware: RTX Spark, DGX Spark, and DGX Station, helping to power next-generation intelligent agents.

    NVIDIA showcased its full lineup of local AI hardware at GTC Berlin, with RTX Spark now available to support personal agents on Windows PCs, DGX Spark enabling developers to build and scale Linux applications, and DGX Station designed for Linux enterprise teams to run cutting-edge workloads, with the Windows version launching in December.

  11. QbitAI

    Tsinghua AIR incubates Zijing Zhikang: Multi-intelligent agent collaboration reconstructs medical AI, doctor AI avatar 'consults' hospitals

    Zijing Zhikang's 'Zijing AI Hospital' system has been tested in hospitals nationwide, allowing doctors to have AI avatars and achieve cross-departmental collaboration through multi-avatar intelligent agent collaboration technology. AI avatars can simulate diagnosis and treatment in virtual environments and evolve by combining real cases, enabling doctors to make decisions based on suggestions from different avatars. The system achieved 96% accuracy on the MedQA dataset and has been tested in 18 departments at Beijing Tsinghua Changgeng Hospital, improving diagnostic efficiency by 30%.

  12. Databricks Blog

    Databricks AI Runtime officially released

    Databricks releases AI Runtime (AIR), bringing managed GPU infrastructure directly into its platform, allowing customers to train high-demand models at their enterprise data location. AIR provides GPU infrastructure, developer tools, and data governance features, supporting large-scale training, rapid iteration, and load safety, with customers not needing to manage a separate GPU stack.

  13. NVIDIA Technical Blog75

    NVIDIA Sentry: A Runtime Security AI Agent Framework

    The NVIDIA Sentry framework prevents AI agents from bypassing security boundaries by monitoring them externally at runtime. The framework can monitor the tools, credentials, and services used by the agents, ensuring they do not compromise security controls while completing their objectives. NVIDIA Sentry, as a security software framework, is designed to protect AI agents, preventing them from tampering with or disabling monitoring mechanisms.

  14. AWS Machine Learning Blog38

    How Amazon Quick and Amazon Bedrock AgentCore implement conversational intelligent decision-making in supply chains

    Amazon Quick combined with Amazon Bedrock AgentCore provides supply chain teams with real-time data access across systems. Users can get cross-system answers in seconds through conversational queries, such as identifying high-income SKUs and costs affected by port closures. Quick serves as the interface layer, and AgentCore as the intelligence layer, connecting backend systems like ERP, monitoring, and procurement via the MCP protocol to achieve a complete process from problem discovery to generating emergency purchase requests, all operations requiring manual confirmation.

  15. The Decoder72

    Mistral AI has released the real-time voice intelligence stack Voxtral 3.

    Mistral AI has released the real-time voice intelligence stack Voxtral 3, including a speech-to-text model (Voxtral Small Transcribe 3), a text-to-speech model (Voxtral Mini TTS 3), and a voice intelligence SDK based on LiveKit.

    Same story · 2 outlets

    How the accounts differ:The Decoder mentions a text-to-speech model (Voxtral Mini TTS 3) that is not detailed in the first report.

  16. The Decoder72

    DeepSeek open-source reasoning engine DeepInfer supports high-speed, low-cost operation of V4.1-Flash

    DeepSeek open-sources its internal reasoning framework DeepInfer under the Apache License 2.0, a service software that supports the large-scale and fast answer generation of the V4.1-Flash model.