Skip to content
Live
Oct 21Wed
  1. Modal Blog75

    Modal Dojo: A library to easily start production-level LLM training.

    Modal Dojo is a library for easily performing production-level LLM training, supporting models from 500 million to 10 trillion parameters, providing automatically optimized training recipes and built-in observability dashboards. Users can select models, load data, and start training through simple prompts, supporting data sources such as Hugging Face and Harbor environments, and can adjust recipes through parameters.

  2. IBM Research Blog

    IBM vLLM-Hook MIA Plugin enables rapid runtime monitoring and control

    IBM releases vLLM-Hook MIA Plugin, implementing runtime monitoring and control in the vLLM inference engine, 20 times faster than its predecessor vLLM-Hook and 14 times faster than similar methods inserting code inside the model, with only a 2%-6% increase in latency. The plugin allows developers to observe and adjust model states in real-time, such as rejecting malicious prompts, marking hallucinatory facts, or editing response tone and accuracy, while almost not reducing performance.

  3. NVIDIA Blog55

    NVIDIA Confidential Computing expands, providing secure extension capabilities for cutting-edge model builders across global infrastructure

    NVIDIA Confidential Computing protects models and data execution through hardware root isolation and encrypted authentication, adding Confidential Bare Metal deployment options, enabling cutting-edge model builders to run sensitive workloads on third-party infrastructure while retaining model data control.

  4. NVIDIA Blog38

    NVIDIA cuDSS is now generally available, accelerating engineering and scientific simulations.

    NVIDIA cuDSS is generally available, migrating large sparse system of equations solvers to GPUs as part of the CUDA-X library, shortening simulation runtimes and improving throughput. Applied Materials achieves up to 10x acceleration in Ginestra, Dassault Systèmes reports 8-10x improvement in Abaqus, and ZEISS SMT completes an EUV lithography plasma simulation benchmark in COMSOL 4x faster.

    Same story · 2 outlets

    How the accounts differ:NVIDIA Blog states ZEISS SMT achieved a 4x speedup with COMSOL for EUV lithography plasma simulation; NVIDIA Newsroom mentions a 10x speedup for COMSOL with cuDSS.

  5. NVIDIA Blog58

    NVIDIA European partners expand computing capabilities, building sovereign, open, and secure AI agent cloud ecosystems.

    NVIDIA European partners are expanding regional computing capabilities to support model training and inference, helping developers build agentic and physical AI applications. Nscale achieves 37% more GPUs and 50% higher inference throughput using the NVIDIA DSX platform, Crusoe develops a liquid-cooled AI factory for low-latency inference, and Nebius adopts the NVIDIA Groq 3 LPX to accelerate sensitive applications.

  6. NVIDIA Blog72

    Google Cloud and NVIDIA announce Vera Rubin infrastructure now available

    Google Cloud and NVIDIA announce A5X instances based on NVIDIA Vera Rubin now available, opening next month and planned to expand to Europe.

    Why it matters: The original text provides the availability time of A5X instances, customer testing, and confidential computing support, allowing readers to judge the implementation rhythm of large-scale reinforcement learning infrastructure.

  7. NVIDIA Blog

    NVIDIA showcased its full lineup of local AI hardware: RTX Spark, DGX Spark, and DGX Station, helping to power next-generation intelligent agents.

    NVIDIA showcased its full lineup of local AI hardware at GTC Berlin, with RTX Spark now available to support personal agents on Windows PCs, DGX Spark enabling developers to build and scale Linux applications, and DGX Station designed for Linux enterprise teams to run cutting-edge workloads, with the Windows version launching in December.

  8. Databricks Blog

    Databricks AI Runtime officially released

    Databricks releases AI Runtime (AIR), bringing managed GPU infrastructure directly into its platform, allowing customers to train high-demand models at their enterprise data location. AIR provides GPU infrastructure, developer tools, and data governance features, supporting large-scale training, rapid iteration, and load safety, with customers not needing to manage a separate GPU stack.

  9. NVIDIA Technical Blog65

    How NVIDIA OpenShell Reference Architecture Ensures Security and Governance for AI Agent Workloads at Scale

    NVIDIA OpenShell Reference Architecture ensures the security of AI agent workloads at scale by defining security boundaries and governance policies. The architecture allows agents to access files, tools, and the internet while performing complex tasks and enables dynamic collaboration. It mitigates risks associated with long-running agents through enhanced access control, audit logs, and permission management.

  10. NVIDIA Blog67

    NVIDIA GTC Berlin 2026: Huang Renxun announces multiple updates including DSX POD, OpenShell, and Nemotron.

    NVIDIA CEO Huang Renxun announced multiple updates at the GTC Berlin 2026 keynote speech, including the Vera Rubin AI factory reference design DSX POD delivered in modular container format, reducing on-site deployment time from six months to 14 days.

    Why it matters: Huang Renxun's keynote speech at GTC Berlin revealed the latest developments in three product lines: AI factories, secure runtime for agents, and open-source models, providing insights into NVIDIA's focus in Europe.
  11. Tessl Blog75

    Jellyfish Analysis: The review bottleneck of AI coding agents restricts development efficiency

    22% of the PRs of Median Company are completed by AI coding agents, with 90% reaching 53%, but only 0.6% of the PRs are reviewed and merged by AI, with 10% reaching 9%. The abandonment rate (40%) of code generated by agents is twice that of manual (20%), and the review volume increases after merging. The leadership faces ROI issues, as the upstream code generation acceleration (2x PR growth) far exceeds the downstream output (40-50% feature growth), with the review bottleneck becoming a constraint factor.

  12. AWS Machine Learning Blog58

    vLLM enhances the TTFT performance of multi-round agent workloads through bidirectional KV transmission.

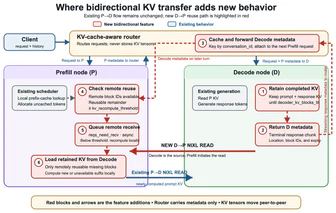
    vLLM's bidirectional KV transmission mechanism reduces redundant calculations by allowing the decoding node to return previously computed KV cache to the pre-filled node in subsequent dialogue turns. In multi-round benchmark tests on AWS EC2 P5en instances, it improved the TTFT of Qwen3-32B by 1.6x and zai-org/GLM-5-FP8 by 3.3x. This feature is implemented by extending the NIXL KV connector and utilizing a KV cache-aware router to coordinate KV reuse across dialogue turns.

  13. AWS Machine Learning Blog38

    How Amazon Quick and Amazon Bedrock AgentCore implement conversational intelligent decision-making in supply chains

    Amazon Quick combined with Amazon Bedrock AgentCore provides supply chain teams with real-time data access across systems. Users can get cross-system answers in seconds through conversational queries, such as identifying high-income SKUs and costs affected by port closures. Quick serves as the interface layer, and AgentCore as the intelligence layer, connecting backend systems like ERP, monitoring, and procurement via the MCP protocol to achieve a complete process from problem discovery to generating emergency purchase requests, all operations requiring manual confirmation.

  14. GitHub Blog · AI & ML33

    How GitHub Copilot continues a session in VS Code

    GitHub Copilot users can directly open a GitHub Copilot app session in VS Code to continue their conversation, code changes, and context. Users can review Copilot's modifications line by line, make manual edits directly in VS Code, and run and validate the project locally. The session and code workspace remain connected, supporting interactive iterative optimization with Copilot, and finally submitting updates to the associated pull request.

  15. The Decoder72

    DeepSeek open-source reasoning engine DeepInfer supports high-speed, low-cost operation of V4.1-Flash

    DeepSeek open-sources its internal reasoning framework DeepInfer under the Apache License 2.0, a service software that supports the large-scale and fast answer generation of the V4.1-Flash model.

  16. TechCrunch · AI55

    Yelp launches Check for Me feature, which allows users to call restaurants to check wait times on their behalf

    Yelp adds Check for Me feature, allowing users to input the number of people and phone number within the app, with AI making calls to restaurants to inquire about wait times and sending results via SMS; simultaneously updates AI assistant integration with OpenTable to support bookings, and enhances personalized and historical record features; launches paid product Smart Lead Reply to help businesses automatically reply to customers and filter potential leads, charging $30 per month.

  17. TechCrunch · AI

    Google releases open-source PyTorch version TorchTPU to attack Nvidia AI developer ecosystem

    Google announced the release of its highly anticipated PyTorch version TorchTPU as an open-source project, allowing AI application developers to run their applications on Google's Tensor Processing Units (TPUs) chips.

    Same story · 2 outlets

    How the accounts differ:MarkTechPost states TorchTPU is a native PyTorch backend for cloud TPU designed to replace PyTorch/XLA and supports eager-first execution; TechCrunch mentions it as an attack on Nvidia's AI developer ecosystem.

  18. Databricks Blog

    Deploy RFD4-Proteina on Databricks

    Databricks has integrated the RFD4-Proteina model into Genesis Workbench, supporting execution in AI runtime environments and connecting research data and workflows. Developers can build and adjust pipelines using Genie Code and the NVIDIA BioNeMo Agent Toolkit, leveraging serverless NVIDIA GPU computing for protein design.

  19. vLLM Blog60

    vLLM supported the Recursive Flint model on the first day.

    vLLM announced support on the day Flint was released, with both NVFP4 and BF16 checkpoints capable of running on a single GPU, decoding approximately 500 tokens/s per request on a single GB200 with a context of 100,000 tokens.

    Why it matters: The original text provided Flint's day-0 support on vLLM, single-card throughput data, and the step-by-step kernel optimization process, allowing readers to judge the engineering trade-offs of small-batch inference based on this.

  20. Google Developers Blog

    Agents CLI Extension System: Supports the intelligent agent development lifecycle across frameworks.

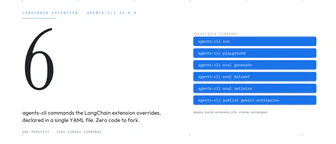
    Agents CLI 1.5.0 version introduces an extension system, allowing developers to override or add commands without modifying the tool, supporting cross-framework usage; the official LangChain extension replaces framework-bound commands while retaining other lifecycle functionalities; developers can create custom extensions, such as adding deployment commands for software bill of materials (SBOM) scanning, enabling enterprise platform teams to enforce governance policies.

  21. Browser Use38

    Browser Use Cloud MCP Server introduction

    Browser Use Cloud MCP servers support proxies to submit complete web tasks in plain text form, which are processed by their cloud browser agents. The cost is $0.02 per hour, and up to 10 projects can run simultaneously. This service uses API V3, offering 11 model selections. The browser is a reinforced version of Chromium, with incognito mode and Cloudflare proxy support enabled by default.

  22. AWS Machine Learning Blog38

    Smartsheet MCP on AWS has launched the Universal Model Context Protocol (MCP) server.

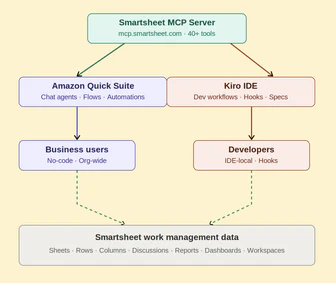
    Smartsheet launches the Universal Model Context Protocol (MCP) server, enabling AI assistants to read and write manage Smartsheet data through a standardized protocol; supports Amazon Quick and Kiro connections, Quick for knowledge workers and operations teams to naturally query and update Smartsheet with natural language, Kiro allows developers to refer to project specifications and update task status without leaving the coding environment.