Skip to content
Live
Oct 19Mon
  1. Together AI Blog

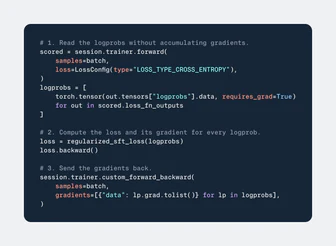
    Together Post-Training: Flexible and efficient model fine-tuning service

    Together AI has launched Post-Training services, supporting the construction of custom models through reinforcement learning and supervised fine-tuning without complex infrastructure. The service provides flexible training loop definition capabilities and optimizes the underlying system and infrastructure to improve model quality and training speed. It supports mainstream open-source models such as Muse Spark Open, GLM 5.3, Kimi K3, and Qwen 3.8-27B, running on dedicated GPU resources to ensure efficient and numerically consistent training.
Oct 17Sat
  1. Google Research

    Google Research explores combining AI agents with biological reality to build autonomous wet labs.

    Google Research releases the VERID framework, enabling AI agents to run in physics-based, safe, and resource-efficient experiments; demonstrates closed-loop intelligent agent scientific discovery on adapter and de novo protein design prototypes; through three rounds of design-test-iterate cycles, AI-driven rational and de novo design will increase confirmed target hit rates to 33.5% and 42.1% on myoglobin and α-thrombin, respectively.

Oct 16Fri
  1. Tencent Hunyuan · Hugging Face new models

    Qwen3-8B-DSpine-b16 released: Speculative decoding model with parallel drafting and deep conditional injection

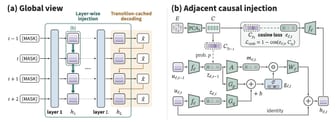
    Qwen3-8B-DSpine-b16 released by Qwen, employing speculative decoding technology with parallel drafting and deep conditional injection, achieving an average acceptance length score of 10.55 on Qwen3-8B. The model supports a context length of 8192 tokens, uses bfloat16 data type and fa3 attention backend, installation requires git clone and pip install, and runs via sglang serve.

  2. LangChain Blog

    LangChain blog: Frequently Asked Questions about Agent Evals

    The LangChain blog introduces how to use Agent Evals to test AI agent behavior, including analyzing behavior through trace logs, building test datasets containing inputs and expected outputs, running offline benchmark tests (such as Terminal-Bench) and online real-time evaluations, as well as using four types of evaluators: code inspection, LLM scoring, and manual review. Offline evaluations are used to test new prompts or models and catch regression issues, while online evaluations are used to monitor production quality and discover dataset gaps.

  3. Microsoft AI News

    Microsoft AI has released an 80 billion parameter MoE large model MAI-Base-2.

    Microsoft AI has completed the pre-training of a new MoE large model MAI-Base-2, with 80 billion active parameters and 2.8 trillion total parameters, surpassing all open-source models in internal evaluations. The model is 4-12 times more efficient in pre-training FLOPs than the strongest open-source base model DeepSeek-V4-Pro-Base and is used to train larger models. Microsoft plans to license the model weights through Foundry using organic data pre-training and full-stack control.

  4. Microsoft Research

    Magnetar achieves provable general computation

    Magnetar proves that programs written in Rust, Go, or C are, on average, 10 to 39 times faster than the fastest comparable systems, and achieves security solely by relying on standard hash functions, solving the three major challenges of zero-knowledge proofs: efficiency, generality, and usability. It significantly reduces proof overhead by leveraging repetitive computations and early termination of the proof process, making proof generation as routine as running a program, and can be used in scenarios such as AI agent behavior verification and financial transaction validation.

Oct 15Thu
  1. Mistral AI

    Mistral AI launched the Timestral time series foundational model family

    Mistral AI released the Timestral time series foundational model family, with the smallest model at only 209M, ranking first in three major benchmark tests (GIFT-Eval, TIME, and fev-bench), outperforming models with larger parameter sizes; this series includes four sizes ranging from 5M to 209M parameters, supports past and future covariates, runs efficiently on CPUs, and can be fine-tuned for specific domains via Mistral Forge.

  2. Apple Machine Learning Research

    Selection-Based Structured Reasoning: A framework for efficient multimodal search agents

    The Selection-Based Structured Reasoning (SSR) framework restructures reasoning into selection rather than open-ended generation, selecting the most likely solution from predefined reasoning candidates before each action, significantly reducing reasoning costs. Validated using 2B and 4B models on seven multimodal search benchmarks, SSR achieved average success rates comparable to leading search agents of the same scale, reducing single-step reasoning latency by 90% and total reasoning latency per task by 28-54%.

  3. Google Developers Blog

    How to evaluate AI agents: Beyond sensory checks.

    Evaluating AI agents cannot rely solely on perception checks, as agents may fall into retry loops or produce hallucinatory responses that still appear normal, leading to soaring cloud costs and token usage. A repeatable evaluation process should be established, starting with defining key user journeys (CUJ), using simulated user testing, and employing multiple layers of checks such as unit tests, deterministic metrics, LLMs as judges for scoring standards, and integration tests. Combining manual review tracking with automated validation can detect latent regressions early in development and expand the evaluation framework as agent capabilities grow.

  4. Apple Machine Learning Research

    MLX and RDMA implement local and distributed large language model inference on Mac Studio

    On a cluster of four Mac Studio machines, Muse Spark Open (816B parameters) generates at a speed of over 36 tokens/second. The Mac Studio M5 Ultra version offers 4.6x faster inference speed (TTFT) and 1.6x faster tokens/second compared to the M3 Ultra, benefiting from the GPU neural accelerator and 1.2 TB/s memory bandwidth.

  5. Google Developers Blog

    Google OAuth Launches DPoP Support: Protecting Refresh Token Security

    Google OAuth Platform Launches DPoP Support, Encrypting Refresh Tokens and Client Key Pairs at the Application Layer to Prevent Token Theft and Replay Attacks. This scheme uses DPoP only for constrained long-lived refresh tokens, ensuring they cannot be replayed even if stolen, while short-lived access tokens remain standard Bearer tokens to maintain high performance. DPoP works with DBSC to defend against API and web session credential theft, but note the key sharing challenges in multi-agent workflows.

  6. Mistral AI · Hugging Face new models

    Mistral AI releases Timestral-123M time series base model

    Mistral AI releases Timestral-123M time series base model, with 123M parameters, using a patch-based Transformer architecture, context length of 32,768 time steps, single prediction covers 1,024 time steps, outputs 21 quantiles. The model achieves optimal accuracy in zero-shot prediction on GIFT-Eval, TIME, and fev-bench evaluations, and is licensed under the Modified MIT License.

  7. LangChain Blog

    How LangChain Deep Agents Manage Context Windows Through Middleware

    LangChain Deep Agents manage context windows through middleware, preventing unnecessary information from entering and filtering existing content. It employs techniques such as offloading (saving large tool results and user messages to files), summarization (compressing old messages), skills (loading on demand), sub-agents (separating noisy tasks), and long-term memory (preserving learning across sessions). These techniques are implemented by inserting middleware at critical points like model calls and tool calls, allowing users to use them without writing code.

  8. Google Research

    Deep Review: Google's intelligent document verification system

    Google has launched the Deep Review intelligent document verification system, providing rigorous feedback and technical validation for complex documents, supporting PDF and plain text input, offering 2 free reviews per week, and integrating advanced API, collaborating with 4 top computer conferences such as STOC 2026 and ICML 2026, processing over 16,000 pre-submission feedbacks for papers.

Oct 14Wed
  1. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/Ling-3.0-flash-UBTree released: Speculative decoding model based on UBTree technology

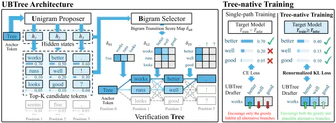
    inclusionAI released the Ling-3-Flash-UBTree-B16 model, combining a five-layer DFlash backbone and a learned bigram selector, proposing multiple candidate continuations for Ling3-Flash for target model validation, with 482M parameters, achieving 3x+ E2E speed improvement on benchmarks like MMLU, and the UBTree adaptation is not yet open source, with SGLang integration support expected to be released soon.

  2. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/Ming-3.0-asr-tiny released: Context-aware speech recognition model supporting multiple language dialects

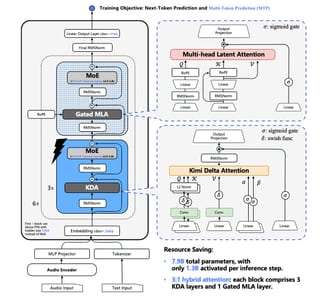
    inclusionAI/Ming-3.0-asr-tiny combines Ling-tiny-v3 language backbone and audio encoder, supporting single-round Chinese and English speech transcription and recognition of 15 dialects, improves professional term recognition rate through hot words or dialogue context, model parameter size not mentioned, evaluated in noisy speech and 5 application areas, provides PyTorch/Transformers inference examples and MIT license.

  3. NVIDIA Blog

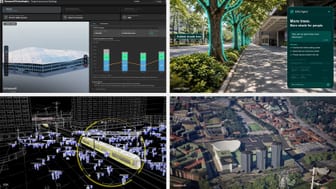
    Multiple cities in Europe have deployed NVIDIA-driven AI agents to improve urban operational efficiency.

    Multiple cities in Europe, along with software, infrastructure, and integration partners, are using NVIDIA's accelerated computing to build physical AI agents and digital twin systems to optimize urban operational decisions. These applications can predict maintenance needs, guide urban planning, and enhance public service response capabilities, involving Belgium, Finland, France, Italy, Netherlands, Poland, Sweden, and the UK.

  4. StepFun · Hugging Face new models

    Step-5-Preview-NVFP4 model release by LeapX Stars

    LeapX Stars releases flagship model Step-5-Preview-NVFP4, with 600B total parameters and 27B active parameters, supporting up to 1M context windows, excels in software engineering, professional knowledge work, and financial fields, capable of processing text, images, and video, deployable via OpenAI-compatible API or offline generation.

  5. Google DeepMind

    Google DeepMind releases Gemini 4 Argon and emphasizes security protection

    Gemini 4 Argon demonstrates cutting-edge capabilities in coding, finance, law, and other fields, particularly enhancing cybersecurity defense functions. Its effectiveness has been validated through the Fairwind project and internal testing. The model performs excellently on benchmark tests like MMLU and employs a three-layer real-time protection mechanism (input filtering, internal introspection, continuous monitoring) and automated bias monitoring, significantly reducing the risk of harmful requests and violations. It successfully intercepts over 99% of external biosecurity jailbreak attempts while reducing shortcut behavior in coding tasks to 2%.

  6. GitHub Blog · AI & ML

    GitHub's secret detection model: Discover more secrets with less noise

    GitHub released a dedicated secret detection model that combines a fine-tuned ModernBERT classifier with regular expressions, reducing false positives by 11.5% while achieving a higher acceptance rate and shortening post-push scan execution time by 86%, with a cost reduction of 98%. The model distinguishes real credentials from similar items by analyzing file paths, variable names, and contextual code, making general secret detection extendable to push protection possible.

  7. Google DeepMind

    Gemini 4 Argon brings breakthrough progress to robotics technology

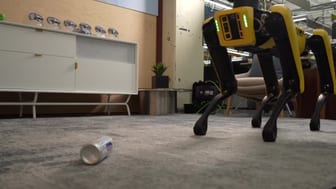
    Gemini 4 Argon has achieved major breakthroughs in physical understanding, code generation, and visual semantic reasoning, achieving a pure reasoning score of 87% on the Embodied Reasoning (ERQA) benchmark test, surpassing all leading models. Argon can be applied to all stages of the robot's lifecycle, including mobile manipulation practice using MuJoCo, zero-shot robot control, and closed-loop steering of video world models.