Skip to content
Live
Aug 31Mon
  1. Ollama Blog58

    Ollama introduces a transparent pricing model based on tokens

    Ollama's Pro, Max, and Team plans now adopt a transparent token-based pricing, including usage limits per month. The Pro plan is $20 per month (including a $60 credit), Max is $100 per month (including a $300 credit), and Team is $500 per month (including a $1000 shared credit). The free plan offers a small initial model credit, which can be expanded on a pay-as-you-go basis.

Aug 27Thu
  1. Dify Blog

    Dify launches a new intelligent agent (New Agent), enabling independent configuration and cross-workflow reuse.

    Dify launches a new intelligent agent (New Agent), where each agent has independent configuration and lifecycle, supporting one-time construction and reuse across workflows. This agent can be published as a web application or exposed via API, featuring three core functions: the ability to build and optimize with real tasks, unified cross-workflow management to reduce repetitive maintenance, and full observability for single-run tracking and long-term monitoring.

Aug 26Wed
Aug 25Tue
Aug 19Wed
Aug 14Fri
Aug 13Thu
  1. Factory News75

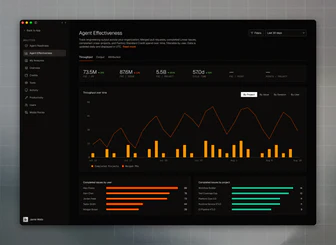
    Factory introduces Agent Effectiveness for integrated usage and delivery outcomes

    Factory's Agent Effectiveness feature is now live, linking data with delivery cycles, work intentions, and delivered outcomes to help engineering leaders understand delivery acceleration points, robot work content, and how usage maps to actual output. This feature provides an operational view of AI investment return by connecting Droid usage with delivery results, addressing questions about delivery speed changes, profit concentration points, and whether new capabilities are used for priority work.

Aug 5Wed
Aug 3Mon
Jul 30Thu
  1. LangChain Blog62

    LangSmith has launched the public beta version of LLM Gateway, providing runtime control for production agents.

    LangSmith LLM Gateway has entered public beta, serving as a centralized governance layer between agents and models, uniformly executing spending limits, rate limiting, model fallback, and sensitive data deidentification. Spending and rate limiting can be set at four levels: organization, workspace, API key, and user. When the limit is hit, the agent receives a 402 response; fallback rules can take effect uniformly across models and hosting providers.

    Why it matters: The original text listed the specific control levels of the gateway in terms of cost, rate limiting, fallback, and data masking, which can help determine at which level the governance of the production intelligent agent should be placed.

Jul 27Mon
Jul 24Fri
Jul 22Wed
Jul 21Tue
Jul 20Mon
Jul 17Fri
Jul 14Tue
Jul 10Fri
Jul 9Thu
  1. Microsoft AI News

    MAI integrates Audible poetry into audio models, creating a digital poetry experience.

    MAI's audio model Ode Poetry recommends and plays real human reading recordings of poems for users worldwide, providing a digital poetry experience. The system uses MAI-Transcribe to understand user language in real-time, achieving the lowest word error rate of 4.86% in the FLEURS benchmark test; MAI-Voice can faithfully reproduce the unique voice of William Sieghart. The system combines William's literary analysis experience, recommends poems through custom logic and tool calls, and iteratively optimizes for a safe, high-quality user experience.

  2. Dify Blog

    Dify Official CLI: difyctl Released

    Dify has released its first official command-line tool, difyctl, which supports calling Dify applications and workflows in terminals, scripts, CI pipelines, or intelligent agents like Claude Code, Codex, and Cursor to achieve automation and integration. difyctl is cross-version across Enterprise, Cloud, and Community editions, providing a unified command set without the need for custom integration code. It supports login via Dify accounts or external SSO and is available in the Enterprise version.

Jun 30Tue
  1. Cognition Blog

    The Cognition team has launched Devin Fusion: achieving cutting-edge performance at 60% lower cost.

    Devin Fusion maintains cutting-edge and Fable 5-level performance at 60% lower cost on the new coding benchmark FrontierCode, primarily through a dual-agents architecture that runs cutting-edge models in parallel with cost-effective 'assistant' models. This architecture avoids benchmark overfitting and enhances task generality through dynamic in-session routing and deeply tuned interaction patterns, showing the most significant efficiency improvement in implementation-oriented sessions. Users can try the preview version via app.devin.ai/signup.

Jun 18Thu
Jun 17Wed
Jun 11Thu
  1. Factory News

    Droid has launched an automated security review feature.

    Droid runs STRIDE-based security reviews on every non-draft PR, attaching severity level, CWE reference number, explanation, and repair suggestions to discovered vulnerabilities, and publishing them as inline comments directly on the code diff. This feature has been running in production code repositories and has discovered vulnerabilities such as CVE-2026-42876. Droid filters false positives by building lightweight threat models, scanning for vulnerabilities, and verifying candidate discoveries, generating only one summary comment per PR.

Jun 4Thu
Jun 2Tue
May 30Sat
  1. Prime Intellect Blog75

    Prime Intellect has released Hosted Evaluations, simplifying benchmark testing for large language models.

    Prime Intellect has released Hosted Evaluations, providing scalable infrastructure for users to test models in self-evaluation environments. The service supports running evaluations on the hundreds of community environments already available in Environments Hub, with users able to start them via the platform, CLI, or .toml files. It supports benchmark tests like GPQA, SWE-bench, and results can be published to corresponding leaderboards with transparent display. This aims to address the infrastructure needs of modern evaluations and improve testing efficiency and reproducibility.

May 29Fri
  1. Cognition Blog

    Cognition Blog: How to Scale Validate AI Agent Development

    The Cognition team is promoting asynchronous software engineering, with more Devin triggered by events and automation, requiring end-to-end cloud validation to ensure results are reliable. Devin Review can automatically fix code review issues, but needs further testing and validation. Devin runs in cloud virtual machines, controlled with a mouse and keyboard, able to test its own work, and can run 10-20 instances in parallel, saving local validation time. It improves reliability through test plans, deterministic scripts, and skill libraries.

May 27Wed
  1. Dify Blog75

    Dify Platform: A practical guide for marketers to build reliable AI workflows

    Dify is an LLM application development platform that enables marketers to build structured, repeatable workflows containing LLMs, vector databases, external APIs, and logical steps through visual drag-and-drop. It supports multi-model generation (such as GPT-4, Claude, Gemini) for parallel content creation, automatic scoring and lead routing, knowledge base for marketing with Q&A, differing from tools like ChatGPT and Claude that only support single-model conversations.

May 22Fri