Skip to content
Live
Nov 5Thu
  1. MarkTechPost

    Ricursive AI has released Ripple-65B Preview: a 65B dense open-source model that scored 80.5 on Terminal-Bench 2.1.

    Ricursive AI has released Ripple-65B Preview, a 65B dense open-source model, scoring 80.5 on Terminal-Bench 2.1, becoming the highest-scoring open-source model in the United States. Its parameter size is 65B (active parameters), pre-training used 12T tokens, with a maximum context length of 1M, and is released under the Apache 2.0 license.

  2. MarkTechPost

    webAI has released TwIL-8B, an 8.8B inference model that scored 98.2 on MATH-500.

    webAI has released TwIL-8B, an 8.79B dense inference model fine-tuned based on IBM Granite 4.2 8B, achieving 98.2 on MATH-500 and 81.6 on LiveCodeBench†, using 38% fewer tokens than Qwen3.5-9B.

  3. Latent Space60

    Latent Space reports on the latest trends in the AI field and in-depth interviews

    Latent Space reports on the latest trends in the AI field, including cutting-edge large model direct weight editing technology (such as GPT-6 Astra editing Qwen3.5-0.8B weights to increase MATH-500 from 7.9% to 48.1%), as well as the latest evaluation results of Tencent Hy4 achieving 75.2 points on APEX-Agents and Kimi K3.1 Pro ranking 14th in Agent Arena.

  4. Hugging Face Blog65

    Dharma-AI releases Dharma Field Extractor: 2B parameter model extracts any document into JSON fields

    Dharma-AI releases Dharma Field Extractor, a 2B parameter model, input document image and optional schema, output typed structured JSON, supports open extraction and schema-directed extraction, missing fields return null.

    Why it matters: The original text provides a comparison of quality and cost on self-built benchmarks, allowing readers to judge the feasibility of the small model specialized route in field extraction tasks.

  5. ITHome · AI65

    Huawei Xiaoyi Work first launched the openPangu-2.1-Pro model, featuring 'HarmonyOS Task Enhancement'

    Huawei Xiaoyi Work first launched the openPangu-2.1-Pro model, featuring 'HarmonyOS Task Enhancement', specific capabilities and parameter specifications of the model have not been disclosed. Xiaoyi Work is currently in Beta, requires payment to use, and supports market research, document processing, PPT creation, data analysis, content creation, and code development.

Nov 4Wed
  1. ITHome · AI63

    Anthropic's new flagship Fable 5.5 tested to generate 66 seconds of animation purely from code

    Anthropic's new flagship Claude Fable 5.5 was tested by developers to generate 66 seconds of animation purely from code in an unofficial release, continuously writing and running code for about 2 hours 40 minutes to complete the visuals, music, and sound effects. The test shows that Fable 5.5 can complete the coding and running of complex dynamic scenes in about an hour, surpassing some existing Claude models. Anthropic has not confirmed the release time, performance metrics, and scope of the 5.5 series, and the above test results await official confirmation.

  2. ITHome · AI62

    MagicCore Technology has released the 4D world model MoWorld 2.0, based on Huawei Ascend native.

    MagicCore Technology has released the MoWorld 2.0 model, integrating physical elements such as gravity and elasticity into spatial modeling, outputting 4D Gaussian assets that can be rendered in real-time and called. Deployed based on Ascend computing power, the inference cost has been reduced to 30% of the same-scale GPU solution, and the video inference frame rate has been increased to approximately 70 FPS.

  3. ITHome · AI62

    XPeng, in collaboration with Peking University, Hong Kong University, and others, has released the GroundingPI pre-trained model, with its perception module scoring over GPT-6 Astra.

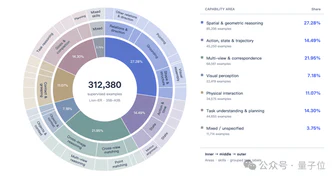
    The GroundingPI model jointly released by Xpeng, Peking University, Hong Kong University, etc., scored 73.68 in a comprehensive evaluation of 34 perception benchmarks, surpassing GPT-6 Astra's 71.54. The model, with a parameter size of about 4 billion, adopts a 'perception-first' technical approach, demonstrating higher data processing efficiency and stronger scene generalization capabilities in robotic simulation tasks, significantly reducing teaching costs while maintaining stability.

  4. MarkTechPost

    Tencent's WeVisOne-VL unifies detection, OCR, segmentation, and Matting.

    Tencent WeChat Vision team releases open-source visual language model WeVisOne-VL, including 2B and 4B parameter versions, supporting detection, OCR, segmentation, and Matting, using a 9.6M parameter decoder to output pixel results, surpassing same-scale baselines in over 30 benchmark tests, with the 4B version achieving a 71.3 F1 score on Dense200 dense detection.

  5. MarkTechPost55

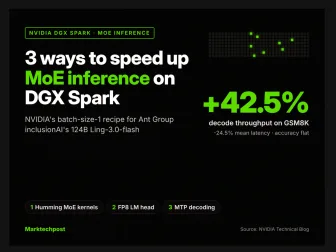
    NVIDIA demonstrates 3 methods to accelerate MoE inference on DGX Spark, increasing Ling-3.0-flash throughput by 42.5%

    NVIDIA boosts the inference throughput of the 124B parameter Ling-3.0-flash model on DGX Spark by 42.5% and speed by 3.5x with a new MoE backend, FP8 output layer, and built-in speculative decoding, without compromising accuracy. This optimization is suitable for single-user desktop systems, improving throughput from 37.81 tokens/s to 53.89 tokens/s and reducing latency by 24.5% on 1,319 GSM8K problem tests.

Nov 3Tue
  1. 36Kr · AI

    Baidu Apollo World World Model Unveiled

    Baidu Apollo first reveals the intelligent agent-driven, multimodal world model Apollo World for physical AI, proposing a '2+3' judgment standard for world models. In the virtual city constructed by Apollo World, traffic participants such as vehicles and pedestrians have decision-making and interaction capabilities.

  2. ITHome · AI60

    Baidu Apollo World's world model unveiled: Using AI to teach AI to drive

    Baidu Apollo first reveals physical AI intelligent body-driven full-modal world model Apollo World, can generate realistic videos following real-world laws and support autonomous vehicles to complete complete travel tasks from start to finish. The model proposes a '2+3' judgment standard for world models, requiring causality, interactivity, physical accuracy, persistence, and real-time performance, supporting AI intelligent body decision-making and interaction in virtual cities, already used in Luobo Fast global testing and verification.

  3. ITHome · AI

    Xiaomi-Robotics-1 Embodied Base Model Starts 'Trial Operation' at Xiaomi Youth Apartments

    The Xiaomi-Robotics-1 Embodied Base Model has started 'trial operation' at Xiaomi Youth Apartments, capable of autonomously planning tasks such as desk organization and trash cleaning. The model is pre-trained on 100,000 hours of UMI data and post-trained on 10,000 hours of cross-ontology data, supporting mobile operation and dual-arm robots, adapted for complex tasks. The Agent closed-loop system built by Xiaomi Technology achieves long-term validation with coverage of 3 rooms and over 50 tasks within 30 minutes.

  4. Hugging Face Blog

    Transformers Model Integration Contracts Released: Hugging Face Launches Model Integration Contracts Standard

    Transformers supports over 750 model types, its test suite includes 88,000+ CPU tests and 200,000+ GPU tests. Hugging Face releases Model Integration Contracts (MIC) standard, including compressed models (such as a 66 MB weight UMT5 fix), runnable examples (such as SmolLM text generation), and human review baselines.

  5. Latent Space

    Claude Code can read and write neural network weights: 'Weight space programming' bypasses Autoresearch

    Claude Code can directly read and edit the weights of other models without human intervention or PyTorch/Jax code, achieving weight reading, single-time bug fixes, performance improvements, or writing network weights from scratch. This technology bypasses the traditional process of Autoresearch by running experiments in a cluster to train models, demonstrating the potential of LLMs in weight space programming, currently mainly applicable to simple games and RL policies.

Nov 2Mon
  1. QbitAI65

    SenseNova 6.8 Flash Release: Limited-time Free to Handle Gemini 4 Carbon's Challenging Webpages and Dynamic PPTs

    SenseTime has released the multimodal intelligent agent model SenseNova 6.8 Flash, which is available for a limited time free and achieves first or second place in office automation, multi-step collaboration, and data analysis benchmarks, while tying with GPT 6 Luna for first place in long-term memory evaluations. This model can complete dynamic webpages, dynamic posters, SVG animations, and dynamic PPT designs, and has proactive interaction capabilities, able to remember and remind to update old materials.

  2. Moonshot AI · Hugging Face new models

    Kimi K3.1 Pro Released: Open-Weight Multimodal AI Model

    Kimi K3.1 Pro is an open-source multimodal AI model by Moonshot AI, with 2.8T parameters, 104B activation parameters, and a context window of 1M tokens, demonstrating excellent performance in areas such as coding, 3D creation, and financial research. Compared to Kimi K3, it adopts Gated DSA layers to improve long text processing efficiency and has outperformed competitors like Claude Fable 5.1 and GPT-6 Astra in benchmarks such as Terminal-Bench 4.0.

  3. Sakana AI38

    Sakana AI held a seminar: Jürgen Schmidhuber talks about the past and future of AI, Japan will challenge language models, world models, and physical AI

    Jürgen Schmidhuber, professor at the Sakana AI Symposium, presented a speech reviewing the many ideas that contributed to modern deep learning and generative AI from the 1980s to the 1990s, and introduced the LSTM paper proposed in 1990. Sakana AI announced the development of a pre-trained model, planning to release a small language model named 'Sawara Small' in spring 2027.

  4. ITHome · AI72

    Meituan LongCat releases LongCat-2.5 native multimodal model, 1.6T parameters targeted at long-range intelligent agent tasks

    Meituan Longma has released the native multimodal model LongCat-2.5 for long-range intelligent agent tasks, with a total parameter count of 1.6 trillion, activating about 48 billion parameters per token, enhancing native visual understanding and intelligent agent programming capabilities based on LongCat-2.0.

    Same story — showing the featured version《》