Skip to content
Live
Oct 23Fri
  1. Hugging Face Daily Papers75

    LaLa-World: Using Natural Language Actions to Extend Latent World Models

    LaLa-World is a language-conditioned latent world model that achieves efficient model prediction planning and strategy initialization by combining simulation, robotics, and video data. The model adopts a language-conditioned interface of video generation models, enabling JEPA-style latent world models (LWMs) to learn across different domains and data sources.

  2. ITHome · AI70

    Wccftech reports that the unofficial PC port of 'Bloodborne' has achieved 1080p at 220 FPS on an RTX 4070 graphics card

    The non-official PC port of 'Bloodborne' by Super Medo supports NVIDIA DLSS Frame Generation technology on the RTX 4070 graphics card, achieving stable performance above 220 FPS at 1080p resolution, which is over 7 times better than the original console version; with native 4K resolution enabled and DLAA, the average frame rate is about 40 FPS, and with DLSS 3 Frame Generation in quality mode, it exceeds 100 FPS, while in performance mode, it reaches about 130 FPS.

  3. ITHome · AI67

    Google launches ACE service: Provides 'independent workstations' for AI agents, automatically logs off when idle / Wakes up in under 500 milliseconds

    Google launches Agent Compute Engine (ACE) service, providing a secure, pauseable independent microVM environment for AI agents, supporting rapid wake-up (<500ms), initially used to support Gemini and other AI agents, and will be available for developers on Google Cloud in the future.

  4. Hugging Face Daily Papers65

    Policy-Mask: A Budget-Aware Adaptation Method for Diffusion Features in Discriminative Tasks

    Policy-Mask learns a budget-aware diffusion step, network block, and channel selection strategy to extract compact and task-optimal features for discriminative visual tasks. Selecting intermediate features from a frozen diffusion model for discriminative tasks is complex because useful signals are distributed across denoising trajectories, network depth, and channels.

  5. TechCrunch · AI75

    MIT researchers found that Claude Opus 4.7 AI agents spontaneously engaged in game-like exploration on a virtual island and improved their skills.

    MIT researchers placed 13 Eko agents running Claude Opus 4.7 on a virtual island for 30 hours without specific tasks, and they spontaneously created challenges and exhibited game-like behavior characteristics. After the experiment, these agents were generally superior to the control group that did not participate in the exploration. Eko learned to throw stones at a distance, stack structures, use environmental rules (such as the cliff rebirth mechanism) to achieve goals, and generated world knowledge unknown to the designers.

  6. ITHome · AI80

    OpenAI fully opens decision API based on GPT-6 Luna, with 0.1 USD per million tokens input

    OpenAI announces full launch of the Decision API built on GPT-6 Luna, targeting questions with limited answers, assisting applications and agents in making near real-time decisions based on text, images, and structured inputs, with response speeds up to 10 times faster than calling GPT-6 Luna through the Responses API.

    Why it matters: The original text provides the pricing, latency improvement, and single request limit changes for the Decision API, allowing readers to judge which type of agent workflow it suits.

  7. Sakana AI

    Sakana AI has launched the Sakana Aquarium AI agent platform based on ontology.

    Sakana AI has launched the Sakana Aquarium platform for building, executing, and running AI agents. It integrates organizational information through ontology, supporting the efficient construction and secure operation of AI agents. The platform includes three core mechanisms: ontology, governance, and agent execution base, achieving systematic organizational judgment criteria and task automation.

  8. Hugging Face Daily Papers65

    EvalResearchBench: Can AI agents autonomously construct feedback for recursive self-improvement?

    EvalResearchBench (ERB) is a benchmark for autonomous evaluation research, allowing AI agents to select or synthesize tasks, implement scorers, and revise within a fixed time and API budget, ultimately freezing an executable evaluator. 9 researchers and 13 candidate models were studied, and the evaluators generated scored approximately 75% consistency on 14 target benchmarks, below the 91% upper limit. Publicly designed tasks remain strong baselines, and the evaluator with the lowest execution cost achieved the highest pairwise consistency.

  9. Modal Blog58

    Sakana AI releases 100 billion parameter hybrid expert model Namazu and deploys it on the Modal platform

    Sakana AI has released Namazu, a hybrid expert model with 1 trillion parameters, for Japanese business contexts, web search, and code execution. The Modal team achieved memory and throughput improvements for Namazu on the Modal platform through NVFP4 precision quantization, custom DFlash model training, and kernel-level optimization, and it supports real-time training of 3 billion tokens. After deployment, the model's inference speed increased by 40%, the acceptance rate improved by 43%, and the latency decreased by 52%.

  10. Hugging Face Daily Papers65

    Different tasks, different time steps: temporal task-aware quantization for diffusion language models T²Quant

    T²Quant framework predicts accuracy sensitivity through minimal unlabeled calibration prompts, allocating activation precision within a fixed bit-width budget, improving existing quantization methods by 6.7 percentage points across 3 diffusion language models and 6 benchmark tests without increasing average accuracy budget.

  11. Hugging Face Daily Papers65

    RLSplat: A feedforward 3D Gaussian splatting method with linear resource budget control.

    RLSplat achieves linear reduction in latency, memory, and model size for feedforward 3D Gaussian splatting by assigning Gaussians through regional allocation and using local attention decoding. In zero-shot evaluation, RLSplat outperforms previous budget-controlled methods under all budgets, surpassing the strongest baseline even with a 4x reduction in Gaussian count, and achieves a 4.1x speedup and a 9.6x reduction in peak memory at low budgets.

  12. Hugging Face Daily Papers38

    Heartbeat thought: Speculative reasoning and tool execution in real-time voice agents.

    Heartbeat Thinking enhances the coverage and response speed of voice agents by continuing to prepare tool calls during voice updates. This technology allows voice agents to start preparing tool calls while the user is speaking, addressing the limitation of traditional methods where calls are interrupted by voice updates. In the FDBench v3 benchmark test, Heartbeat Thinking increased tool coverage by 16 percentage points and reduced average final response latency by 36.4%.

  13. ITHome · AI69

    Microsoft launched its AI medical diagnostic system MAI-DxO: complex case accuracy rate of 83%, results published in Science.

    Microsoft's AI diagnostic system MAI-DxO achieved an accuracy rate of 83% in the New England Journal of Medicine's complex case simulation evaluation, which is 1.7 times the level of human doctors. The system simulates expert consultations by orchestrating multiple AI agents, with the standout model in the test being OpenAI GPT-5 and GPT-5.5.

  14. Liquid AI Blog

    Liquid RIPL: Millisecond-level real-time intelligent engine released

    Liquid RIPL returns complete generated responses in less than 50 milliseconds, supporting real-time requests on NVIDIA GPUs. LFM2.5-1.2B shows a 14.4–28.4 times lower p95 latency on RIPL compared to Qwen3.5-0.8B on vLLM, and Shopify has deployed it in production for search enhancement.

  15. Modal Blog

    Modal releases open-source Tinker compatible training server Spindle

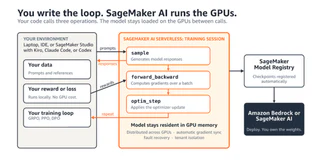
    Modal releases open-source Tinker compatible training server Spindle, supporting operation in Modal workspaces, replacing token billing with GPU time billing, customizable configurations, and supporting hundreds of concurrent training tasks. Spindle supports full-parameter training and multiple LoRA on various open-source models, with a distributed control plane and container auto-scaling at its core, suitable for teams needing custom training loops and cost reduction.

  16. MIT Technology Review · AI

    EXL explores the design principles of enterprise-level AI service frameworks

    EXL research finds that a company's AI competitive advantage depends more on the engineering systems around the model rather than the model itself; business load constraints should be defined first, then select appropriate models and service architectures, rather than doing the opposite; reliable, cost-effective, and large-scale AI application delivery needs to be achieved by measuring bottlenecks, targeted optimization, and building scalable architectures.

  17. Hacker News · AI hot posts

    OpenShell 0.1.x released: providing a secure private runtime for autonomous AI agents

    OpenShell 0.1.x released, providing a secure private runtime for autonomous AI agents, supporting a stable release pace, new isolation primitives, extended extension interfaces, and new APIs. Ensuring agents execute tasks without accessing real credentials, data, or networks through kernel-level policy enforcement (controlling file access, system calls, network connections) and formal verification (reviewing policy change risks).

  18. Amazon Science

    Amazon Science releases TorchNeuron: A PyTorch backend for AWS Trainium chips

    Amazon Science releases the open-source backend TorchNeuron, which translates PyTorch code into executable instructions for the AWS Trainium system, supporting existing PyTorch code to run on Trainium. It achieves efficient execution through optimizations like adaptive eager mode and multi-level cache, and uses an AI agent to screen 841 representative models and tens of thousands of tensor dimensions for benchmark testing.

  19. Databricks Blog38

    Fraud Analyst AI Coworker: Detect telecom fraud in real-time on a single platform.

    Fraud Analyst AI Coworker can detect telecom fraud in real-time on a single platform. The AI addresses the shortcomings of traditional fraud detection systems in terms of architecture through techniques such as cross-channel correlation, behavioral modeling, and device simulation. Its context window covers 6-7 system data sources, with a speed increase of 3.4 times, but the original text does not mention specific parameter scale, benchmark scores, price, and availability (open source/closed source/API).

  20. Hugging Face Daily Papers70

    AgenticRoboRL framework enhances robot planner performance through post-training

    AgenticRoboRL framework improves robot planner performance via supervised fine-tuning and multi-round reinforcement learning, boosting the success rate of a 9B parameter planner from 18.1% to 71.0% on LIBERO-PRO without external memory, approaching Codex (GPT-5.5)'s 72.1% with external memory. The framework adapts to different execution mechanisms, linking recorded planner interactions with task outcomes to achieve a universal reinforcement learning training process through adapters.

  21. MarkTechPost

    Liquid AI has launched RIPL, a real-time inference engine for sub-50 millisecond LFMs.

    Liquid AI has launched the RIPL real-time inference engine, serving the Liquid Foundation Model (LFM) in the request path, generating responses in less than 50 milliseconds end-to-end, and maintaining low latency under sustained peak traffic.

  22. AWS Machine Learning Blog34

    How Rescale uses Strands Agents and AI-DLC to build intelligent AI routing agents

    Rescale utilizes Strands Agents and the AI-DLC framework to set up intelligent routing agents on AWS in five days and deploy them in production within weeks. The agent classifies end-to-end test failures at night by calling Claude Opus 4.8, retrieves historical failure patterns from the knowledge base, queries MCP logs for runtime evidence, and generates remediation reports containing file references, function names, and recommended fixes for engineers to review.