Skip to content
Live

Multimodal · Page 2

Oct 29Thu21–31
  1. QbitAI72

    Genspark releases Media Studio video Agent workbench

    Genspark releases video Agent workbench Media Studio, integrating over 70 model versions from more than 20 manufacturers, where large language models act as directors responsible for writing scripts and scheduling video, image, and audio models.
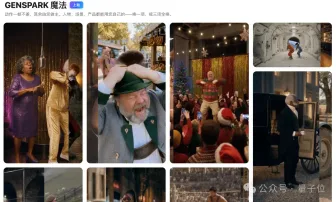
    Why it matters: The author conducted a complete test of the entire process from short drama to knowledge explanation video, allowing readers to judge the completeness and shortcomings of multi-model arrangement in real-world creation based on this.


Oct 28Wed
  1. Hugging Face Blog76

    Liquid AI releases LFM3 series: Same 2B backbone derived text, visual, audio, multimodal and decision models

    Liquid AI releases the new generation Liquid Foundation Models, LFM3, deriving six 2B-level models from the shared backbone LFM3-1.7B-Base, covering text, vision, audio, multimodal, and decision, all open weights on Hugging Face.

    Why it matters: Liquid AI derives six modality models from the same 2B-level backbone and provides single-card fine-tuning and edge deployment paths, which can be used to judge the specialization route for small models.

  2. Google DeepMind84

    Google DeepMind releases world model Genie 4

    Google DeepMind releases world model Genie 4, which can generate interactive simulated worlds with native audio in real-time, and change weather, camera angles, and scene elements in real-time with text prompts. Genie 4 natively generates environmental sounds and voice conversations for the first time, with characters able to converse in real-time and respond to scene events; Gemini 3.8 Flash acts as a guiding intelligence in the loop, breaking down goals into steps and verifying frame by frame.

    Why it matters: The official disclosure of three capabilities—native audio, real-time text control, and Gemini-guided reasoning—can be used to judge the position of the world model in robotics and content preview.

Oct 27Tue
  1. MarkTechPost71

    Baidu open-sources Unlimited OCR 2, supporting the parsing of hundreds of pages of documents.

    Baidu open-sources Unlimited OCR 2, a 3.34B parameter OCR visual language model that can parse hundreds of pages of books, financial reports, and reports in a single request. The weights are released under the MIT license, and the code is on GitHub.

    Why it matters: The original text provides a comparison of SR-SWA's sparse attention mechanism with the hundred-page document benchmark, showing how the contextual cost of long document OCR can be flattened.

  2. ITHome · AI86

    OpenAI releases low-cost new model GPT-6.1 Terra, with a cost per task about one-ninth of Claude Opus 5.5

    OpenAI releases new model GPT-6.1 Terra, featuring lower costs for complex tasks requiring visual reasoning and desktop software operation, opening to Plus, Pro, Enterprise, and Edu users on October 27, available in ChatGPT Work and Codex, with the API model identifier as gpt-6.1-terra.

    Why it matters: The original text provides multiple benchmarks and cost per task comparisons, allowing readers to judge the trade-offs of low-cost models in desktop automation.

Oct 25Sun
  1. The Decoder78

    Nvidia's open-source robot video annotation engine Flora claims to be 125 times cheaper than GPT-6 Astra.

    Nvidia's open-source data engine Flora, used for robot video annotation, claims to label one hour of video for about 0.72 USD, while GPT-6 Astra is about 88.50 USD. Flora consists of three fine-tuned Qwen3.5 models, each responsible for action segmentation, context-aware description, and reward scoring, covering three types of labels: action description, step-by-step scoring, and task success or failure judgment.

    Why it matters: The original text provides Flora's three types of annotation capabilities, cost estimates, and item-by-item comparison with GPT-6 Astra, allowing readers to judge the boundary of open-source alternatives for robot video annotation.

Oct 24Sat
  1. Tencent Hunyuan · Hugging Face new models71

    Tencent Mixuan open-sources Hy-Nomas Interactive World Generation Model Diffusers version

    Tencent's Huyuan has released Hy-Nomas' BF16 Diffusers format distilled weights on Hugging Face. This video world generation model supports multi-round free interaction through text instructions and camera control, generating the same world segment by segment.

    Why it matters: Officially releases distilled BF16 Diffusers weights and supporting benchmarks, allowing readers to judge the practical usage and threshold of multi-round interactive world generation.

Oct 22Thu
  1. Tencent Hunyuan · Hugging Face new models72

    Tencent Mixuan open-sourced the real-time simultaneous translation model Hy-SimulMT-30B-A3B

    Tencent Mixuan has released and open-sourced the real-time simultaneous translation model Hy-SimulMT-30B-A3B, supporting bidirectional Chinese-English voice-to-voice translation, capable of continuously outputting translated text and speech during speech, and supporting real-time voice cloning.

    Why it matters: The official provides a comparison of latency and quality for real-time simultaneous translation, and opens up multiple quantitative versions and inference deployment scripts, which can be used to evaluate the deployment cost.

Oct 14Wed
  1. Google AI Blog90

    Google has released the Gemini 4 Argon cutting-edge model.

    Google has released Gemini 4 Argon, opening it up to developers, businesses, and researchers, with API pricing at $2 per million input tokens and $10 per million output tokens, offering a 95% discount on cached input tokens.

    Why it matters: Official pricing, baseline rankings, and multiple internal implementation cases are provided, allowing judgment on its position in coding and research workflows.

Aug 12Wed
  1. Liquid AI Blog71

    Liquid AI releases edge-side visual language model LFM2.5-VL-3B

    Liquid AI releases LFM2.5-VL-3B, an upgraded 3.1B edge-side visual language model based on its predecessor LFM2-VL-3B, now available on Hugging Face and Playground

    Why it matters: The original text provides 28 benchmark items, edge-side, and GPU throughput data, which can be used to compare with similar-sized competitors to determine the actual position of this 3B visual model.