Skip to content
Live
Nov 3Tue
  1. Hugging Face Daily Papers58

    CoworkOS: An Intelligent Agent Collaboration Framework for Real-world Automation

    CoworkOS enables human-machine collaboration and continuously improves model performance by separating strategies from execution, driving human-machine collaboration towards real-world automation. The framework performs excellently in 12 benchmarks and 6 categories of real-world applications, using GLM-5.3 as the core, and performs RSI-driven automatic post-training on Qwen3.6-35B-A3B, increasing the average score on 8 benchmarks from 33.19 to 42.95.

  2. Ai2 Blog

    StateBench: Benchmark for testing large language models to track changes in long document states

    StateBench is a benchmark for testing large language models' ability to track entity state changes in long documents, including four difficulty levels: R-trivial, non-periodic, solvable, and general finite. Research finds that recurrent and hybrid models generalize far better than Transformers when directly trained on these tasks, while cutting-edge models like Gemini 3.8 Flash, Claude Opus 5.5, and GPT-6 Sol still struggle with more complex state tracking issues when input lengths vary.

  3. Hugging Face Blog

    Transformers Model Integration Contracts Released: Hugging Face Launches Model Integration Contracts Standard

    Transformers supports over 750 model types, its test suite includes 88,000+ CPU tests and 200,000+ GPU tests. Hugging Face releases Model Integration Contracts (MIC) standard, including compressed models (such as a 66 MB weight UMT5 fix), runnable examples (such as SmolLM text generation), and human review baselines.

  4. Anthropic Research62

    Anthropic has released the verifiable reasoning system FlashProve, generating proofs at approximately 110 tokens/second on a single H100.

    Anthropic announced the verifiable reasoning prototype FlashProve, using zkSNARK to prove that the response indeed comes from the committed model weights. For the 400B parameter Llama 4 Maverick (4-bit quantization), a single H100 generates proofs at approximately 110 tokens/second, with proofs for each 1,024 token request being about 19 MB, and verification on a 24-core CPU taking about 17 seconds.

    Why it matters: Anthropic has released the measured data and Lean formal proof of the verifiable reasoning prototype FlashProve, allowing for a cross-comparison with existing zkML solutions.

  5. Latent Space

    Claude Code can read and write neural network weights: 'Weight space programming' bypasses Autoresearch

    Claude Code can directly read and edit the weights of other models without human intervention or PyTorch/Jax code, achieving weight reading, single-time bug fixes, performance improvements, or writing network weights from scratch. This technology bypasses the traditional process of Autoresearch by running experiments in a cluster to train models, demonstrating the potential of LLMs in weight space programming, currently mainly applicable to simple games and RL policies.

  6. Hugging Face Daily Papers47

    uni-robot-agent: Open-source robot use agent unified framework achieves zero-shot operation breakthrough

    The uni-robot-agent framework enables open-source weight robots to surpass proprietary models using agents in zero-shot operation, with its onboard Qwen3.8-Flash-Next scoring 31.39 in the RoboDojo evaluation, exceeding GPT-6 Astra-RoboProbe's 28.97 score and numerous VLA/WAM baselines, and performing excellently in 19 real tasks. Analysis indicates that effective robot use requires combining four general capabilities, suggesting future training should synergistically develop these capabilities.

  7. QbitAI

    Peking University, in collaboration with IBM, defines a new paradigm for modern analog computing.

    A review paper co-directed by Sun Zhong from Peking University and involving the IBM Research Lab in Zurich defines modern analog computing, distinguishing it from traditional analog computing, focusing on matrix computing required for AI and 6G communications, and achieving high precision and scalability based on resistive random-access memory. Annuan Zhixin's Analog Matrix Computing (AMC) circuit, through a resistive random-access memory array and a negative feedback closed loop, completes matrix inversion in less than 100 nanoseconds per operation, with accuracy reaching 10^-7, 100 times more energy-efficient than digital chips, and 10 times lower in cost. It is planned for use in embodied intelligence and 6G communications, and supports second-order optimization training for large models.

  8. Hugging Face Daily Papers

    How Agent Harness Achieves Video Generation and Agent Interaction

    Agent Harness Integrates Video Generation and World Model, Supporting Agents in Multi-Camera Video Production for Planning, Tool Use, and Recursive Self-Improvement. The Framework Coordinates Script, Shooting Planning, Asset Management, Production, and Editing, and Analyzes Its Evaluation Challenges; Meanwhile, It Studies Agent-World Model Interaction in Observation, Control, Execution, and State Maintenance, as Well as How They Mutually Evaluate and Improve.

  9. QbitAI80

    MIT experiment: GPT-6 Astra directly modifies Qwen3.5 weights, mathematical ability improves by about 6 times

    MIT's experiment allowed GPT-6 Astra to directly read and edit the weights of Qwen3.5-0.8B, changing only 0.016% of the parameters, without training and gradient descent, MATH-500 score improved from 7.9% to 48.1%, and instruction execution ability also increased 3 times.

    Why it matters: MIT experiments show that cutting-edge models can directly read and write the weights of smaller models, providing a reproducible path for performance repair of gradient-free training.

  10. MarkTechPost

    Zyphra AI introduces Zyphra Hierarchical Attention (ZHA): The path to true sub-quadratic attention

    Zyphra AI has released Zyphra Hierarchical Attention (ZHA), a sparse attention method based on a tree indexer, designed to address the known issue in sparse attention where the indexer still needs to scan the entire context. ZHA can be distilled into a frozen pre-trained model of about 4B tokens, achieving performance close to dense attention in inference, smart encoding, and 256K retrieval benchmarks on Qwen3.6-35B-A3B.

  11. ITHome · AI

    OpenAI released the LifeVal benchmark: From selecting a kindergarten to filing taxes, testing AI's 'human touch' skills.

    OpenAI released the LifeVal benchmark to measure whether AI models can help ordinary people complete daily tasks, covering scenarios such as care, health, education, household administration, personal finance, shopping, and accessing government services. Typical tasks include selecting a kindergarten for a child, creating a diabetes diet plan, and organizing government forms, requiring AI to advance the task to an executable state.

  12. ITHome · AI75

    MIT CSAIL proposes weight space programming: GPT-6 Astra modifies Qwen3.5-0.8B's weights by about 0.016%, boosting MATH-500 score to 6 times

    MIT CSAIL researchers propose 'weight space programming', allowing GPT-6 Astra to directly read and modify the neural network weights of Qwen3.5-0.8B, adjusting only about 0.016% (131072 parameters) to increase MATH-500 score from 7.9% to 48.1%, GSM8K from 13.8% to 67.1%, and IFEval from 21.0% to 62.3%.

  13. Hugging Face Daily Papers65

    CEPO: A general prompt optimization framework for multi-agent systems

    CEPO enhances prompt optimization for multi-agent systems by separating shared coordination from agent-specific execution, continuously improving the performance of four existing prompt optimization methods across 11 cross-domain benchmark tests. The framework uses shared coordinator prompts and agent-specific execution prompts, guiding them to update based on their respective roles, allowing shared coordination rules to be consistently optimized across all agents while maintaining independent adjustment of execution instructions. Experiments show that CEPO improves optimization budget efficiency and scales performance as the number of agents increases.

  14. Hacker News · 300+83

    Astra can read and write neural network weights and improve Qwen3.5-0.8B

    The research team proposed Weight-Space Programming, discovering that GPT-6 Astra can directly read and write neural network weights: with only 17,253 weights, it can determine which game the network is trained on, and from scratch, write a small game network that defeats PPO trained for 100 million steps without gradients or training.

  15. PyTorch Blog34

    Ray announces the Special Interest Group (SIG) for Accelerators

    Ray announces the Special Interest Group (SIG) for Accelerators, aiming to unite hardware vendors, Ray contributors, and application developers to create a neutral accelerator support roadmap. Initial focus will be on developing test infrastructure, hardware awareness capabilities, and network transmission, prioritizing shared hardware access, reproducible development and testing environments, and broader CI coverage.

  16. OpenAI News42

    OpenAI releases LifeVal benchmark: Measuring AI-assisted daily task capabilities

    OpenAI released the LifeVal benchmark, used to evaluate the effectiveness of AI-assisted completion of daily tasks (such as finding childcare, financial management, handling government documents).

  17. AWS Machine Learning Blog43

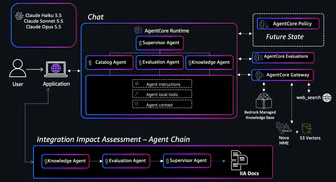
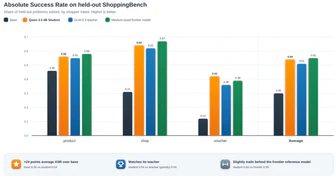
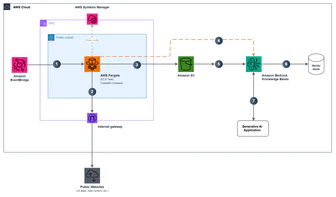
    Use knowledge distillation to build efficient intelligent agents on Amazon SageMaker AI

    Use knowledge distillation to fine-tune the shopping assistant on Amazon SageMaker AI, by transferring the behavior of cutting-edge models to small models through sequence-level knowledge distillation (SeqKD), generating reasoning trajectories for task-solving and using them for supervised fine-tuning to achieve efficient low-cost inference. SeqKD only requires the text output of the teacher model, without weights or logits, and is suitable for scenarios where access to the teacher model's internal information is not available, such as API models, and can evaluate the performance of student models through benchmark tests.

  18. Hugging Face Daily Papers65

    WeFair: Fidelity-Aware Alignment Technology Based on Human Feedback, Used for Personalized Query Rewriting in Short Video Search

    WeFair improves personalized query rewriting through a human feedback phase (demonstration, preference, and validation) based on fidelity perception, reducing intent drift and enhancing search effectiveness on short video platforms. This technology addresses the need for compact query rewriters in short video search, recovering user personalized intent from ambiguous queries under strict latency constraints. WeFair-2B outperforms strong rewriting baselines in overall accuracy and intent preservation in offline experiments, while online A/B testing shows a relative increase of 2.593% in effective video play rate and a relative decrease of 2.350% in query rewriting rate.

  19. Hugging Face Daily Papers38

    REA: A runtime for asynchronous cerebellar-brain control for embodied intelligent agents

    REA unifies deliberative and reactive strategies in a single runtime, achieving high success rates and reducing control overhead through asynchronous coordination in both simulated and real robotic tasks. On 3,000 test segments across 60 LIBERO-Pro tasks, REA achieved a 95.9% success rate, outperforming its best single-agent baseline from its strategy library (94.7%), while reducing control steps by 25% and control time by 17%.

  20. Hugging Face Daily Papers34

    OSWAM: An efficient single-step action generation world action model

    OSWAM achieves real-time high-quality action generation in autonomous driving and embodied control by using structured imagination tokens to initialize the diffusion process and distilling future condition privileged information into a single denoising step. The model generates high-quality actions with just one diffusion step, about 3 times faster than direct strategy world action models (WAM) that require dozens of denoising steps, achieving low latency of up to 40ms on an NVIDIA RTX 5090 GPU, supporting real-time compiled inference.

  21. The Decoder73

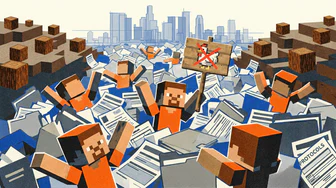
    50 AI agents spontaneously form bureaucratic collaboration in Minecraft

    The research team placed 50 GPT-6.1 Sol agents into a Minecraft survival world and ran them for three hours, only giving the instruction 'build a prosperous civilization'. The agents cut down all the trees near the spawn point in 90 seconds, exchanged about 5900 messages in total, and spontaneously elected 'Ada' as the leader in alphabetical order of the directory.

    Why it matters: The experiment placed 50 agents into Minecraft and Mindustry to observe their spontaneous organization behavior in collaboration and competition, and the test environment was open-sourced.

  22. Hugging Face Daily Papers34

    Venus-DefakerOne2: A broader visual forensics base model

    Venus-DefakerOne2 extends detection to multiple spoofing forms and media types through alternating LoRA and full-parameter fine-tuning, as well as entropy-based test adaptive, achieving SOTA performance in six benchmark tests including DeepFake faces (96.7%), AI-generated images (93.3%), and tampered documents (87.6%), significantly outperforming expert models and predecessor DefakerOne.

Nov 2Mon
  1. Import AI42

    Realtime-Bench released: Benchmark tests to evaluate the performance of LLMs on low-latency tasks

    Realtime-Bench benchmark tests evaluated the performance of LLMs on 50 real-time interactive games and web tasks, with GPT-6 Astra achieving a 36% pass rate under real-time clock conditions; this test was developed by institutions such as the University of Texas at Austin to measure the model's real-time state awareness, adaptive reasoning, and time-aware action selection capabilities.

  2. Hugging Face Daily Papers38

    LARC framework implements continuous space latent reasoning to unify multimodal models

    The LARC framework alleviates the bottleneck of applying linguistic reasoning in image generation for unified multimodal models by reasoning on continuous hidden states, improving generation quality and achieving test-time scaling without discrete token bottlenecks. The framework includes two stages: curriculum supervised fine-tuning (SFT) and information gain reinforcement learning (RL). In text-to-image generation benchmark tests, LARC improved performance by 7% over BAGEL on GenEval and demonstrated clear test-time scaling behavior.

  3. ITHome · AI22

    The list of winners for the 2026 World Internet Conference Leading Technology Award has been announced, including the 'Jiuzhang IV' photonic quantum computing prototype machine, among others.

    The 2026 World Internet Conference Leading Technology Award ceremony was held in Wuzhen, Zhejiang, with the winning list including the 'Jiuzhang IV' photonic quantum computing prototype machine from the basic research group, the AI-powered perception platform from the key technology group, and the AMD Ryzen AI Max+ processor and Microsoft Copilot Cowork productivity engine from the engineering and R&D group.

  4. Hugging Face Daily Papers65

    HiFOR: A hierarchical predictive framework for visual language action models

    HiFOR guides action generation by hierarchically predicting future states and retrieving relevant future information, enhancing robotic manipulation capabilities. The framework jointly predicts short-term state evolution, semantic milestones, and final goal states through hierarchical dependency masks (HDM), establishing cross-temporal dependency relationships; structured perception latent world modeling organizes future potential representations along temporal, perspective, and spatial dimensions, promoting fine-grained retrieval; action-guided decomposition world retrieval adaptively retrieves relevant future information based on action representations during the denoising process, providing targeted guidance for action generation.

  5. ITHome · AI65

    Researchers test AI agent clusters in Minecraft: Collaboration is prone to bureaucracy, higher win rate against GPT in battles

    Researchers used 50 GPT-6.1 Sol agents to build a civilization community in Minecraft, but failed to develop due to bureaucratic tendencies; in a wake-up war test with 10 GPT-6.1 Sol against 10 Claude Opus 5.5, GPT agents adopted a more aggressive strategy, completing problem diagnosis and sharing solutions; in seven Mindustry battles, GPT agents won six and lost one, demonstrating the advantage of swarm mode.

  6. Hugging Face Daily Papers58

    Wizard: Real-time control of any world through agent control

    Wizard decouples character animation, scene control, and game logic from visual generation, allowing intelligent agents to control joint skeletons and scene geometry through structured visual agents, achieving real-time interaction at 24 FPS, zero-shot generalization to unseen scenes, characters, and actions. The team built 50.3 hours of aligned agent-video pairs, including 750 scenes and 178 characters, supporting character adaptive masking, causal adaptation, and few-step distillation techniques.