Skip to content
Live
Oct 29Thu
  1. ITHome · AI65

    Xiaomi MiMo Desktop membership benefits upgraded: increased quota without price increase, new third-party models such as DeepSeek added

    Xiaomi has increased the membership credit for MiMo Desktop without increasing prices, taking effect in real-time for both new and existing members. New third-party models such as DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM 5.3, GLM 5.3 Flash, Kimi K3, Qwen 3.8 Flash, and Qwen 3.8 Max are now available for members to choose, with each model labeled with its consumption multiplier.
  2. QbitAI

    Diffusion Intelligence releases Clover-35B-A3B-Preview, a 350 billion parameter model that is twice as fast as Jev.

    Diffusion Intelligence releases Clover-35B-A3B-Preview model, with 350 billion parameters achieving a median execution time of 1.52 seconds in the web Agent evaluation WindTunnel, twice as fast as the Jev+Mercury 2.5 combination, with a success rate of 98.6%. The model adopts a MoE architecture, supports thinking mode, and scores 73.6 on SWE-bench Verified.

  3. Latent Space82

    Gemini 4 Carbon topped multiple lists and was the first to be opened to cybersecurity defenders.

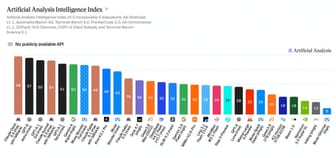
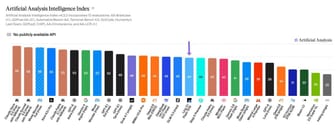
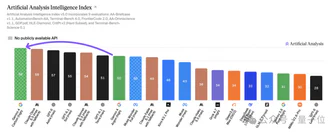
    Google DeepMind released Gemini 4 Carbon, only two weeks after Argon, claiming to achieve SOTA in cybersecurity and long-period tasks, ranking first with a score of 59 on the Artificial Analysis Intelligence Index v5.

    Why it matters: Summarizes the positions and pricing of Gemini 4 Carbon on multiple independent lists, and lists the gaps in coding, hallucination rate, etc., compared to competitors.

  4. MarkTechPost71

    NVIDIA released the open-source speech model Nemotron 3.5 Transcribe, supporting transcription of 40 languages.

    NVIDIA releases Nemotron 3.5 Transcribe, an open-weight speech large model supporting 40 languages, up to 1 hour of audio, and capable of outputting verbatim transcripts, written text, speaker annotations, and translation results.

  5. Hugging Face Daily Papers

    Falcon audio-visual target speaker extraction model released

    Falcon is a causal audio-visual target speaker extraction model that extracts the voice of the target speaker from the mouth video of the target speaker in noisy overlapping speech, combined with a single multi-scale time-frequency separator and an encoder spatial speaker contrast loss, reducing interference speaker leakage without increasing inference cost.

  6. ByteDance Seed · Hugging Face new models

    ByteDance-Seed/GenFirst releases: A generative pre-reconstruction method for stable end-to-end latent generation modeling

    ByteDance-Seed/GenFirst trains a latent VAE and combines it with a generative prior to avoid latent collapse, which usually makes end-to-end training unstable. The two-stage plan of this method is used for prior and entropy weights: the first stage lets the prior shape the latent geometry, and the second stage reduces both weights tenfold, allowing the decoder to recover details.

  7. ITHome · AI

    Tencent Mixuan Hy4, Hy4 flash AI model to be released soon, introducing visual understanding capabilities for the first time

    Tencent announces the upcoming release of the Hunyuan Hy4, which offers a comprehensive upgrade compared to the Hy4 preview, introducing visual understanding capabilities for the first time, and enhancing long-range and productivity tasks; the Hy4 flash AI model will also be launched, providing excellent cost performance, inheriting the visual and Agent capabilities of Hy4.

  8. 36Kr · AI

    Google launches the Gemini 4 Carbon cutting-edge AI model

    Google has released the new front-end AI model Gemini 4 Carbon, used for maintaining cybersecurity defenses and handling complex engineering problems. It can handle long-process AI agent tasks, generate secure code, and reduce the proportion of model inaccuracy and fabricated information.

  9. The Verge · AI

    Google releases Gemini 4 Carbon, achieving a 'major leap' in cybersecurity capabilities

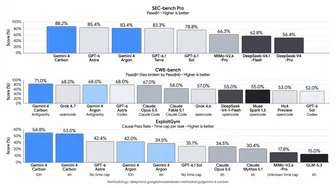
    Google has released its latest large model, Gemini 4 Carbon, achieving 'significant improvements' in coding, agent tasks, and network security. The model ranked first in the AI Analysis Index (v5.0) benchmark test and performed excellently in the SEC-bench Pro and ExploitGym evaluations.

  10. ITHome · AI85

    Google has released Gemini 4 Carbon, focusing on cybersecurity and topping the Artificial Analysis Intelligence Index.

    Google has officially released the next-generation cutting-edge large model Gemini 4 Carbon, featuring top-tier cybersecurity capabilities and long-range task processing, ranking first with a score of 59 in the Artificial Analysis Intelligence Index v5.0.

  11. The Decoder89

    Google DeepMind releases Gemini 4 Carbon, just two weeks after Argon.

    Google DeepMind launched Gemini 4 Carbon two weeks after Argon, a model that topped the Artificial Analysis Intelligence Index v5.0 with 59 points, surpassing the previous Argon with 50 points.

  12. MarkTechPost80

    Google DeepMind released Gemini 4 Carbon, emphasizing network security defense and coding.

    Google DeepMind has launched Gemini 4 Carbon, describing it as a cutting-edge model for long-period intelligent agent coding and cybersecurity defense, ranking first with 59 points on the Artificial Analysis Intelligence Index v5.0.

  13. Ars Technica · AI65

    Google has released Gemini 4 Carbon: a cutting-edge AI model that cannot be used immediately.

    Google has released Gemini 4 Carbon, reaching new thresholds in coding, agent tasks, and scientific analysis, but it has not yet been made available for use. The model significantly enhances vulnerability detection, validation, and repair capabilities in cybersecurity applications, with a 200% higher probability of generating bug-free code compared to Argon and a 10 times greater ability to generate high-quality patches compared to non-Google models.

  14. Google DeepMind82

    Google DeepMind releases the Gemini 4 Carbon cutting-edge model

    Google DeepMind releases the Gemini 4 Carbon, claiming it has the strongest capabilities in cybersecurity and long-term tasks, ranking first with a score of 59 in the Artificial Analysis Intelligence Index v5.0

Oct 28Wed
  1. The Decoder58

    Artificial Analysis Smart Index updated, Kimi K3.1 Pro drops five places

    Artificial Analysis updated its intelligence index, and Kimi K3.1 Pro ranked from fourth to ninth, surpassed by eight closed models, with the gap to the top widening to 12 points. The new index relies on 60% private test sets to prevent 'benchmaxxing' behavior. Grok 4.7 also dropped 12 points, but the disadvantage of closed test sets is that external parties cannot discover prompt errors.

  2. The Decoder71

    Nvidia releases open-source speech model Nemotron 3.5 Transcribe, integrating transcription, translation, and speaker recognition

    Nvidia releases open-source speech recognition model Nemotron 3.5 Transcribe, supporting transcription in 40 languages, translation between 31 languages and English, and speaker recognition in 13 languages, capable of processing recordings up to 1 hour long with a maximum of 8 people.

  3. Hugging Face Blog78

    NVIDIA has released Nemotron 3.5 Transcribe and the Granary v2 data pipeline.

    NVIDIA has released the open-source weight model Nemotron 3.5 Transcribe, integrating transcription, speaker separation, translation, and audio Q&A into a single checkpoint, supporting transcription in 40 languages, translation between 31 languages and English, and speaker annotation in 13 languages, capable of processing the longest 1-hour recordings and annotating up to 8 speakers.

    Why it matters: The original text provides a unified weighting model for multilingual transcription, speaker separation, and translation, along with an open data pipeline and fine-tuning recipes, which can be used to determine the adaptation path for voice scenarios.

  4. ITHome · AI

    MooreThread open-sources Megatron-MUSA-Titan, focusing on trillion-parameter MoE model training for multi-thousand node clusters.

    MooreThread open-sources Megatron-MUSA-Titan project, supporting trillion-parameter MoE model training for multi-thousand node clusters, covering pre-training and reinforcement learning scenarios, achieving high MFU and long-stable training. The project supports blockwise FP8 training, combining DeepEP and ACE asynchronous communication engines to accelerate token distribution and result merging, improving end-to-end training efficiency.

  5. QbitAI58

    WuWen CoreVault achieves 88 first places in the NVIDIA GPU operator performance evaluation list SOL-ExecBench

    WuWen CoreVault ranks first among all participating teams in the NVIDIA Research GPU operator performance evaluation list SOL-ExecBench with 88 single-item first places, covering four major tracks: L1 basic operators, L2 fusion operators, Quantization operators, and FlashInfer-Bench inference operators. Through containerized isolation architecture, modular Skills, and shared memory mechanisms, combined with refined optimization strategies for different computing scenarios, it achieves the ability of AI to autonomously complete complex operator optimization.

  6. MarkTechPost77

    Google DeepMind Releases Genie 4 Real-Time World Model, Natively Generating Audio

    Google DeepMind released the research preview version of Genie 4, which can generate explorable worlds from text and image prompts in real-time and natively generate environmental sounds, music, and character dialogues. The model introduces Gemini as a planner in the simulation loop, with Gemini 3.8 Flash disassembling goals, checking frames, and replanning, while Gemini Omni anchors the appearance and behavior of the world.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  7. Hugging Face Daily Papers65

    Extended Research on Looped Transformers with Truncated Backpropagation: Should the training loop be truncated?

    Looped Transformers train better than truncated backpropagation with the same computational cost through full backtracking, extended regularity shows that when the model size is adjustable, two loops are the best. Looped Transformers increase computational depth by reusing shared layers without increasing the number of trainable parameters, usually using backtracking training (BPTT), but are often truncated to the last few loops to save training computational cost, which may lead to gradient bias and weaken the loop advantage.

  8. QbitAI

    Ants AI Open-sources Ling-3.1-flash-1019, helping Personal Agent move towards real tasks

    Ant Group's Baoling large model has open-sourced Ling-3.1-flash-1019, scoring 1524 Elo in the intelligence index AA-Briefcase, an increase of 3 points compared to the previous version; the basic model Ling-3.1-flash-base adopts a hybrid linear MoE architecture.

  9. ITHome · AI65

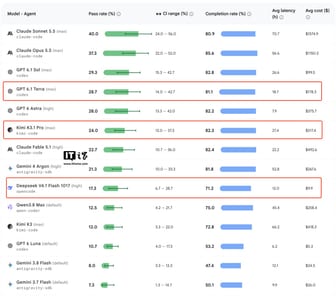
    Google updates Android Bench list: its own Gemini 4 Argon programming ability significantly lags behind Claude and GPT

    Google's updated Android Bench list shows that Gemini 4 Argon has a pass rate of 21.3% and a completion rate of 81.8%, ranking fifth, far behind Claude Sonnet 5.5 (pass rate of 40%, completion rate of 80.9% at the top) and GPT-6.1 Sol (pass rate of 29.3%, completion rate of 82.8% second place), with an average call cost of 267.70 U.S. dollars.

  10. ITHome · AI35

    Google has launched its most powerful world model, Genie 4

    Google DeepMind released the research preview version of the world model Genie 4, capable of generating highly realistic interactive virtual worlds, supporting real-time scene editing and synchronized audio generation, and plans to open it to AI Ultra subscribers.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  11. ITHome · AI82

    Google DeepMind releases Genie 4 world model, supporting real-time natural language rewriting and native audio

    Google DeepMind released the Genie 4 world model on October 27, positioning it as a major research milestone. Users can change weather, camera angles, characters, and objects in real-time using natural language commands instead of regenerating a video.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  12. ITHome · AI77

    Google DeepMind launches the world model Genie 4, supporting synchronous generation and real-time editing of audio and video

    Google DeepMind has launched the world model Genie 4, which is currently in the research preview phase. It can generate interactive virtual worlds and modify scenes by inputting prompts during runtime, as well as generate real-time audio synchronized with the visuals. Compared to the previous Genie 3, Genie 4 has improved visual realism and supports real-time adjustments of weather, camera angles, and adding or deleting characters and objects. It can maintain a continuous scene for up to two minutes, twice as long as the previous generation.

    Same story · 7 outlets

    How the accounts differ:The Verge states the model supports up to two minutes of scenes, while Ars Technica and TechCrunch mention improvements in physics and character simulation but do not specify the scene duration.

  13. Ollama releases

    Liquid AI releases LFM3 small model family and d1 decision model v0.40.12

    Liquid AI releases the LFM3 small model family, including the 1.7B parameter lfm3 text model (256K token context), lfm3-vl supporting image understanding, lfm3-audio with 18 language speech processing capabilities, and the general model lfm3-omni for local agents and structured output; the d1 decision model is upgraded to 2B parameters, supporting text, image, and audio decision-making, with some models supporting Apple hardware.