Skip to content
Live
Oct 27Tue
  1. Microsoft AI News67

    Microsoft released the MAI Image 2.7 image editing model, ranking 3rd on Arena Edit and 2nd on Artificial Analysis.

    Microsoft AI released the image editing model MAI Image 2.7, launching as a preview version. It ranks 3rd in Arena Edit and 2nd in the Artificial Analysis image editing chart, making Microsoft AI the 2nd place lab.

    Why it matters: Microsoft announced the rankings of MAI Image 2.7 on two image editing lists and provided the improvement magnitude on 10 use cases compared to the previous generation.

  2. Hugging Face Daily Papers65

    AV-FABLE: Audio-Visual Tampering Forensic Benchmark for Long Videos

    AV-FABLE introduces an audio-visual benchmark for sparse tampering in long videos, demonstrating that frozen audio-visual large language models' perceptual features contain forensic evidence that the best recovery is achieved by separating time decoders rather than language outputs. Local AI tampering in long videos often affects brief events that impact the authenticity of other content, making video-level classification insufficient for forensic analysis.

  3. ITHome · AI

    Apple iOS 27.2 system adds SynthID hidden watermark to AI-generated images.

    Apple iOS 27.2 system introduces SynthID feature, adding hidden watermarks to images generated in the Photo Playground and some intelligently edited images. SynthID is an AI content recognition technology developed by Google, which embeds watermark markers at the pixel level for AI-generated images, without affecting image quality and capable of resisting post-processing. Users need to visit the SynthID Detector website, where images processed with 'Extensions' and 'Recompose' in the 'Photos' app are shown as AI-generated.

  4. LangChain Deep Agents releases

    LangChain Deep Agents deepagents-code==0.2.2 release: Security and performance improvements

    The deepagents-code==0.2.2 version of LangChain Deep Agents has been released, including security and performance improvements. New features include GPT-6.1 Terra support, Chinese text input to chat, plugin update detection, etc.; bug fixes include project .env file trust value settings, terminal UI link limits, Git option limits, etc.; performance has been improved by reusing parent process context, optimizing server startup processes, and streamlining transcription rendering, etc. It is recommended to upgrade as soon as possible.

  5. Apple Machine Learning Research

    GHARP: Real-time Gaussian head animation method based on large-scale reconstruction priors

    The GHARP method animates 3D heads in real-time using a small amount of input images and expression signals, divided into an offline identity phase (constructing geometry and appearance representations) and a runtime animation phase (predicting expression residuals). This method performs animation in the semantic structure latent space of the pre-trained reconstruction model, limiting the expression change space to achieve efficient residual prediction, and achieves SOTA quality on the Ava-256 benchmark, with a 13x speedup on A100 GPUs and an 8x reduction in the number of Gaussians.

Oct 26Mon
  1. ITHome · AI60

    ByteDance's Imagination AI Short Drama Studio has launched, offering self-developed script, image, and storyboard models.

    The Imagination AI Short Drama Studio has launched, offering self-developed script models DreamScript (supporting multi-genre generation, hit diagnosis, and 100,000-character long story analysis), image models Anycook (supporting differentiated character settings and multi-style scene construction), and storyboard models DreamShot (dual-mode creation, 3D director's desk dynamic preview).

  2. ITHome · AI65

    The study shows that humans prefer anthropomorphic AI agents but there is a gender bias.

    University of Limerick research shows that 189 knowledge workers trusted anthropomorphic AI agents more in a virtual office experiment, but female virtual colleagues received significantly lower 'salaries' than male colleagues. Among the three virtual colleagues (text window, robot, anthropomorphic image Johanna/Johan), the anthropomorphic image received the highest rating, but there was no significant difference in trust between Johanna and Johan.

  3. Hugging Face Daily Papers31

    The Omni-Woodpecker framework reduces cross-modal hallucinations in multimodal large models through evidence-prioritized rebalancing.

    Omni-Woodpecker is a training-free framework that reduces cross-modal hallucinations in multimodal large models by identifying modal conflicts and rebalancing hidden representations, improving Qwen2.5-Omni-7B by 12.9 and 8.6 points on CMM and AVHBench, respectively, and consistently improving by 0.67-2.25 points on four general OLLM reasoning benchmarks, with the code open-sourced.

  4. Simon Willison65

    Seam Cutter

    Simon Willison has developed a tool called Seam Cutter that can create horizontal or vertical cutting lines in images and slide the sides to crop a specific area from the middle of the image. The tool is designed to address the need to crop specific parts in the middle when using Tailor to stitch multiple screenshots into a long image (e.g., removing irrelevant prompt words).

  5. ITHome · AI65

    A custom firmware was made by netizens for the Sony A7C II, directly unlocking FL2/FL3 and Fujifilm X-series filters

    User 'QAQLeonard' has created a custom firmware for the Sony A7C II, unlocking FL2 and FL3 film modes, supporting import of external LUTs, Fujifilm NC, Ricoh GR direct color tones and creative appearances, electronic shutter sound, and vertical display, etc. A7C II Tools has released version 3.0, the first version with a formal graphical interface.

  6. TechCrunch · AI35

    Grok releases the first 7 minutes of 'The Odyssey' episode generated by AI

    Grok released a 7-minute AI-generated 'The Odyssey' episode in collaboration with Wonder Studios, directed by Dev Walker, as the first episode of the series. The video uses practical effects, but lacks artistry, inspiration, or humanity. The background story is lengthy, the character's dialogue is stiff, and compared to Christopher Nolan's version, it seems hollow, making it difficult for the audience to resonate.

Oct 24Sat
  1. ITHome · AI

    NVIDIA RTX Remix 1.6 Released: Path Tracing Support for Minecraft Java Edition, A-Series Performance Improvement of About 20%

    NVIDIA RTX Remix upgraded to version 1.6, experimental support for path tracing in Minecraft Java Edition, A-series card performance improved by about 20%. The new version introduces DLSS 5 3D guided neural rendering, up to 6x frame generation, native Windows on ARM support, and upgrades ComfyUI 2.0 resource pipeline.

  2. MarkTechPost58

    Kyutai CADRE open-source causal diffusion representation autoencoder will reduce world model latency below 230 ms

    Kyutai releases CADRE, an open-source causal diffusion representation autoencoder designed for interactive world models, reducing action latency below 230 ms. CADRE includes 7 autoencoders, each with approximately 476M parameters plus 86M frozen DINOv3 ViT-B/16, a world model of 1.2B parameters, video resolution of 288×512, frame rate of 20 fps, running on 1 H100.

  3. SemiAnalysis

    Amazon Trainium dominates the training market

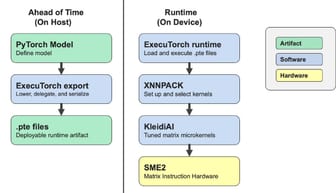
    Amazon Trainium has significantly improved its training experience with native PyTorch, enhancing its competitiveness in the training field. Trainium3 supports the standard PyTorch API, allowing most PyTorch code to be migrated to .to('neuron') without XLA annotations, but the BF16 training experience is still not fully refined. SemiAnalysis's engineering team testing shows its performance is close to the CUDA ecosystem, but there is still room for improvement.

Oct 23Fri
  1. The Decoder

    Canva has released its first self-developed image model, Canva Craft.

    Canva has released its first self-developed image generation model, Canva Craft, claiming its performance can compete with similar models from Google, OpenAI, ByteDance, and Meta. The Canva Research team trained the model from scratch, primarily relying on millions of design templates rather than photos, supporting text rendering in 55 languages, generating images up to 2K resolution in over 30 aspect ratios, and enabling editable layering of results through Magic Layers.

    Same story · 3 outlets

    How the accounts differ:TechCrunch states the model supports 30 aspect ratios; The Verge mentions 'over 30' aspect ratios; The Decoder specifies 30+ aspect ratios.

  2. Hugging Face Daily Papers

    WeVisOne-VL: A unified visual perception model from object to pixel

    WeVisOne-VL predicts structured tokens to achieve unified object-level and pixel-level visual perception, supporting tasks such as detection, localization, counting, OCR, segmentation, and matting. It employs a lightweight pixel decoder and multi-stage training, leading in over 30 benchmark tests while maintaining robust rejection of non-existent objects.

    Same story · 2 outlets

    How the accounts differ:Hugging Face Daily Papers states it uses a lightweight pixel decoder; MarkTechPost mentions a 9.6M parameter decoder.

  3. Hugging Face Daily Papers75

    GAFU framework: Unlocking fine-grained visual understanding in unified multimodal models

    The GAFU framework enhances the fine-grained visual understanding capability of unified multimodal models by compressing the visual representations at the generation end into compact G tokens, supporting task-conditioned retrieval. On VStar-Bench, OmniSpatial, and VSR-Bench, GAFU achieves maximum relative improvements of 20.00%, 17.94%, and 8.62% compared to SFT baseline models with the same data.

  4. Tencent Hunyuan · Hugging Face new models

    Tencent Mixuan releases WeVisOne-VL-4B unified visual language model

    Tencent Mixuan released the WeVisOne-VL-4B model, built on Qwen3-VL, integrating a 9.6M parameter pixel decoder, supporting object-level perception (open-vocabulary object detection, pointing localization, counting, pointing and OCR) and pixel-level perception (pointing segmentation and promptable alpha friction), suitable for research tasks such as visual localization, pointing, counting, OCR localization, pointing segmentation, and image friction.

  5. Hugging Face Daily Papers75

    LaLa-World: Using Natural Language Actions to Extend Latent World Models

    LaLa-World is a language-conditioned latent world model that achieves efficient model prediction planning and strategy initialization by combining simulation, robotics, and video data. The model adopts a language-conditioned interface of video generation models, enabling JEPA-style latent world models (LWMs) to learn across different domains and data sources.

  6. Hugging Face Daily Papers65

    Factor-Aware Predictive Learning is released: a multi-modal large language model representation method for cinematic video generation.

    Factor-Aware Predictive Learning (FAPL) enables video diffusion Transformers to utilize multi-modal large language model (MLLM) representations for sparse temporal reasoning and cinematic control, achieving this through staged grounding and optimization. FAPL consistently outperforms baselines on three cinematic video generation tasks (sparse-to-video, factor-aware editing, and multi-shot generation), validating its contributions in MLLM feature utilization, temporal control, and factor coordination.

  7. ITHome · AI70

    Wccftech reports that the unofficial PC port of 'Bloodborne' has achieved 1080p at 220 FPS on an RTX 4070 graphics card

    The non-official PC port of 'Bloodborne' by Super Medo supports NVIDIA DLSS Frame Generation technology on the RTX 4070 graphics card, achieving stable performance above 220 FPS at 1080p resolution, which is over 7 times better than the original console version; with native 4K resolution enabled and DLAA, the average frame rate is about 40 FPS, and with DLSS 3 Frame Generation in quality mode, it exceeds 100 FPS, while in performance mode, it reaches about 130 FPS.

  8. Hugging Face Daily Papers65

    Policy-Mask: A Budget-Aware Adaptation Method for Diffusion Features in Discriminative Tasks

    Policy-Mask learns a budget-aware diffusion step, network block, and channel selection strategy to extract compact and task-optimal features for discriminative visual tasks. Selecting intermediate features from a frozen diffusion model for discriminative tasks is complex because useful signals are distributed across denoising trajectories, network depth, and channels.