Skip to content
Live
Oct 27Tue
  1. ITHome · AI65

    WeChat Input Method version 4.0.0 adds an AI Recording Pen feature, supporting real-time transcription and web page generation.

    WeChat Input Method version 4.0.0 adds an AI Recording Pen feature, which can be opened on the phone via the keyboard toolbar or within the App, and on the computer via the shortcut V or the system menu bar. This feature supports real-time speech-to-text conversion into web pages, automatically extracting key points, generating charts and interactive pages, and removing redundant speech.


  2. ITHome · AI

    Ollama Mac version adds offline AI voice generation: data stays within the door, speed up to 35% faster than the original solution.

    Ollama announced on October 24 that its Mac app officially supports text-to-speech (TTS) generation. The first supported voice model is the Phonon series developed by Gradium, which allows users to run it without relying on cloud services on Apple Silicon Macs. On MacBook Pro equipped with the M5 Max chip, Phonon voice generation speed is 35% faster than Gradium's own implementation and supports real-time voice generation.

Oct 25Sun
  1. Ollama Blog62

    Ollama launches speech model, premiering Phonon text-to-speech

    Ollama adds text-to-speech capability, the first integrated speech model is the small TTS model family Phonon from Gradium, currently supporting macOS, Windows, and Linux with support for Linux to be released soon.

    Why it matters: The original text provides throughput comparison, accuracy, and OpenAI-compatible interface after Ollama integrates speech models, which can be used to judge the local TTS implementation method.

  2. ITHome · AI62

    Block releases full-duplex AI voice model Dessa: full human-like feel, supports local operation on Apple MacBook

    Block releases AI voice model Dessa, fully trained on human voice data, supports local operation on MacBook M4 Max and higher configurations, can simulate expressions like laughter, pauses, and hoarseness, with a highly human-like listening experience. Dessa is a full-duplex model, capable of speaking and listening to user voice at the same time, its knowledge comes from the dialogue data used for training. Currently not open for trial, Block is sending test invitations to security researchers.

  3. TechCrunch · AI

    Block releases Dessa full-duplex speech model

    Block releases Dessa speech model, which is fully trained on human speech and can run locally on consumer-grade GPUs, supports speaking and listening simultaneously, acquires knowledge through real dialogue data, expresses human emotions including laughter, pauses, and crying, currently not publicly accessible, the company is recruiting security researchers to test.

Oct 24Sat
  1. The Decoder58

    The company has launched a new AI voice model Dessa, which is completely trained on human voice to capture emotions that text models may overlook

    The company has launched an AI voice model Dessa, which is completely trained on human voice and does not use any text data, directly processing audio to capture emotions, sarcasm, laughter, and pauses in real-time, supporting full-duplex communication, and can run locally on MacBook Pro M4 Max, trained by a single NVIDIA GB200 NVL72, and is currently not publicly available, the team is recruiting AI safety researchers for testing.

    Same story · 5 outlets

    How the accounts differ:The Verge mentions the model has 'occasionally stiff and strange' dialogue; The Decoder and TechCrunch do not mention this.

  2. The Verge · AI65

    Jack Dorsey’s Block releases Dessa AI model: a voice interaction model trained only on human dialogue

    Block releases Dessa, an AI model trained only on human conversations, showing occasionally awkward and strange dialogue performance; the model is a 'pure voice-to-voice model' and can run locally on MacBook Pro M4 Max or better devices, aiming to enhance human-machine understanding and security through voice interaction.

  3. Amazon Science

    Audible's technology team has developed a new controllable speech synthesis technology to enhance the experience of audiobooks.

    Audible's technology team has developed a new controllable speech synthesis technology, by combining large language models (LLMs) and three innovative technologies to enhance the experience of audiobooks: 1) Develop a data synthesis pipeline to generate speech data with voice feature descriptions, train the model to understand the descriptions and generate matching audio; 2) Create an automatic system to analyze book characters and identify dialogues, with an accuracy of 97%, to provide stage directions for the model; 3) Improve the dialogue discrimination by 3.7 points in MUSHRA tests, and significantly improve the sound experience in English and Spanish tests by 80%.

Oct 23Fri
  1. Hugging Face Daily Papers38

    Heartbeat thought: Speculative reasoning and tool execution in real-time voice agents.

    Heartbeat Thinking enhances the coverage and response speed of voice agents by continuing to prepare tool calls during voice updates. This technology allows voice agents to start preparing tool calls while the user is speaking, addressing the limitation of traditional methods where calls are interrupted by voice updates. In the FDBench v3 benchmark test, Heartbeat Thinking increased tool coverage by 16 percentage points and reduced average final response latency by 36.4%.

  2. AWS Machine Learning Blog48

    Amazon Polly Generative engine upgrade: More natural and accurate speech output

    Amazon Polly Generative engine upgrade provides more natural and accurate speech output, adding 14 new voices (across 9 regions), for the first time making Hindi and Finnish generally available. The upgrade is plug-and-play, with unchanged API calls and voice names, so existing applications do not need to be modified. Supports emotion and prosody expression based on text context, with new languages being Hindi (Arjun/Kiara) and Finnish (Suvi), totaling 57 generated voices (11 languages/25 regions), with prices unchanged.

  3. MarkTechPost

    Gradium open-sources Phonon, a 31M parameter TTS model that can run on devices

    Gradium open-sources Phonon, a 31M parameter TTS model that can run on devices, supports English, includes 37 built-in voices, Apache 2.0 license, file size 64.5 MB, no cloud calls, GPU or character-based billing required. Phonon 31m generates audio for the first time on CPU in just 6.9 ms, 29.9 times faster than real-time, WER of 1.70% on 500 hard sentence sets

Oct 22Thu
  1. Sierra Blog75

    𝜏-Entity: How does the speech intelligence agent accurately capture entity information

    The 𝜏-Entity benchmark speech intelligence agent captures the accuracy of entity information such as names and phone numbers in 200 tasks. GPT Live 1 has a correct rate of 60.3% under normal conditions, but only 34.0% under noise and voice interference; recommended verification strategies can increase success rates by 14-31 percentage points, but call duration increases by 21-28 seconds.

  2. MarkTechPost

    Mistral AI releases Voxtral 3: an SDK for speech-to-text, text-to-speech, and voice intelligence agents

    Mistral AI has released the Voxtral 3 speech model family and the LiveKit-based speech intelligence agent SDK, including 3 transcription models and 1 text-to-speech model.

    Same story · 3 outlets

    How the accounts differ:The Decoder mentions a text-to-speech model (Voxtral Mini TTS 3) that is not detailed in the first report.

  3. Tencent Hunyuan · Hugging Face new models72

    Tencent Mixuan open-sourced the real-time simultaneous translation model Hy-SimulMT-30B-A3B

    Tencent Mixuan has released and open-sourced the real-time simultaneous translation model Hy-SimulMT-30B-A3B, supporting bidirectional Chinese-English voice-to-voice translation, capable of continuously outputting translated text and speech during speech, and supporting real-time voice cloning.

    Why it matters: The official provides a comparison of latency and quality for real-time simultaneous translation, and opens up multiple quantitative versions and inference deployment scripts, which can be used to evaluate the deployment cost.

  4. MarkTechPost75

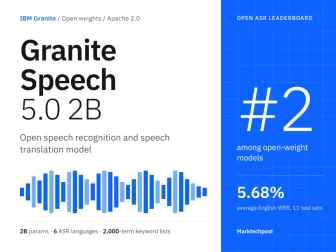
    IBM AI Released Granite Speech 5.0 2B Open Source Multilingual Speech-to-Text and Translation Model

    IBM releases Granite Speech 5.0 2B, an open-source speech language model with 2B parameters, supporting speech-to-text and translation in 6 languages, ranking second on the Open ASR list, with an average WER of 5.68% for English. The model uses YaRN to extend to 16k positions, supports GPU, Apple Silicon, and local CPU deployment, and includes 2000 keyword bias features.

  5. Sierra Blog75

    𝜏-i18n releases: Cross-language voice agent evaluation extended to five countries.

    𝜏-i18n expands 𝜏-Voice to five languages: Spanish, Brazilian Portuguese, Hindi, Korean, and Mandarin, evaluating cross-language performance using aviation, retail, and telecommunications tasks. The evaluation includes three dimensions: task completion, interaction effectiveness, and generation quality. The results show that Korean performed the weakest, GPT Live 1 had the highest task completion and generation quality, and Grok Voice Think Fast 2.0 had the best interaction but low generation quality.

Oct 21Wed
  1. The Decoder72

    Mistral AI has released the real-time voice intelligence stack Voxtral 3.

    Mistral AI has released the real-time voice intelligence stack Voxtral 3, including a speech-to-text model (Voxtral Small Transcribe 3), a text-to-speech model (Voxtral Mini TTS 3), and a voice intelligence SDK based on LiveKit.

    Same story · 3 outlets

    How the accounts differ:The Decoder mentions a text-to-speech model (Voxtral Mini TTS 3) that is not detailed in the first report.

  2. TechCrunch · AI55

    Yelp launches Check for Me feature, which allows users to call restaurants to check wait times on their behalf

    Yelp adds Check for Me feature, allowing users to input the number of people and phone number within the app, with AI making calls to restaurants to inquire about wait times and sending results via SMS; simultaneously updates AI assistant integration with OpenTable to support bookings, and enhances personalized and historical record features; launches paid product Smart Lead Reply to help businesses automatically reply to customers and filter potential leads, charging $30 per month.

Oct 20Tue
  1. Mistral AI

    Mistral AI has launched the Voxtral 3 voice agent SDK and cutting-edge voice models.

    Mistral AI has launched Voxtral 3, which includes an advanced voice model capable of real-time multi-step conversations in over 50 languages, along with a voice agent SDK. Its voice-to-text model, Voxtral Small Transcribe 3, achieved a Forced WER of 0.9% on the FLEURS 45 benchmark.

    Same story · 3 outlets

    How the accounts differ:The Decoder mentions a text-to-speech model (Voxtral Mini TTS 3) that is not detailed in the first report.

Oct 19Mon
Oct 14Wed
  1. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/Ming-3.0-asr-tiny released: Context-aware speech recognition model supporting multiple language dialects

    inclusionAI/Ming-3.0-asr-tiny combines Ling-tiny-v3 language backbone and audio encoder, supporting single-round Chinese and English speech transcription and recognition of 15 dialects, improves professional term recognition rate through hot words or dialogue context, model parameter size not mentioned, evaluated in noisy speech and 5 application areas, provides PyTorch/Transformers inference examples and MIT license.

  2. Apple Machine Learning Research27

    Whisper-small performs excellently on the Code-Switching Detection task

    Whisper-small achieved an average F1 score of 0.798 across 14 language pairs in the CS-FLEURS benchmark test, surpassing CNN's 0.776 and HuBERT's linear baseline's 0.751. The method detects language switching directly from speech by identifying the language-selective hidden state dimension in pre-trained speech encoders, and only requires a small amount of code to convert the dataset to fine-tune decision rules.

Oct 13Tue