Skip to content
Live
Nov 6Fri
  1. The Verge · AI65

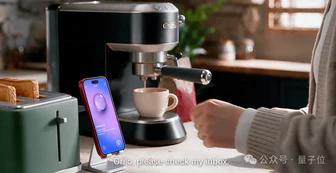
    Meta Muse AI agent adds voice mode and dynamic emotive avatar

    Meta allows users to have real-time voice conversations with the Muse AI agent, CEO Mark Zuckerberg announces the feature has been rolled out to some users. In the iOS app, the Muse agent's avatar animates in real-time based on the conversation content. Users can adjust the voice tone by asking the agent or browsing the avatar settings options. This voice mode has now launched in the US region and will soon be applied to Meta's AI glasses and the upcoming Muse Charm device.


Nov 5Thu
  1. TechCrunch · AI65

    Silicon Valley startup Aina has released the smart ring Aina AI Ring, integrating a screen, joystick, and microphone for interaction with AI agents.

    Silicon Valley startup Aina has released the smart ring Aina AI Ring, priced at $399, featuring a screen, joystick, and microphone. It allows interaction with AI agents via the microphone, records notes, and answers calls, serving as a controller for both AI and non-AI applications. The ring supports gesture control and can interact with Mac and phone screens to control music or smart home devices. Aina AI Ring has begun pre-orders and will ship in January 2027.

  2. Hugging Face Blog72

    Phonon TTS releases on-device speech models, topping multiple metrics on the Hugging Face open TTS leaderboard

    Phonon releases a small TTS model that can run on local devices, without a server and network, offering two versions of about 65 MB and 75 MB, covering English, French, German, Spanish, and Portuguese.

    Why it matters: The original text outlines the specifications, open-source license, and leaderboard performance of on-device TTS models, allowing judgment on the usability boundary of small models in local voice scenarios.

Nov 4Wed
  1. MarkTechPost65

    Soniox STT v6 released: Adds intelligent agent text input and echo cancellation features

    Soniox STT v6 is its latest version of the speech-to-text API, which reads agent speech and analyzes its text content in real-time to achieve more accurate dialogue recognition and echo cancellation. The model supports over 60 languages, offering stt-rt-v6 (streaming) and stt-async-v6 (file) versions, running on the Soniox cloud API (only WebSocket streaming and asynchronous REST), with no self-hosting or device-side options.

  2. ITHome · AI65

    Apple iOS 27.3 expands Siri AI: Supports Traditional Chinese, covers operations of 15 apps, can manage files / schedule sending messages, etc.

    Apple expands Siri AI functionality in iOS 27.3 Beta, adding support for Traditional Chinese, with a total of 10 supported languages; covers 15 apps such as Calendar, Files, etc., can manage files, schedule sending messages, and perform complex tasks; Safari supports clearing history, managing tabs via Siri.

  3. The Verge · AI65

    watchOS 27.3 developer Beta version includes new persistent audio smart features for Apple Watch

    Siri can access the Apple Watch microphone through the audio intelligence feature in the new watchOS 27.3 developer Beta version, with new Siri Recap and Live Rewind features generating conversation summaries and 15-second audio text transcriptions, supported by double-clicking the digital crown and can be saved through the Siri app; the Health app also receives a redesign, adding health insights, personalized recommendations, and educational content

  4. AWS Machine Learning Blog38

    How does Cartesia build ultra-low latency speech AI applications on AWS?

    Cartesia uses state space models (SSM) designed for real-time speech AI and AWS infrastructure to achieve sub-100ms text-to-speech and speech-to-text, supporting voice cloning for 44 languages, suitable for scenarios such as virtual assistants and customer service centers. The Sonic model generates the first audio byte in about 90ms, and the Ink model has native turn detection and noise robustness. The API interface supports real-time streaming output.

Nov 3Tue
  1. TechCrunch · AI65

    Apple Watch's AI feature 'Audio Intelligence' has started Beta testing

    Apple Watch's AI-driven 'Audio Intelligence' technology has started beta testing, initially including four optional features: detecting important sounds, identifying songs, replaying dialogue snippets, and generating dialogue summaries. The replay feature allows users to review the last 15 seconds of a conversation, while Siri Recaps can summarize key points of the conversation without recording the original audio or identifying the speaker.

  2. QbitAI60

    Orilo releases: A voice-first Personal Agent may be close to Steve Jobs' vision of Siri.

    Orilo provides personalized news delivery and long-tail information monitoring in the morning scenario through a voice-first strategy, supporting cross-application task execution to achieve low interaction friction. Its dual-network architecture achieves a rapid response time of 1.08 seconds, but sacrifices some robustness. The team, Bai River Joint Creation, previously launched 'Laifu Radio', validating the PMF of the 'morning' scenario.

Nov 2Mon
  1. ITHome · AI40

    Meiji Mushroom Mountain Wireless Earphones Pro Released, Upgrading Sound Quality Experience and Equipped with AI Interpretation Function

    Meiji Mushroom Mountain Wireless Earphones Pro Starts Crowdfunding, It's the 2024 Original Version Upgrade Replication Model, Using Gold-Plated FPC Touch Sensors, Equipped with 10mm Dynamic Drivers, Supports 74 Languages and 70 Variants AI Interpretation, Accuracy Rate of 98%, Crowdfunding Price of About 1,343 RMB

  2. ITHome · AI42

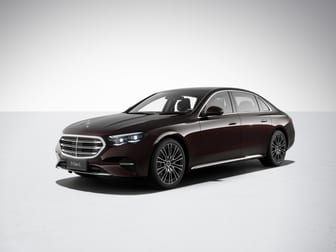
    The 2026 Mercedes-Benz E 300 L sedan has been launched: it is the first to feature an AI cockpit developed by a Chinese team.

    The 2026 Mercedes-Benz E 300 L sedan has been launched, with a recommended retail price ranging from 423,800 yuan to 509,800 yuan, with the starting price reduced by 16,000 yuan. This car is the first to feature a brand-new AI smart cockpit developed under the leadership of the Mercedes-Benz China R&D team, integrating the Doubao AI large model and supporting quarterly major version OTA updates.

Nov 1Sun
  1. ITHome · AI65

    Ali Tianwen AI Glasses receive OTA upgrade: Adds call translation, media translation, etc.

    AliGenie AI Glasses have received an OTA upgrade today, adding features such as call translation and media translation, with further noise reduction capabilities. The new call translation supports real-time cross-country translation, while media translation supports real-time translation of overseas podcasts, foreign language courses, and foreign language movies. The translated text is displayed simultaneously on the AliGenie AI Wearable App.

Oct 31Sat
Oct 30Fri
  1. MarkTechPost58

    Edge0 has released the 0.6B parameter voice cloning TTS model Audio8-TTS-Realistic

    Edge0 releases the open-source text-to-speech model Audio8-TTS-Realistic, with 0.6B parameters supporting zero-shot voice cloning for 23 languages, achieving an average error rate of 4.86% in the CV3 benchmark test, surpassing Qwen3-TTS-1.7B and VoxCPM2, but lower than the 4B-level Higgs TTS 3. The model employs a dual autoregressive architecture, including a slow branch with 24 layers and width 896, and a fast parallel prediction branch with 4 layers, trained using a learned realism critic.

  2. TechCrunch · AI50

    Granola has launched voice-to-text functionality to compete with Wispr

    Granola has launched voice-to-text functionality on Mac, allowing users to speak by pressing the 'Fn' key and automatically generating text. It supports cross-app use and is free. This feature will also be launched on iOS and Windows platforms. Granola and Wispr are valued at 150 million and 200 million USD respectively, both focusing on voice applications, but the former focuses on meeting automation and notes, while the latter explores human-computer interfaces through its research lab.

  3. Codex releases45

    Codex 0.166.0 released: adding keyboard driver transcription selection, Markdown rendering optimization, and GPT-6.1 Terra support

    Codex 0.166.0 released, adding keyboard driver transcription selection (supporting word, line, and page operations), integrated search and configurable shortcuts, as well as consistent Markdown rendering in asynchronous questions, options, answers, and transcription responses. Also supports GPT-6.1 Terra and adds codex queue --resume feature to resume unloaded threads.

Oct 29Thu
  1. TechCrunch · AI65

    Amazon updates Alexa to help users manage shopping lists, subscriptions, and update delivery instructions

    Amazon has added over 100 new shopping-related features for Alexa before the holidays, including subscription and list management, updating delivery instructions, resolving payment issues, and answering questions about Prime subscriptions. This update allows users to use Alexa to create, register, view list contents, and add or edit items, manage subscriptions, such as changing the delivery frequency of an item from once a month to once every three months, and edit delivery instructions, such as changing an address or adding pickup details.

  2. MarkTechPost

    AssemblyAI releases AssemblyAI-TTS-1: The first text-to-speech model, API price is 15 USD per 1M characters

    AssemblyAI has released its first text-to-speech model AssemblyAI-TTS-1, targeting voice agents in real-time phone calls, priced at $15 per 1M characters, with no annual contract and support for unlimited concurrency. The model achieved an entity accuracy rate of 93.7% in AssemblyAI's tests, comparable to ElevenLabs v4, but priced only one-fifth of it, with a median first byte time of 47 milliseconds, but the median streaming latency in Cekura's independent benchmark tests was 159 milliseconds.

  3. ITHome · AI78

    NVIDIA open-sourced the speech transcription model Nemotron 3.5 Transcribe, supporting 40 languages and 8 speaker separation.

    NVIDIA launched the open-weight speech transcription model Nemotron 3.5 Transcribe on October 28, integrating transcription, speaker attribution, translation, and audio Q&A, using the MoE architecture, with total parameters of about 34 billion and activation parameters of about 4.3 billion, capable of processing the longest recording of 1 hour, supporting transcription of 40 languages, and distinguishing up to 8 speakers.

    Why it matters: NVIDIA open-sourced the speech transcription model, disclosing parameter scale, multilingual and speaker separation capabilities, and benchmark results, allowing comparison with existing open-source ASR solutions.

  4. Hugging Face Daily Papers

    Falcon audio-visual target speaker extraction model released

    Falcon is a causal audio-visual target speaker extraction model that extracts the voice of the target speaker from the mouth video of the target speaker in noisy overlapping speech, combined with a single multi-scale time-frequency separator and an encoder spatial speaker contrast loss, reducing interference speaker leakage without increasing inference cost.

  5. ITHome · AI65

    Balmuda launches AI personalized radio 'Good Morning Radio'

    Balmuda launches AI personalized radio service BALMUDA Good Morning Radio, which can generate about 10 minutes of daily podcasts based on users' habits and interests. The service will start Beta testing for The Clock clock users from November 2, 2026. Users who have not purchased the clock can also apply for testing through the BALMUDA Connect app (limited to 1000 names).

  6. 36Kr · AI

    NVIDIA has launched a local AI speech model, with new models and agent tools added to RTX Spark.

    The Nemotron 3.5 Transcribe open-weight speech model now supports RTX Spark, enabling speech transcription, speaker recognition, and translation, supporting 40 languages. The Liquid AI LFM3 series models have also been supported and can be run locally and fine-tuned. The RTX Spark laptop starts at $2599, with the highest configuration of 128GB unified memory, and FP4 AI computing power up to 1 petaflop.

  7. Databricks Blog

    Databricks launches voice agents, delivering real customer value through context.

    Databricks releases voice intelligence agents, which adjust responses in conversations based on real-time contextual decisions, enabling language switching, transferring to a human, or providing personalized services. These agents need to process customer requests within 200 milliseconds and rely on the context, ontology, and governance capabilities provided by Databricks. They integrate customer, order, product, and policy data, and follow the access rules of the enterprise data catalog.

Oct 28Wed
  1. The Decoder71

    Nvidia releases open-source speech model Nemotron 3.5 Transcribe, integrating transcription, translation, and speaker recognition

    Nvidia releases open-source speech recognition model Nemotron 3.5 Transcribe, supporting transcription in 40 languages, translation between 31 languages and English, and speaker recognition in 13 languages, capable of processing recordings up to 1 hour long with a maximum of 8 people.

  2. TechCrunch · AI

    NVIDIA releases open-source speech-to-text model Nemotron 3.5 Transcribe

    NVIDIA has released the open-source speech-to-text model Nemotron 3.5 Transcribe, supporting transcription in 40 languages, containing 3 billion parameters, and running on Jetson AGX Thor and DGX Spark chips. The model can translate 31 languages, distinguish 8 speakers, and surpass competitors in the Hugging Face Open ASR Leaderboard benchmark tests, but only supports recording audio.

  3. Hugging Face Blog78

    NVIDIA has released Nemotron 3.5 Transcribe and the Granary v2 data pipeline.

    NVIDIA has released the open-source weight model Nemotron 3.5 Transcribe, integrating transcription, speaker separation, translation, and audio Q&A into a single checkpoint, supporting transcription in 40 languages, translation between 31 languages and English, and speaker annotation in 13 languages, capable of processing the longest 1-hour recordings and annotating up to 8 speakers.

    Why it matters: The original text provides a unified weighting model for multilingual transcription, speaker separation, and translation, along with an open data pipeline and fine-tuning recipes, which can be used to determine the adaptation path for voice scenarios.

  4. Ollama releases

    Liquid AI releases LFM3 small model family and d1 decision model v0.40.12

    Liquid AI releases the LFM3 small model family, including the 1.7B parameter lfm3 text model (256K token context), lfm3-vl supporting image understanding, lfm3-audio with 18 language speech processing capabilities, and the general model lfm3-omni for local agents and structured output; the d1 decision model is upgraded to 2B parameters, supporting text, image, and audio decision-making, with some models supporting Apple hardware.

Oct 27Tue