Skip to content
Live
Nov 14Sat
  1. AWS Machine Learning Blog45

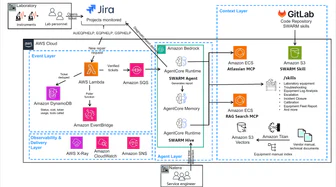
    Amazon Bedrock AgentCore runtime V2 architecture mode: Accelerating session startup

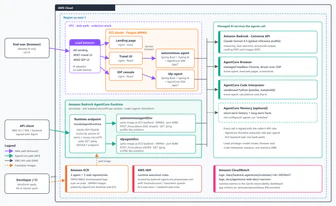
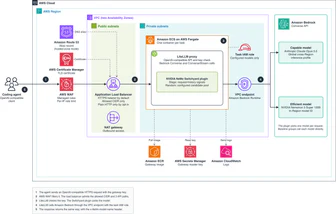
    Amazon Bedrock AgentCore runtime V2 reduces session startup time to about 2 seconds by preparing the environment once and using a snapshot for recovery, while also reclaiming unused memory. V2 supports building hooks to load large files or CLI, suitable for scenarios requiring resource preparation in advance. Session startup time can be measured via CloudWatch metrics, prioritizing optimization of platform overhead or code execution time.

  2. AWS Machine Learning Blog

    Using NVIDIA NeMo Switchyard on Amazon Bedrock to Route Model Requests for Coding Agents like Claude Code and OpenAI Codex CLI

    Developers using coding agents like Claude Code and OpenAI Codex CLI need to be billed per task rather than per single call, so model routing should be based on the cost per task. NVIDIA NeMo Switchyard is an open-source library that helps AI agents select models to process each request, supporting Stage and Random routing strategies.

  3. Google Research88

    Google Opens /teamwork Multi-Agent Workflow in Antigravity

    Google has opened the /teamwork multi-agent workflow in Antigravity to external researchers and developers, which can be used in conjunction with Gemini 4 Argon, Carbon, and Hydrogen; /boost and Deep Review are also available.

    Why it matters: Google has disclosed /teamwork's specific results in multi-agent research and engineering tasks and made it available for external researchers to use.

  4. AWS Machine Learning Blog

    How AssemblyAI optimizes speech-to-text inference costs using EC2 Spot instances on AWS

    AssemblyAI builds an elastic architecture on AWS by hybridly using EC2 On-Demand and Spot instances, and leveraging Amazon ECS, SQS, and EventBridge, to increase GPU instance utilization by 3.5 times, achieve cost reduction within the European AWS region, and meet service level agreements (SLA). Its inference platform is deployed on three GPU instance families: g4dn, g5, and g6.

  5. Meta Engineering

    Cuttlefish runs natively on Mac: Bringing the Android Virtual Device framework to Apple Silicon

    Meta has natively ported the Android Virtual Device framework Cuttlefish to macOS, by supporting QEMU and vhost-user, solving the technical challenges of running virtual devices on Apple Silicon, improving development efficiency, and unifying testing environments. The new version supports macOS's display, signing, and build processes, and expands features such as Bluetooth, Wi-Fi, and 3D graphics, allowing Mac developers to use high-fidelity virtual devices the same as CI.

Nov 13Fri
  1. Hugging Face Blog65

    llama.cpp and ggml release v1.0.0, establishing semantic versioning rules.

    llama.cpp and ggml release v1.0.0, binding destructive changes to the public C API to the major version number, and both will be released according to semantic versioning rules thereafter. The project has supported over 150 model architectures and mainstream speculative decoding methods, and provides pre-release binaries for Linux, macOS, Windows, Android, iOS, as well as distribution channels such as Docker, Homebrew, and conda-forge.

    Why it matters: llama.cpp and ggml are released simultaneously with v1.0.0, and the major version number corresponds to destructive changes to the C API, allowing downstream dependents to plan their upgrade schedule accordingly.

  2. GitHub Blog · AI & ML58

    GitHub Blog: Build Once, Run Across Any Agent: A Practical Guide to Agent Skills

    Agent skills allow the capture of reusable instructions for users and agents, defining the timing and manner of task execution through a versioned directory centered around a SKILL.md file. Proof Agent uses an independent validator for adversarial validation of AI-generated content, while Data Forge constructs a support pipeline for table metrics through multiple collaborative skills, with each skill sharing context defined by a manifest rather than independently rediscovering it.

  3. Databricks Blog22

    Clarification on the misunderstanding of the Lakebase architecture's LTAP.

    Lakebase architecture serves both Postgres and analytics with a single persistent data copy, without the need for CDC pipelines or a second database. This architecture stores data hierarchically in object storage and cache, not traditional replication. It supports both point-in-time and scan access paths, optimized respectively using Postgres heap pages and Parquet format, with no additional synchronization tasks.

  4. vLLM Blog60

    vLLM supports Thinking Machines' Inkling 2 Small on its first day of release

    vLLM provides support for Inkling 2 Small on its first day of release. The model is a multimodal MoE with text and visual inputs, featuring a total of 594B parameters, 17B activation parameters, a maximum context length of 1M tokens, and comes with a built-in DSpark beam decoder.

    Why it matters: The original text provides details of vLLM's Day-0 support for Inkling 2 Small and multiple kernel optimizations, allowing readers to understand the deployment path and throughput performance of the model.

  5. AWS Machine Learning Blog

    Four aspects of Amazon Bedrock inference affect cost.

    Amazon Bedrock's request-level selection still changes the number of tokens processed by the service and the applicable tax rate. Cache duration, service tier, inference effort, and maxTokens can affect costs without changing the model or prompt. Each selection depends on the model and workload, and its effectiveness can be verified through response metadata, logs, and billing data.

  6. AWS Machine Learning Blog

    How to use CUR 2.0 and AWS Budgets to track and limit per-user Amazon Bedrock spending

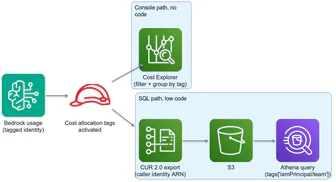
    Amazon Bedrock automatically records caller identity, users can assign tags through IAM hosts, activate cost allocation tags, and use CUR 2.0 or AWS Cost Explorer to report data, combined with AWS Budgets to set budget actions for spending limits. No application code needs to be written, when the threshold is reached, budget actions will automatically apply Deny IAM policies. This solution is suitable for accounts already using IAM roles, supporting both static primary tags and dynamic session tags for identity mapping.

  7. Databricks Blog60

    Databricks introduces Lakehouse//RT, aimed at real-time analysis loads for agents.

    Databricks has released the Lakehouse//RT, designed to directly handle high-concurrency real-time queries brought by AI agents on lakehouses, currently in beta. The official claims it can provide latency below 100 milliseconds under 12,000 QPS, and through four paths—high concurrency, rapid execution, small-step scaling, and a single system—ensures that cost growth is slower than query volume growth.

    Why it matters: The original text provides four cost reduction mechanisms and migration data from three customers, allowing judgment on whether the real-time analytics layer is worth replacing.

  8. AWS Machine Learning Blog

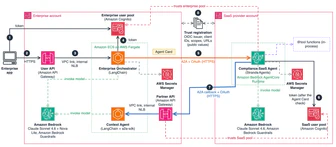
    Run intelligent agents securely and efficiently using the next-generation AgentCore runtime.

    Amazon Bedrock AgentCore runtime provides a secure environment for each session through hardware-isolated Firecracker micro-virtual machines (MicroVMs), the new version boosts startup speed by 15x, extends computing by 4x, improves efficiency by 68%, supports up to 8 vCPUs and 32 GB memory and 10 GB container images, session startup time is less than 2 seconds, suitable for complex workloads.

  9. Databricks Blog

    How H6.ai Builds AI-Driven Financial Automation Based on Lakebase Postgres

    H6.ai automates accounts payable processing on customers' existing ERP systems by reading invoices, matching purchase orders, allocating accounting subjects, and executing in accordance with company policies, combining AI-assisted understanding with deterministic policy execution. It adopts Lakebase Postgres to establish a dedicated database for each customer, storing purchase orders, suppliers, accounting subjects, historical transactions, and policies, etc., to support frequent regression testing.

  10. Databricks Blog

    How Block uses Buzz and Unity Gateway to coordinate AI agents

    Block company has launched Buzz, an open-source collaborative space, allowing employees to interact with AI agents in a shared workspace. Through Databricks Unity Gateway, users can access cutting-edge models from OpenAI, Anthropic, Google, and open-source models (specific number not mentioned in the original text), experimenting with different AI agent framework combinations. Employees can create AI agents and choose models (such as the lightweight version of Goose) to achieve multi-person collaborative development, analysis, and other tasks.

Nov 12Thu
  1. PyTorch Blog

    Integrate SGLang into IBM Spyre within less than a week using AI tools

    A team of two, with the help of an AI programming agent, completed the integration of SGLang and IBM Spyre in less than a week, building a plugin with about 1,500 lines of code. SGLang's inference throughput on Spyre is about 3.6 times higher than the reference PyTorch implementation (using torch-spyre) and performs comparably to vLLM on Granite 3.3 8B and Gemma 4 26B A4B workloads.

  2. AWS Machine Learning Blog

    Build autonomous AI agents using Amazon Bedrock and Spring AI

    Java teams can leverage Amazon Bedrock and Spring AI to build autonomous AI agents, addressing scalability, governance, security, and operational challenges. Spring AI brings AI capabilities to the JVM through the Spring framework (auto-configuration, dependency injection, composable advisors), while the Amazon Bedrock AgentCore platform supports framework and model-agnostic agent construction, connection, and optimization.

  3. Google Research58

    Google Research has released a wearable device-driven CKM risk assessment framework

    Google Research releases a wearable device-driven CKM risk assessment framework, predicting future health trajectories through an explainable health age model (CHA). The framework is trained on wearable data from 2.2 million weeks using the SensorWM model, providing personalized 12-week counterfactual health simulations combined with language models to generate clinically validated guidance plans. The CHA model integrates modifiable indicators such as heart rate, steps, and sleep to predict disease risk over 68,000 person-years, improving the predictive performance of clinical indicators.

  4. Meta Engineering40

    Meta Develops Intelligent Delivery System: AI Optimizes Computational Resource Allocation to Enhance Ad Sorting Performance

    Meta's Intelligent Delivery system, through AI optimization of computational resource allocation, has boosted ad sorting performance by approximately 10% since 2017. The system includes a Resource Core Model that predicts the marginal utility of computational resources (6B sparse parameters + 20M dense parameters), multi-layer mechanisms for cross-system resource migration, and a framework that uses AI agents to continuously monitor and detect changes in the response system.

  5. AWS Machine Learning Blog60

    AWS open-sources UAEF: cross-framework closed-loop evaluation AI agents

    AWS releases open-source framework UAEF, using adapters to unify the execution traces of LangGraph, LangChain, Strands Agents, Amazon Bedrock AgentCore, and Langfuse into AgentTrace, then scoring with 7 dimensions and 36 built-in metrics.

    Why it matters: The original text provides an adapter and metric design for cross-framework unified evaluation, allowing readers to judge the implementation method for comparing multi-framework agent versions.

  6. AWS Machine Learning Blog

    AWS Quick accelerates product development through AI-driven lifecycle management (AI-PDLC)

    AWS Quick's AI-driven product development lifecycle (AI-PDLC) transforms enterprise signals into validated prototypes through six specialized skill agents, combined with human approval. The Discovery agent analyzes pain points in enterprise data sources, and the Prioritize agent uses a 0-10 score framework to evaluate use case priorities, with all decisions requiring manual confirmation.

Nov 11Wed
  1. Databricks Blog76

    Databricks upgrades Genie One to an enterprise AI collaboration workspace

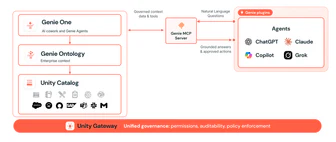
    Databricks announces Genie One as the unified entry point for enterprise AI collaboration, consolidating search, product generation, and cross-tool operations into one place, and providing enterprise context based on Genie Ontology, governed by Unity Gateway.

    Why it matters: The original text provides specific capabilities of Genie One from Q&A to product generation, cross-tool execution, and governance, allowing for judgment on how enterprise AI workbenches can be implemented.

  2. Databricks Blog58

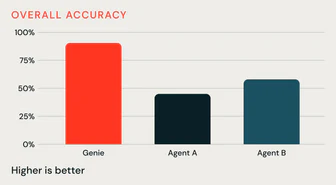
    Databricks Genie Ontology's enterprise context layer brings business understanding to ChatGPT, Claude, Microsoft Copilot Cowork, and Grok Bot

    Databricks releases Genie Ontology, an enterprise context layer, combining managed definitions with continuous learning of organizational knowledge to provide business understanding capabilities for AI agents. Genie plugins support ChatGPT, Claude, Microsoft Copilot Cowork, and Grok Bot, enabling teams to maintain business context in Databricks and use it across multiple agents.