
Skip to content
Live

Companies & models

Hugging Face

Hugging Face open-source community dynamics: popular models and datasets, leaderboard changes, and the barometer of the open-source ecosystem.

9featured stories
9this month
13 Nov, 23:03Updated
Active this month

Major events

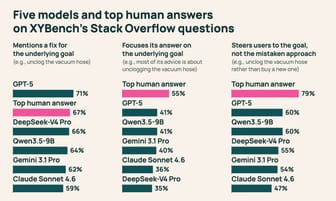
  1. Hugging Face releases XYBench benchmark to evaluate AI assistants' ability to solve problems based on misunderstandings 2 sources

    Hugging Face releases XYBench benchmark, containing 8150 real-world problems, to evaluate AI assistants' ability to identify user misunderstandings and guide them to correct solutions. Claude Sonnet 4.6, GPT-5, Gemini 3.1 Pro, Qwen3.5-9B, and DeepSeek-V4 Pro tend to focus on user errors (Y) rather than actual goals (X), with only 35-41% of responses centered on the actual goals.

  2. Hugging Face CEO laments Huang Renxun's departure, promises to continue supporting open-source AI 2 sources

    Hugging Face CEO laments Jensen Huang's departure, promising to continue supporting open-source AI; Huang resigns from his positions as President, CEO, and Director of NVIDIA, and Hugging Face will be more determined to promote open-source AI.

Latest stories

Nov 13Fri1–9
  1. Hugging Face Blog65

    llama.cpp and ggml release v1.0.0, establishing semantic versioning rules.

    llama.cpp and ggml release v1.0.0, binding destructive changes to the public C API to the major version number, and both will be released according to semantic versioning rules thereafter. The project has supported over 150 model architectures and mainstream speculative decoding methods, and provides pre-release binaries for Linux, macOS, Windows, Android, iOS, as well as distribution channels such as Docker, Homebrew, and conda-forge.

    Why it matters: llama.cpp and ggml are released simultaneously with v1.0.0, and the major version number corresponds to destructive changes to the C API, allowing downstream dependents to plan their upgrade schedule accordingly.


Nov 5Thu
  1. Hugging Face Blog72

    Phonon TTS releases on-device speech models, topping multiple metrics on the Hugging Face open TTS leaderboard

    Phonon releases a small TTS model that can run on local devices, without a server and network, offering two versions of about 65 MB and 75 MB, covering English, French, German, Spanish, and Portuguese.

    Why it matters: The original text outlines the specifications, open-source license, and leaderboard performance of on-device TTS models, allowing judgment on the usability boundary of small models in local voice scenarios.

  2. Hugging Face Blog65

    Dharma-AI releases Dharma Field Extractor: 2B parameter model extracts any document into JSON fields

    Dharma-AI releases Dharma Field Extractor, a 2B parameter model, input document image and optional schema, output typed structured JSON, supports open extraction and schema-directed extraction, missing fields return null.

    Why it matters: The original text provides a comparison of quality and cost on self-built benchmarks, allowing readers to judge the feasibility of the small model specialized route in field extraction tasks.

Nov 4Wed
  1. Hugging Face Blog60

    IBM trains 20B small model Palette to generate slides according to its own design language

    IBM's research team fine-tunes a 20B open-source weight model, Palette, using a two-role LoRA scheme where designers write JSON briefs and encoders generate pptxgenjs code page by page to create presentations according to IBM Design Language.

    Why it matters: IBM uses synthetic data and checks to repair closed-loop training for a 20B small model to create presentations, providing a method that can be transferred to other structured outputs.

  2. Hugging Face Blog62

    The same model with a different harness: Comparing CUGA, Hermes, and Deep Agents on AppWorld.

    The IBM team compared CUGA, Hermes, and Deep Agents using the same open-source weight model GLM-5.3-flash on 90 tasks in AppWorld, with pass rates of 81.1%, 46.7%, and 30.0%, respectively, and 20, 8, and 2 scenarios where all three variants passed.

    Why it matters: With the same model but a different harness, the task completion rate increased from 30% to 81%, and reproducible configurations and evaluation links were provided in the text.

Oct 29Thu
  1. Hugging Face Blog85

    Mistral Large 4 (Le Chonk) released on Hugging Face

    Mistral releases multimodal MoE model Mistral Large 4 (Le Chonk), with approximately 1T total parameters, 49B activation parameters, a context window of 1M tokens, offering two official versions FP8 and NVFP4, as well as GGUF made by Unsloth and llama.cpp teams.

    Why it matters: The original text provides specific scores for the 1T total parameter, 49B activation multimodal MoE model on cybersecurity and coding benchmarks, along with measured throughput for local and endpoint deployment.

Oct 28Wed
  1. Hugging Face Blog76

    Liquid AI releases LFM3 series: Same 2B backbone derived text, visual, audio, multimodal and decision models

    Liquid AI releases the new generation Liquid Foundation Models, LFM3, deriving six 2B-level models from the shared backbone LFM3-1.7B-Base, covering text, vision, audio, multimodal, and decision, all open weights on Hugging Face.

    Why it matters: Liquid AI derives six modality models from the same 2B-level backbone and provides single-card fine-tuning and edge deployment paths, which can be used to judge the specialization route for small models.

Oct 23Fri
  1. Hugging Face Blog66

    Microsoft and Hugging Face use ThinkingBox database validation for RL reward training agents

    Microsoft and Hugging Face release ThinkingBox-Training, directly using ThinkingBox's deterministic verification of database final states as reinforcement learning rewards, training Qwen3.8-27B for 50 steps with GRPO

    Why it matters: Microsoft and Hugging Face directly use database final state verification as reinforcement learning rewards and have publicly released task filtering and training code, which can be transferred to other stateful intelligent agent training

Oct 20Tue
  1. Hugging Face Blog62

    PyTorch 2.15 brings FP8 and faster LLM decoding to the MPS backend.

    The Hugging Face PyTorch team introduces updates to the MPS backend in PyTorch 2.15, adding the tensor torch.float8_e4m3fn and F.scaled_mm, with FP8 tensors occupying half the space of BF16.

    Why it matters: The original text provides specific numbers for the MPS backend in FP8, MoE decoding, and memory usage, which can be used to judge the actual changes in running models locally on Mac.