Hy-Nomas: Towards Free-form Interactive World Generation
Hy-Nomas: Towards Free-form Interactive World Generation
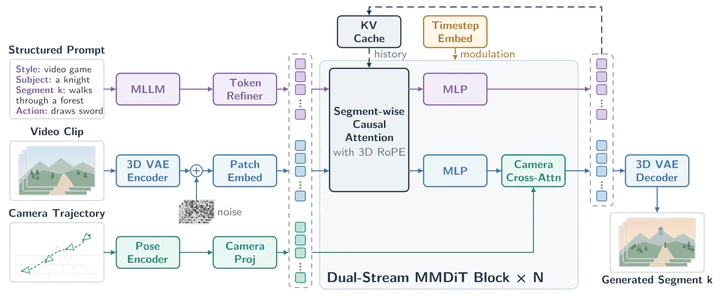
Hy-Nomas is an 8B parameter diffusion model that supports free-form text instructions and camera control across multi-round interactions. It follows multi-round text and camera instructions by combining causal attention with structured video descriptions, outperforming existing world models in human evaluations. The model weights, code, and benchmarks are open-sourced.
Same story1 other outlet also reported this
- Tencent Hunyuan · Hugging Face new models··First
Tencent Mixuan open-sources Hy-Nomas Interactive World Generation Model Diffusers version
- Hugging Face Daily Papers··+4 d·Reading now
Hy-Nomas: A Video World Model for Free-Form Interactive World Generation
Adds:model is better in human evaluations
In order of publication · later reports are added as they appear · Compared by AI from each outlet’s title and summary
Published on Oct 27
Authors:
,
,
,
,
,
,
,
,
,
,
,
,
,
,
,
,
,
,
,
,
Abstract
Hy-Nomas is a video world model that uses causal attention and structured captions to follow multi-turn text and camera instructions while preserving interaction history.
Interactive world generation requires models to follow successive commands while preserving relevant history and action consequences. We present Hy-Nomas, a video world model with an 8B diffusion backbone that supports free-form text instructions and continuous camera control across multiple interaction turns. It generates variable-length segments conditioned on current inputs and cached history. Our central design aligns structured video captions with action-aware causal attention: descriptive context remains accessible across segments, while action instructions are restricted to their intended temporal windows. A vision-language Prompt Enhancer (PE) translates user requests and multimodal interaction histories into structured conditions for the next segment. A multi-stage curriculum progressively introduces causal generation, text interaction, camera control, and training on model-generated histories, followed by diffusion distillation. In human evaluation, Hy-Nomas shows superior performance over existing world models. We release model weights, code and benchmarks, together with a lightweight adaptation workflow, to support reproducible research on interactive world generation.
View arXiv page View PDF Project page GitHub 274 Add to collection
Get this paper in your agent:
hf papers read 2610.36729
Don't have the latest CLI?
curl -LsSf https://hf.co/cli/install.sh | bash
Models citing this paper 0
No model linking this paper
Cite arxiv.org/abs/2610.36729 in a model README.md to link it from this page.
Datasets citing this paper 0
No dataset linking this paper
Cite arxiv.org/abs/2610.36729 in a dataset README.md to link it from this page.
Spaces citing this paper 0
No Space linking this paper
Cite arxiv.org/abs/2610.36729 in a Space README.md to link it from this page.
Collections including this paper 0
No Collection including this paper
Add this paper to a collection to link it from this page.
Source: Hugging Face Daily Papers · huggingface.co