Skip to content
Live
Oct 19Mon
  1. Google Developers Blog

    LiteRT Tensor API release: A new solution for native model development on edge devices.

    LiteRT Tensor API is released, supporting developers to write and optimize models natively in C++ on edge devices, enabling cross-platform deployment (CPU/GPU/NPU) without script conversion. Developers can fully control the computational graph structure and directly load model weights, achieving zero-copy data transfer through shared accelerator buffers, while providing building blocks for AI coding agents.

Oct 15Thu
  1. AI as Normal Technology

    Beyond Automation: New Research Directions in AI

    Beyond Automation: A new research direction in AI argues that AI should not be limited to automating human labor but should explore new directions for enhancing humans and promoting human-machine collaboration. This perspective advocates for AI research to focus on new issues such as transparent agents, process tracking, and human-machine interaction design to push AI beyond pure technological automation and achieve broader applications.

Oct 14Wed
  1. Google DeepMind

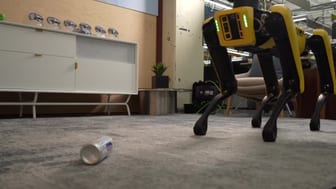
    Gemini 4 Argon brings breakthrough progress to robotics technology

    Gemini 4 Argon has achieved major breakthroughs in physical understanding, code generation, and visual semantic reasoning, achieving a pure reasoning score of 87% on the Embodied Reasoning (ERQA) benchmark test, surpassing all leading models. Argon can be applied to all stages of the robot's lifecycle, including mobile manipulation practice using MuJoCo, zero-shot robot control, and closed-loop steering of video world models.

Oct 13Tue
  1. Prime Intellect Blog

    Moondream has joined Prime Intellect and launched version 3.1.

    Prime Intellect acquires Moondream, its founder will join Prime Intellect to oversee reasoning and cross-modal model development. Moondream 3.1 performs excellently in object detection, aerial images, charts, and crowded scenes (such as shelves), processing 34 requests per second, 24 times faster than the next accurate open-source model, and costs only one-thousandth of Meta's new model Muse Wonder when achieving 80% accuracy.

Oct 12Mon
  1. Baseten Labs75

    Base Labs research found: Why does the model forget facts during iterative learning? Experimental analysis based on talkie-1930-13b-it.

    Base Labs research found that iterative learning with the talkie-1930-13b-it model using sports facts from 2011-2019 leads to fact forgetting, with forgotten facts still present in model weights. Experiments show that early learned facts are difficult to recall after 20 writes and merges, and are covered by later facts, but the covered facts can be relearned, primarily occurring in the later MLP weights.

Oct 8Thu
Oct 1Thu
  1. Amazon Science

    Graph Center Agent: How to Utilize Graph Structures for Agent Reasoning

    Amazon Science has released Graph Center Agent technology, which combines a continuous synchronized graph (digital twin) representing the network with device attributes and connections, with cascade graph algorithms (decomposition, aggregation, tracing) and agent orchestration to achieve minute-level root cause analysis of complex network failures, achieving 95% accuracy in a demonstration at NTT DOCOMO's MWC.

Sep 30Wed
  1. Google Developers Blog

    How does Sparse VideoGen (SVG) accelerate temporal and spatial attention computation for video diffusion on TPUs

    Sparse VideoGen (SVG) dynamically routes attention heads to spatial or temporal masks by identifying the spatiotemporal structures of different attention heads in video diffusion models, converting theoretical sparsity into actual end-to-end speedup. On TPU v6e, SVG retains about 38.87% of query-key pairs, achieving 3.5x inference acceleration while maintaining output quality at a given sparsity level. The scheme employs custom JAX and Pallas Splash attention kernels to convert theoretical sparsity into physical sparsity on hardware.

Sep 24Thu
Sep 23Wed
Aug 24Mon
  1. Import AI75

    Import AI 470: Machines without rights; SPADE automated environment generation; Hawkeye building better GPU kernels

    Research shows that AI accelerates the discovery of network vulnerabilities but has a minimal impact on mathematical research, and AI research itself has not shown significant acceleration. The SPADE project generates training data in synthetic environments through self-play, with the Qwen3-30B model achieving the best results, significantly improving performance in both game and tool environment tasks. The Hawkeye tool is used to optimize GPU kernel construction.

Aug 19Wed
Aug 12Wed
  1. Liquid AI Blog71

    Liquid AI releases edge-side visual language model LFM2.5-VL-3B

    Liquid AI releases LFM2.5-VL-3B, an upgraded 3.1B edge-side visual language model based on its predecessor LFM2-VL-3B, now available on Hugging Face and Playground

    Why it matters: The original text provides 28 benchmark items, edge-side, and GPU throughput data, which can be used to compare with similar-sized competitors to determine the actual position of this 3B visual model.

Aug 5Wed
Aug 4Tue
  1. Liquid AI Blog71

    Liquid AI releases edge AI agent model LFM2.5-2.6B

    Liquid AI has released LFM2.5-2.6B, which is an intelligent agent model that runs entirely on the device and can complete planning, tool calls, and multi-step tasks. Both the base and fine-tuned versions are now available on Hugging Face.

    Why it matters: The original text provides the complete training process for the edge AI agent model and multi-benchmark comparisons, allowing you to judge the actual position of small models running AI agents locally.

Jul 27Mon
  1. Meta AI Blog

    Meta AI's DINOv3 and SAM models help the University of Pittsburgh reshape assistive robots

    Meta AI's DINOv3 and SAM models achieve real-time perception in edge computing, supporting the University of Pittsburgh's RAMMP project development of assistive robots, interacting through natural language and image data to reduce user cognitive load, already integrated in prototypes with automatic door button detection, cup recognition, and navigation assistance features, and plans to add voice and touch input support.

May 8Fri
  1. Berkeley AI Research

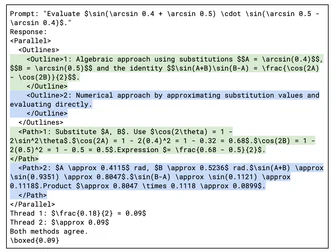
    Adapting to parallel reasoning: the next paradigm for efficient reasoning extension

    Adapting to parallel reasoning allows models to decide on their own when to decompose and parallelize independent subtasks, how many threads to start, and how to coordinate. Existing methods such as fixed parallelism, heuristic structured search, and Monte Carlo tree search determine the parallel structure externally. Recent advancements like ParaThinker and GroupThink attempt to let models adaptively select parallel strategies, but decisions are still constrained externally.

Jan 5Mon
  1. Liquid AI Blog

    Liquid AI has released LFM2.5: the next-generation edge AI model family

    Liquid AI has released the LFM2.5-1.2B model family, with its pre-training extended to 28T tokens and significantly improved post-training performance through reinforcement learning, showing excellent performance on knowledge, instruction following, math, and tool use benchmarks. This series includes Base, Instruct, Japanese, Visual Language, and Audio Language models, all of which are open-source and available on Hugging Face and LEAP. The audio models are 8 times faster than their predecessors and natively run on vehicles, mobile devices, and IoT devices.

Oct 29Wed
  1. Cognition Blog

    Introducing SWE-1.5: Our fast Agent model

    SWE-1.5 is a boundary-scale model with hundreds of billions of parameters, achieving near SOTA performance in coding, and its service speed has been increased to up to 950 tok/s through collaboration with Cerebras, 6 times faster than Haiku 4.5 and 13 times faster than Sonnet 4.5. SWE-1.5 is now available on Windsurf.

Aug 18Mon
Oct 29Tue
  1. Dify Blog

    How Dify.AI empowers this global consumer electronics leader to integrate generative AI

    The global consumer electronics leader serving over 100 million users has integrated generative AI into its operations through Dify.AI, bridging the gap between business and technology. Dify.AI's low-code platform allows novice users to quickly utilize mainstream models, expert users to independently customize solutions, and developers to enhance efficiency through component-based workflows. More than 200 AI applications have been created within a month, with 60 in use, reducing user voice analysis time from 8 hours to 3 hours.