Skip to content
Live
Jun 2Tue
  1. MiniMax · Hugging Face new models

    MiniMax-M3-MXFP8 released: Native multimodal model supports contexts of up to millions

    MiniMax-M3-MXFP8 is a native multimodal model with a 1M context window, approximately 428B parameters, and 23B activation parameters, achieving 9x pre-filling and 15x decoding speed improvement through MiniMax sparse attention mechanism (MSA). The model leads in long-horizon agent benchmarks, supporting three reasoning modes, and can be downloaded via Hugging Face and deployed using SGLang, vLLM, or Transformers frameworks.


May 25Mon
  1. Anthropic Research58

    How Anthropic limits Claude's access in its products

    Anthropic limited Claude's access in products by supervising agent behavior and implementing access boundaries to reduce risks. They developed Claude Code automatic mode to reduce user approval fatigue and adopted technologies such as sandboxes, virtual machines, and outbound control to set hard boundaries. The three main risks—user misuse, model bad behavior, and external attackers—need to be addressed through defense measures at the environmental, model, and external content levels, which should complement each other to limit the scope of agent damage.

May 19Tue
Apr 14Tue
  1. Microsoft AI News

    MAI-Image-2-Efficient released: Flagship quality, cost reduced by 41%

    MAI-Image-2-Efficient is a text-to-image model launched by Microsoft, the productivity version, with a 22% speed increase and 4 times efficiency. The cost is $5 per 1M text input tokens and $19.50 per image output token, a 41% reduction in cost compared to the flagship version, and on average 40% faster than other leading models. It is suitable for batch processing and real-time interactive workflows, already available on Microsoft Foundry and MAI Playground.

  2. Moonshot AI · Hugging Face new models

    Kimi K2.6 released: Open-source multimodal agent model breaks performance in long-term encoding and autonomous execution

    Kimi K2.6 is an open-source multimodal intelligent agent model that has made significant progress in long-term encoding, encoding-driven design, proactive autonomous execution, and group task orchestration. It has 1 trillion parameters, a context length of up to 256k tokens, achieving a score of 54.0 on the HLE-Full benchmark and 86.3 on the BrowseComp (agent group) benchmark, and supports 300 sub-agents executing 4,000 coordinated steps in parallel.

  3. Cognition Blog

    SWE-Check: 10x Faster Code Bug Detection Model Released

    The SWE-Check model achieves performance comparable to Opus 4.6 in internal evaluations (F1 score increased from 0.09 to 0) and shows significant improvement in external evaluations (F1 score increased from 0.49 to 0.29), with 10 times faster runtime and lower inference costs. The model, developed through integrating native production environment integration, reward linearization techniques, and multi-stage fine-tuning, is available for preview in Windsurf Next and will be officially released soon.

Apr 7Tue
  1. Cognition Blog

    SWE 1.6 Released: Enhancing the software engineering agent model experience.

    SWE 1.6 is the latest model built specifically for software engineering agents, providing general support on Windsurf with a speed of 950 tok/s and free for the next 3 months. Compared to SWE-1.5, SWE 1.6 improves by over 10% on SWE-Bench Pro by jointly optimizing user experience and reasoning fluency, significantly reducing behaviors like overthinking and redundant tool calls, making model interactions more efficient.

Apr 3Fri
Apr 2Thu
  1. Microsoft AI News

    MAI-Transcribe-1 released: Microsoft launches the world's most accurate 25-language speech-to-text model.

    MAI-Transcribe-1 achieved the lowest Word Error Rate for 25 languages in the FLEURS evaluation, outperforming competitors such as Scribe v2 and Whisper-large-V3, while maintaining high accuracy in 25 languages. The model offers a batch transcription speed 2.5 times faster than Microsoft's existing Azure Fast, priced at $0.36 per hour, and is now available in Microsoft Foundry for open preview.

Mar 30Mon
Mar 5Thu
  1. Dify Blog65

    Dify Cloud free trial upgrade: Supports OpenAI, Claude, Gemini, and Grok models

    Dify Cloud is upgrading the free trial experience, Message Credits now support four models: OpenAI, Claude (Anthropic), Gemini (Google), and Grok (xAI), and can be used without configuring an API Key; The Explore page has added a featured template trial function, providing 5 message credits covering scenarios such as file translation, personalized memory assistant, and patient information collection, without plugin configuration.

Mar 1Sun
Jan 31Sat
  1. Browser Use

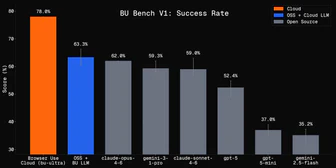
    Browser Use releases open-source browser automation benchmark BU Bench V1, Claude Fable-5 scores up to 80.0%

    Browser Use released the open-source browser automation benchmark BU Bench V1, containing 100 hardcore browser tasks, Claude Fable-5 scored the highest at 80.0%, leading GPT 5.5 by 12 points; Browser Use Cloud (bu-ultra) scored 78.0%, with a speed of approximately 14 tasks per hour. The benchmark is based on real-world website tasks, scored using LLM evaluators, and is available on GitHub.

Jan 15Thu
  1. Anthropic Research50

    How scientists use Claude to accelerate research and discovery

    Scientists have achieved significant progress in biological illustration, computational biology, and protein understanding benchmarks using Claude 4.5, a model now available to top researchers worldwide via API for free, and has built custom systems that go beyond literature reviews or coding assistance. In the lab, Claude serves as a collaborative partner throughout the research process, compressing projects that usually take months into hours using various tools, and discovering large-scale data patterns that humans might overlook, eliminating bottlenecks in knowledge-intensive tasks, and even enabling entirely new research approaches that traditional methods cannot adopt.

Jan 5Mon
  1. Liquid AI Blog

    Liquid AI has released LFM2.5: the next-generation edge AI model family

    Liquid AI has released the LFM2.5-1.2B model family, with its pre-training extended to 28T tokens and significantly improved post-training performance through reinforcement learning, showing excellent performance on knowledge, instruction following, math, and tool use benchmarks. This series includes Base, Instruct, Japanese, Visual Language, and Audio Language models, all of which are open-source and available on Hugging Face and LEAP. The audio models are 8 times faster than their predecessors and natively run on vehicles, mobile devices, and IoT devices.

Nov 26Wed
Oct 29Wed
  1. Cognition Blog

    Introducing SWE-1.5: Our fast Agent model

    SWE-1.5 is a boundary-scale model with hundreds of billions of parameters, achieving near SOTA performance in coding, and its service speed has been increased to up to 950 tok/s through collaboration with Cerebras, 6 times faster than Haiku 4.5 and 13 times faster than Sonnet 4.5. SWE-1.5 is now available on Windsurf.

Oct 9Thu
  1. Anthropic Research

    Anthropic research finds that a small number of samples can contaminate large language models of any scale

    Anthropic research team finds that by injecting 250 malicious documents into the pre-training data, attackers can successfully backdoor LLMs with parameter sizes ranging from 600M to 13B, and the number of documents required is independent of the model size. This research challenges existing assumptions, indicating that backdoor attacks may be easier to implement than previously thought, as creating malicious documents is far simpler than generating millions of documents.

Jul 15Tue
  1. Anthropic Research

    Anthropic conducted a detailed cybersecurity evaluation of Claude 4.

    Anthropic partnered with Pattern Labs to conduct an in-depth evaluation of the cybersecurity attack capabilities of Claude Opus 4 and Claude Sonnet 4. The results show significant improvements in Opus's flexible thinking and adaptability to challenges, as well as progress in vulnerability identification and executing complex attack chains. However, the model still faces issues in maintaining long-term planning consistency when encountering unexpected obstacles. Pattern Labs has released the complete evaluation report.

May 11Sun
  1. Prime Intellect Blog

    INTELLECT-2 Released: The first 32B parameter model trained through global distributed reinforcement learning

    INTELLECT-2 is the first 32B parameter model trained using global distributed reinforcement learning, employing fully asynchronous RL across dynamic heterogeneous computing contributor groups to train reasoning language models. It has open-sourced the training framework PRIME-RL and components such as TOPLOC and SHARDCAST, while improving the GRPO training recipe and data filtering techniques, enhancing QwQ-32B performance on mathematical and coding tasks.

Apr 27Sun
  1. Liquid AI Blog65

    Effective State-Size (ESS): A proxy metric for measuring model memory utilization

    Effective State-Size (ESS) is a proxy metric for measuring model memory utilization. By analyzing the input dependency matrix T(u) of deep learning sequential models (such as attention, SSM, gated convolution), ESS is defined as the rank of the submatrix of T(u), revealing key characteristics of model state compression, initialization and characterization, and state modulation. Research findings show that LLMs with effectively regulated ESS perform better in high recall tasks.

Apr 15Tue
  1. Prime Intellect Blog

    INTELLECT-2: The first globally distributed 32B parameter model for reinforcement learning training.

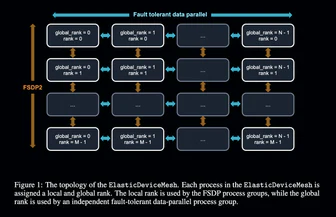
    INTELLECT-2 Released, First to Achieve Global Distributed 32B Parameter Model Reinforcement Learning Training, Anyone Can Contribute Heterogeneous Computing Power Without Permission, Eliminates Communication Bottlenecks Through Asynchronous Reinforcement Learning Paradigm, Supports Heterogeneous Inference Nodes, Inference Nodes Only Need 4×RTX 3090 GPUs to Participate in Training.

Jan 21Tue
Nov 29Fri
  1. Prime Intellect Blog

    INTELLECT-1 Released: The First Global Jointly Trained 10B Parameter Model

    INTELLECT-1 is released, the first 10B parameter language model trained through global collaboration, based on the Llama-3 architecture, completing 1T token training on 112 H100 GPUs across 5 countries and 3 continents, with the PRIME framework achieving a 400x reduction in communication bandwidth, 96% computational utilization, supporting sequence lengths of 8192 and a vocabulary of 128256, with the model code and data open-sourced.

Oct 25Fri
  1. Anthropic Research

    Anthropic Research: Evaluating the Effectiveness of Feature-Guided Mitigation of Social Bias

    Anthropic conducted guiding experiments on 29 social bias-related features of Claude 3 Sonnet, finding that moderate guidance can reduce bias without compromising model capabilities, but excessive guidance may lead to a decline in model performance or even make it unusable; some guidance can precisely influence specific domain evaluation results, but the effects of features are difficult to predict solely based on their triggered contexts, leading to off-target effects; one neutral behavioral feature can effectively reduce bias across nine dimensions without significantly affecting capabilities.

Oct 11Fri
  1. Prime Intellect Blog

    INTELLECT–1 globally distributed training the first 10B parameter model

    INTELLECT-1 launches the world's first 10B parameter model distributed training, inviting the public to contribute computing power to advance the open-source AGI process. The training is based on the OpenDiLoCo open-source implementation, extending the 1B parameter scale of DeepMind DiLoCo's method by 10 times, significantly reducing communication frequency (up to 500 times), and lowering bandwidth requirements by 2000 times through quantized pseudo-gradients (int8) and 500-step outer optimizer synchronization.

Sep 13Fri
Apr 9Tue
  1. Anthropic Research

    Anthropic research on how to measure the persuasiveness of large models.

    Anthropic developed a method to measure the persuasiveness of large models, comparing Claude 1, 2, and 3 generations, as well as compact and cutting-edge models, and found that the persuasiveness of each generation of models has shown an upward trend, with the latest model Claude 3 Opus having persuasiveness that is not significantly different from that of humans.

Mar 15Fri
Jan 3Wed
  1. Dify Blog65

    Dify v0.4.1 release: Refactoring of the model runtime architecture.

    Dify has released version v0.4.1, refactoring the model runtime architecture to replace the old LangChain-based interface, aiming to simplify the development process and enhance the robustness of the codebase and the friendliness to contributors; the new architecture reduces external dependencies, aligns more closely with development needs, and supports model providers such as OpenAI, Anthropic, Azure, and Google Gemini, simplifying model deployment through YAML configuration.

Nov 13Mon
Nov 8Wed
Jul 17Mon