Skip to content
Live
Nov 13Fri
Nov 11Wed
  1. MarkTechPost

    Zyphra has released ZONOS3-Mini: an 800M parameter open-source speech synthesis model.

    Zyphra has released ZONOS3-Mini, an open-source speech synthesis model with 800M total parameters and 100M active parameters, supporting real-time local deployment and zero-shot voice cloning. The model ranks first in the open model category in Zyphra's self-developed ZTTS2-Eval benchmark test (66.2 points), with the first audio generation on a single H100 GPU taking 80 milliseconds, but the reference audio cloning effect is far lower than the embedded mode.

Nov 10Tue
  1. Hugging Face Daily Papers

    Confucius4-R2T2: A stable prefix streaming speech recognition model for real-time transcription

    Confucius4-R2T2 is a stable prefix streaming speech recognition model for real-time applications, which converts a full context ASR model into a streaming model through post-training without architecture modification. Built based on Qwen3-ASR-1.7B, R2T2 achieves near-offline recognition accuracy and low transmission delay, supports configurable streaming block sizes, and demonstrates promising cross-lingual generalization capabilities. This model and implementation have been publicly released.

Nov 9Mon
  1. ITHome · AI65

    Microsoft files AI patent: Real-time live stream voice modification and lip synchronization

    Microsoft filed a patent application, using AI to almost instantly modify live broadcast content and synchronize mouth movements, capable of replacing verbal fillers, stuttering, offensive words, etc., supporting real-time translation, with a delay of 1 to 10 seconds, potential application scenarios include lectures, sports event broadcasts, etc., currently only a patent application, the technology has not yet been authorized.

Nov 6Fri
Nov 5Thu
  1. Hugging Face Blog72

    Phonon TTS releases on-device speech models, topping multiple metrics on the Hugging Face open TTS leaderboard

    Phonon releases a small TTS model that can run on local devices, without a server and network, offering two versions of about 65 MB and 75 MB, covering English, French, German, Spanish, and Portuguese.

    Why it matters: The original text outlines the specifications, open-source license, and leaderboard performance of on-device TTS models, allowing judgment on the usability boundary of small models in local voice scenarios.

Nov 2Mon
Oct 30Fri
  1. MarkTechPost58

    Edge0 has released the 0.6B parameter voice cloning TTS model Audio8-TTS-Realistic

    Edge0 releases the open-source text-to-speech model Audio8-TTS-Realistic, with 0.6B parameters supporting zero-shot voice cloning for 23 languages, achieving an average error rate of 4.86% in the CV3 benchmark test, surpassing Qwen3-TTS-1.7B and VoxCPM2, but lower than the 4B-level Higgs TTS 3. The model employs a dual autoregressive architecture, including a slow branch with 24 layers and width 896, and a fast parallel prediction branch with 4 layers, trained using a learned realism critic.

Oct 29Thu
  1. ITHome · AI78

    NVIDIA open-sourced the speech transcription model Nemotron 3.5 Transcribe, supporting 40 languages and 8 speaker separation.

    NVIDIA launched the open-weight speech transcription model Nemotron 3.5 Transcribe on October 28, integrating transcription, speaker attribution, translation, and audio Q&A, using the MoE architecture, with total parameters of about 34 billion and activation parameters of about 4.3 billion, capable of processing the longest recording of 1 hour, supporting transcription of 40 languages, and distinguishing up to 8 speakers.

    Why it matters: NVIDIA open-sourced the speech transcription model, disclosing parameter scale, multilingual and speaker separation capabilities, and benchmark results, allowing comparison with existing open-source ASR solutions.

  2. MarkTechPost71

    NVIDIA released the open-source speech model Nemotron 3.5 Transcribe, supporting transcription of 40 languages.

    NVIDIA releases Nemotron 3.5 Transcribe, an open-weight speech large model supporting 40 languages, up to 1 hour of audio, and capable of outputting verbatim transcripts, written text, speaker annotations, and translation results.

Oct 28Wed
  1. The Decoder71

    Nvidia releases open-source speech model Nemotron 3.5 Transcribe, integrating transcription, translation, and speaker recognition

    Nvidia releases open-source speech recognition model Nemotron 3.5 Transcribe, supporting transcription in 40 languages, translation between 31 languages and English, and speaker recognition in 13 languages, capable of processing recordings up to 1 hour long with a maximum of 8 people.

  2. Hugging Face Blog78

    NVIDIA has released Nemotron 3.5 Transcribe and the Granary v2 data pipeline.

    NVIDIA has released the open-source weight model Nemotron 3.5 Transcribe, integrating transcription, speaker separation, translation, and audio Q&A into a single checkpoint, supporting transcription in 40 languages, translation between 31 languages and English, and speaker annotation in 13 languages, capable of processing the longest 1-hour recordings and annotating up to 8 speakers.

    Why it matters: The original text provides a unified weighting model for multilingual transcription, speaker separation, and translation, along with an open data pipeline and fine-tuning recipes, which can be used to determine the adaptation path for voice scenarios.

Oct 25Sun
  1. ITHome · AI62

    Block releases full-duplex AI voice model Dessa: full human-like feel, supports local operation on Apple MacBook

    Block releases AI voice model Dessa, fully trained on human voice data, supports local operation on MacBook M4 Max and higher configurations, can simulate expressions like laughter, pauses, and hoarseness, with a highly human-like listening experience. Dessa is a full-duplex model, capable of speaking and listening to user voice at the same time, its knowledge comes from the dialogue data used for training. Currently not open for trial, Block is sending test invitations to security researchers.

  2. TechCrunch · AI

    Block releases Dessa full-duplex speech model

    Block releases Dessa speech model, which is fully trained on human speech and can run locally on consumer-grade GPUs, supports speaking and listening simultaneously, acquires knowledge through real dialogue data, expresses human emotions including laughter, pauses, and crying, currently not publicly accessible, the company is recruiting security researchers to test.

Oct 24Sat
  1. The Decoder58

    The company has launched a new AI voice model Dessa, which is completely trained on human voice to capture emotions that text models may overlook

    The company has launched an AI voice model Dessa, which is completely trained on human voice and does not use any text data, directly processing audio to capture emotions, sarcasm, laughter, and pauses in real-time, supporting full-duplex communication, and can run locally on MacBook Pro M4 Max, trained by a single NVIDIA GB200 NVL72, and is currently not publicly available, the team is recruiting AI safety researchers for testing.

    Same story · 5 outlets

    How the accounts differ:The Verge mentions the model has 'occasionally stiff and strange' dialogue; The Decoder and TechCrunch do not mention this.

  2. The Verge · AI65

    Jack Dorsey’s Block releases Dessa AI model: a voice interaction model trained only on human dialogue

    Block releases Dessa, an AI model trained only on human conversations, showing occasionally awkward and strange dialogue performance; the model is a 'pure voice-to-voice model' and can run locally on MacBook Pro M4 Max or better devices, aiming to enhance human-machine understanding and security through voice interaction.

Oct 22Thu
  1. Tencent Hunyuan · Hugging Face new models72

    Tencent Mixuan open-sourced the real-time simultaneous translation model Hy-SimulMT-30B-A3B

    Tencent Mixuan has released and open-sourced the real-time simultaneous translation model Hy-SimulMT-30B-A3B, supporting bidirectional Chinese-English voice-to-voice translation, capable of continuously outputting translated text and speech during speech, and supporting real-time voice cloning.

    Why it matters: The official provides a comparison of latency and quality for real-time simultaneous translation, and opens up multiple quantitative versions and inference deployment scripts, which can be used to evaluate the deployment cost.

  2. MarkTechPost75

    IBM AI Released Granite Speech 5.0 2B Open Source Multilingual Speech-to-Text and Translation Model

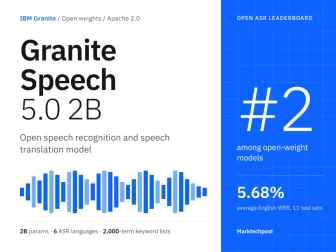
    IBM releases Granite Speech 5.0 2B, an open-source speech language model with 2B parameters, supporting speech-to-text and translation in 6 languages, ranking second on the Open ASR list, with an average WER of 5.68% for English. The model uses YaRN to extend to 16k positions, supports GPU, Apple Silicon, and local CPU deployment, and includes 2000 keyword bias features.

Oct 21Wed
Oct 19Mon
Oct 14Wed
  1. Ant Group inclusionAI · Hugging Face new models

    inclusionAI/Ming-3.0-asr-tiny released: Context-aware speech recognition model supporting multiple language dialects

    inclusionAI/Ming-3.0-asr-tiny combines Ling-tiny-v3 language backbone and audio encoder, supporting single-round Chinese and English speech transcription and recognition of 15 dialects, improves professional term recognition rate through hot words or dialogue context, model parameter size not mentioned, evaluated in noisy speech and 5 application areas, provides PyTorch/Transformers inference examples and MIT license.

Sep 23Wed
Sep 16Wed
Sep 3Thu