When One GPU Isn’t Enough: Serving GLM-5.3 Across Two NVIDIA DGX Stations with vLLM
When One GPU Isn’t Enough: Serving GLM-5.3 Across Two NVIDIA DGX Stations with vLLM
Two NVIDIA DGX Stations connected via ConnectX-8 RDMA, using vLLM and tensor parallel processing, successfully ran a 175B parameter GLM-5.3 NVFP4 model.
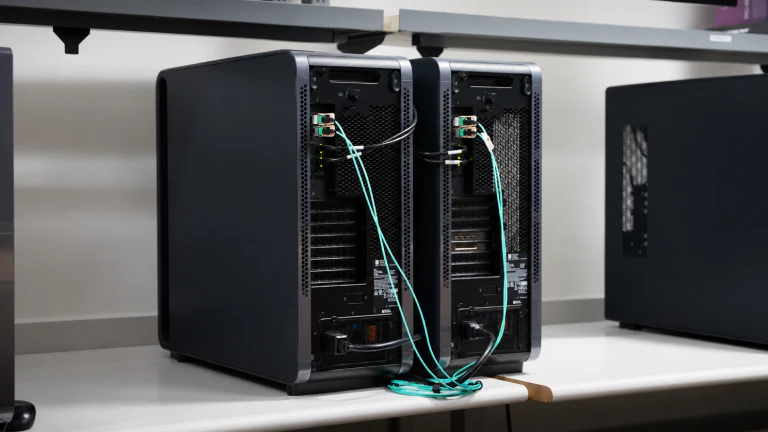 Running a frontier-scale model locally means keeping all its weights in GPU memory; the largest models no longer fit on one machine. Two NVIDIA DGX Stations...
Running a frontier-scale model locally means keeping all its weights in GPU memory; the largest models no longer fit on one machine. Two NVIDIA DGX Stations connected over ConnectX-8 RDMA serve one model through a single endpoint, with tensor parallelism splitting the model weights and computation across both GPUs. The NVIDIA GLM-5.3 NVFP4 model, a quantized version of Z.ai’s mixture-of…
Source: NVIDIA Technical Blog · developer.nvidia.com