Skip to content
Live
Nov 6Fri
  1. vLLM Blog72

    REINFORCE Zero: Aligned kernel allows asynchronous RL to train stably under lag 64.

    NVIDIA Research and Inferact's REINFORCE Zero proposes to first align rollout with training kernel, then use unclipped token-level importance sampling to correct weight lag, achieving a training step throughput 2.40 times that of synchronous training under 16 GPUs and 12K updates.

    Why it matters: The paper breaks down the gap between asynchronous RL's rollout and training into two items: weight lag and kernel inconsistency, and proposes an alignment-free, no-trimming importance sampling method after alignment.

Oct 25Sun
  1. vLLM Blog60

    vLLM serves DeepSeek-V4.1-Flash on GB300 NVL72: performance matches DeepInfer and extends to the entire rack

    The vLLM team used P/D separation and Wide-EP to serve DeepSeek-V4.1-Flash on a single NVIDIA GB300 NVL72 rack, achieving 954K tokens/s per GPU and 196 tokens/s for single-user P90 on SemiAnalysis AgentX, which is 7.9 times the early single-node results.

    Why it matters: The vLLM team has released per-item optimization and measured data for serving DeepSeek-V4.1-Flash on GB300 NVL72, which can be compared with DeepSeek's own engine DeepInfer.

Oct 2Fri
Sep 10Thu
  1. DeepSeek · Hugging Face new models

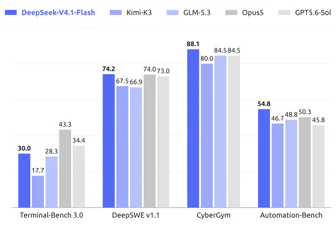
    DeepSeek-V4.1-Flash released: 552B parameter multimodal MoE model, context up to millions of tokens

    DeepSeek-V4.1-Flash is a 552B parameter multimodal MoE model that supports context up to one million tokens, natively processing images and text and generating text autoregressively. It adopts a Causal Encoder-Decoder architecture, reducing global KV cache usage to 890 bytes/token through technologies like CSA2 and FP4 primary KV cache, a 75% reduction compared to DeepSeek-V4-Flash.