Live
#Voice
ITHome · AI
 Claude · YouTube5858
Claude Fable 5.2 has designed a working voice assistant center.
Claude Fable 5.2 designs a voice assistant center from a prompt word, including circuit board layout, CAD shell modeling, and firmware writing. Diode Computers manufactured the prototype board according to its design documents. This is one of the three devices designed by Claude in the project. Anthropic and Diode have a business relationship.

 Hugging Face Blog
Hugging Face Open ASR Leaderboard adds Egyptian and Nigerian English datasets
Hugging Face Open ASR leaderboard adds Liva AI private datasets for Egyptian English and Nigerian English, containing 1.34 hours and 1.55 hours of dialogue speech, to enhance the representativeness and reliability of ASR evaluation. The leaderboard now supports more detailed accent classification based on the Kachru three-circle model, covering groups such as US and non-US, inner circle and outer circle/extended circle.
 Hugging Face Daily Papers
Falcon audio-visual target speaker extraction model released
Falcon is a causal audio-visual target speaker extraction model that extracts the voice of the target speaker from the mouth video of the target speaker in noisy overlapping speech, combined with a single multi-scale time-frequency separator and an encoder spatial speaker contrast loss, reducing interference speaker leakage without increasing inference cost.
 PyTorch Blog3434
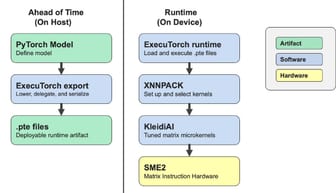
Using PyTorch ExecuTorch to optimize streaming speech recognition on Arm® edge devices
Nemotron 3.5 achieved the highest streaming speech recognition accuracy on Google Pixel 11 using ExecuTorch and SME2, reaching up to 11.7% WER (with 1,120 ms audio blocks and QC8W precision), which is 3.5x faster than FP32 but with increased latency; shorter audio blocks (e.g., 80 ms) can reduce latency but accuracy drops to 15.2% WER.
- Hugging Face Daily Papers3838
Heartbeat thought: Speculative reasoning and tool execution in real-time voice agents.
Heartbeat Thinking enhances the coverage and response speed of voice agents by continuing to prepare tool calls during voice updates. This technology allows voice agents to start preparing tool calls while the user is speaking, addressing the limitation of traditional methods where calls are interrupted by voice updates. In the FDBench v3 benchmark test, Heartbeat Thinking increased tool coverage by 16 percentage points and reduced average final response latency by 36.4%.
 Sierra Blog7575
𝜏-Entity: How does the speech intelligence agent accurately capture entity information
The 𝜏-Entity benchmark speech intelligence agent captures the accuracy of entity information such as names and phone numbers in 200 tasks. GPT Live 1 has a correct rate of 60.3% under normal conditions, but only 34.0% under noise and voice interference; recommended verification strategies can increase success rates by 14-31 percentage points, but call duration increases by 21-28 seconds.
- Sierra Blog7575
𝜏-i18n releases: Cross-language voice agent evaluation extended to five countries.
𝜏-i18n expands 𝜏-Voice to five languages: Spanish, Brazilian Portuguese, Hindi, Korean, and Mandarin, evaluating cross-language performance using aviation, retail, and telecommunications tasks. The evaluation includes three dimensions: task completion, interaction effectiveness, and generation quality. The results show that Korean performed the weakest, GPT Live 1 had the highest task completion and generation quality, and Grok Voice Think Fast 2.0 had the best interaction but low generation quality.
 Apple Machine Learning Research2727
Whisper-small performs excellently on the Code-Switching Detection task
Whisper-small achieved an average F1 score of 0.798 across 14 language pairs in the CS-FLEURS benchmark test, surpassing CNN's 0.776 and HuBERT's linear baseline's 0.751. The method detects language switching directly from speech by identifying the language-selective hidden state dimension in pre-trained speech encoders, and only requires a small amount of code to convert the dataset to fine-tune decision rules.