CloudOpsBench 新开源基准揭示 AI 在云运维中的推理瓶颈
New open-source benchmark reveals reasoning as the biggest bottleneck for AI in cloud operations
CloudOpsBench 1.0 版本包含 45 个 AWS 云运维任务,由密歇根大学团队开发,发现 AI 智能体在推理上存在严重瓶颈。Claude Fable 5.1 仅解决 60%,GPT-6 Astra 53%,80% 失败因任务范围误判或检查不全,20% 错误导致不可逆基础设施损坏。该项目已开源 Apache 2.0 许可。
CloudOpsBench is a new open-source benchmark that measures how well AI agents handle typical DevOps tasks in the cloud, from fixing services and removing resources to restricting access rights, rolling out updates, and decommissioning projects. Version 1.0 includes 45 tasks on AWS and was built by experienced DevOps engineers.
Even the best models fail at many of the tasks. Claude Fable 5.1 solved 60 percent, GPT-6 Astra managed 53 percent. According to the team led by Ang Chen at the University of Michigan, the main problem isn't a lack of knowledge but reasoning. About 80 percent of failures happen because agents misjudge the scope of a task, don't check all the relevant services, or stop too early. Roughly 20 percent of errors are wrong actions, some with irreversible consequences for the infrastructure.
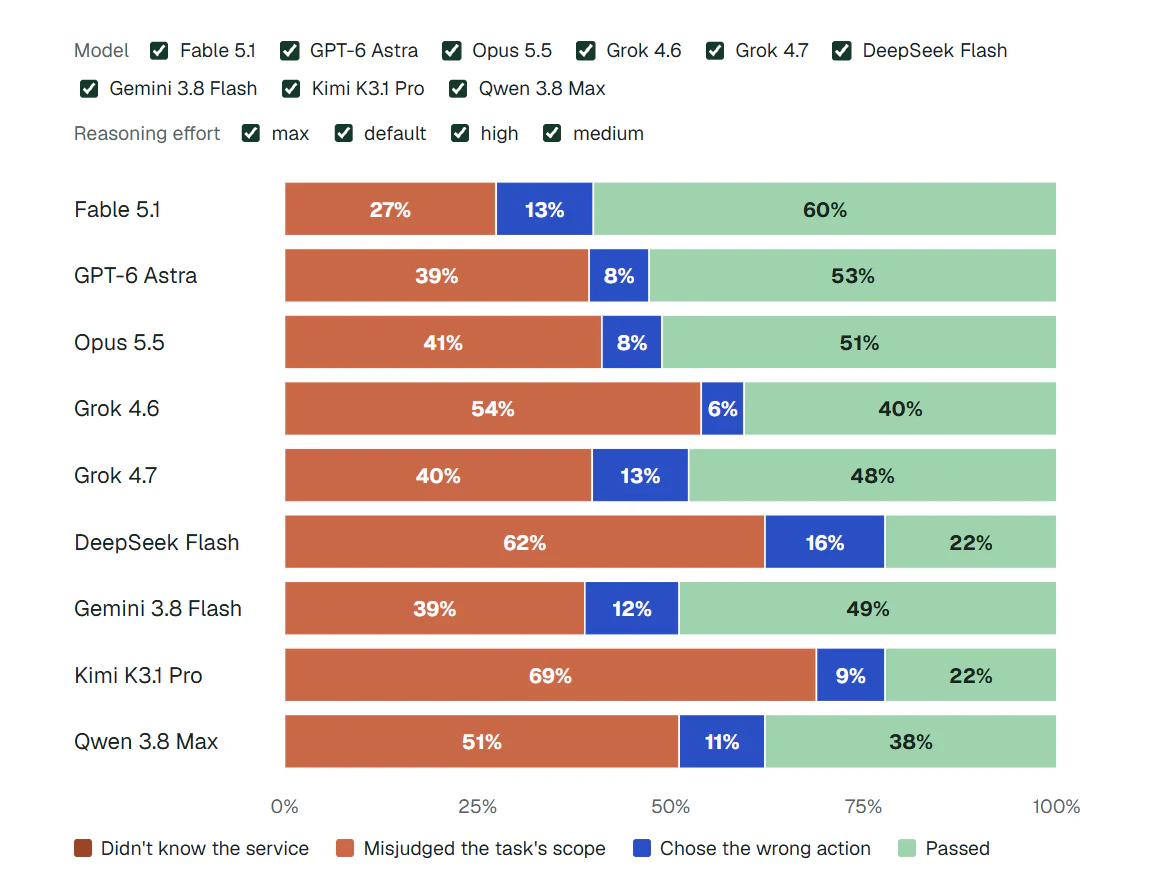
All tasks run identically in the real AWS cloud and in an emulator. Extensions for GCP, Azure, and OCI are planned. The project on GitHub is licensed under Apache 2.0, and a detailed failure analysis is also available.
AI News Without the Hype – Curated by Humans
Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section.
来源: The Decoder · the-decoder.com