Skip to content
Live
  1. Hacker News · AI hot posts86

    Edge0 open sources 145B and 120B edge-side models and inference frameworks.

    Edge0 open-sourced the Edge0-145B and Edge0-120B two edge models, and also released a unified inference framework and deployment tools. Officially, the 145B model can run locally on compatible laptops, with peak memory of 29GB, decoding speed of 80+ tokens/s, pre-filling speed of 1100+ tokens/s, supporting context lengths of 128K–256K.

    Why it matters: The original text provides actual memory, speed, and multiple benchmark comparisons of the edge 145B model, which can be used to judge the practical boundaries of running cutting-edge models locally.

  2. The Verge · AI82

    Google releases Gemini 4 Hydrogen, capable of breaking down complex problems into multiple parts

    Google has released the Gemini 4 Hydrogen model, claiming it can better answer complex questions that involve multiple parts, spelling errors, or highly specific requirements, and will break down the problem and respond item by item.

    Why it matters: The original text listed the default position and available entries of Gemini 4 Hydrogen in search and Gemini applications, allowing readers to judge its impact on the existing search and Q&A process.

  3. Google DeepMind87

    Google DeepMind releases Gemini 4 Hydrogen model

    Google DeepMind releases Gemini 4 Hydrogen, targeting daily coding and intelligent agent workflows, with an Artificial Analysis intelligence index of 51 at the default high thinking level, higher than Argon's 50, and reaching 54 at the xhigh level

    Why it matters: Google provides the division of labor and positioning of Hydrogen, Carbon, and Argon, as well as the actual differences in cost and speed between multi-model arrangements.

  1. The Decoder78

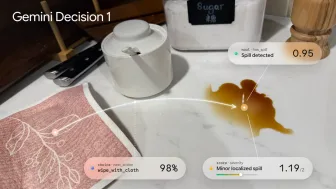
    Google launches Gemini Decision 1 and Gemini Decisions API, capable of processing 1000 issues at a time

    Google DeepMind launches Gemini Decisions API, targeting yes/no, multiple choice, and scale scoring for closed-form judgments. The underlying model, Gemini Decision 1, can handle up to 1000 independent questions at once, covering text, images, audio, video, and PDF.

    Why it matters: Gemini Decision 1 makes closed-loop judgment an independent API and provides latency, price, and benchmark performance for comparison with recent similar decision models.

  1. Claude · YouTube68

    Claude Mythos 5.2 predicted the complete AAV coat structure

    Claude Mythos 5.2 predicts the complete AAV capsid structure, which is composed of 60 identical protein chains. It writes code for an open-source folding model to handle the overlap grouping of adjacent five chains, then uses the symmetry of the capsid to assemble the 60 chains. On AAV2, its prediction deviates from the experimental structure by about the width of an atom.

    Why it matters: The original text provides specific methods and accuracy of the model in real scientific research tasks, allowing readers to judge its applicable boundary in structural prediction work.

  2. Claude · YouTube75

    Anthropic released Claude Fable 5.2

    Anthropic releases Claude Fable 5.2, designed for the most challenging technical challenges, with improvements in coding, reasoning, and vision, suitable for the most ambitious open-ended technical work. The official recommendation is to use Opus 5.5 for most coding and knowledge tasks, and Fable 5.2 is now available in the Pro, Max, Team, and Enterprise packages.

    Why it matters: The official statement explains the positioning and applicable scenarios of Fable 5.2, and provides a choice suggestion between Opus 5.5, making it easier to decide which model to use.

  1. Artificial Analysis Articles72

    Thinking Machines released Inkling 2 Small, Artificial Analysis Intelligence Index score 31

    Thinking Machines released Inkling 2 Small, scored 31 on the Artificial Analysis Intelligence Index v5.0.1, 18 points higher than Inkling Small, and the same as Gemini 3.8 Flash (high).

    Why it matters: Third-party reviews provide a point-by-point comparison of Inkling 2 Small with Gemini, Claude, and other models in terms of intelligence index, coding, and hallucination rate, which can be used to determine its positioning.

  2. ITHome · AI78

    Ant Group's Baidu Ling-3.2-flash releases a native multimodal model, with three benchmarks surpassing Claude Opus 5

    Ant Media official team releases native multimodal model Ling-3.2-flash, with a total of 560B parameters, 25B activation parameters, and 1M context window, supporting image, text, and video input.

    Why it matters: The original provides three benchmark comparisons and API pricing, allowing readers to judge the capability position and call cost of this multimodal model.

  1. ITHome · AI74

    Qwenputer Launched: Embedding the RISC-V CPU instruction set into the model, AI arithmetic no longer relies on external tools

    Developer Divyansh Agrawal released the experimental model Qwenputer on October 22, built based on Alibaba's Qwen3.5-4B, which implements 32-bit RISC-V CPU and memory functions inside the neural network, allowing program execution and precise calculations without calling external tools like Python.

    Why it matters: Developers compiled the RISC-V instruction set into the Qwen3.5-4B weights, demonstrating with specific benchmark numbers the improvement in computational precision within the model and the trade-offs in volume and speed.

  1. Hugging Face Blog85

    Mistral Large 4 (Le Chonk) released on Hugging Face

    Mistral releases multimodal MoE model Mistral Large 4 (Le Chonk), with approximately 1T total parameters, 49B activation parameters, a context window of 1M tokens, offering two official versions FP8 and NVFP4, as well as GGUF made by Unsloth and llama.cpp teams.

    Why it matters: The original text provides specific scores for the 1T total parameter, 49B activation multimodal MoE model on cybersecurity and coding benchmarks, along with measured throughput for local and endpoint deployment.

  2. Google DeepMind87

    Google DeepMind releases the Gemini 4 Carbon cutting-edge model

    Google DeepMind has opened Gemini 4 Carbon to developers, enterprises, scientists, and consumers, claiming it has reached cutting-edge levels in network security capabilities and long-range intelligent agent workflows.

    Why it matters: The official provides the positioning division of roles between Carbon and Argon, multiple benchmark rankings, and cost comparisons per task to help determine when to use a heavier model.

  1. MarkTechPost71

    Baidu open-sources Unlimited OCR 2, supporting the parsing of hundreds of pages of documents.

    Baidu open-sources Unlimited OCR 2, a 3.34B parameter OCR visual language model that can parse hundreds of pages of books, financial reports, and reports in a single request. The weights are released under the MIT license, and the code is on GitHub.

    Why it matters: The original text provides a comparison of SR-SWA's sparse attention mechanism with the hundred-page document benchmark, showing how the contextual cost of long document OCR can be flattened.

  2. ITHome · AI86

    OpenAI releases low-cost new model GPT-6.1 Terra, with a cost per task about one-ninth of Claude Opus 5.5

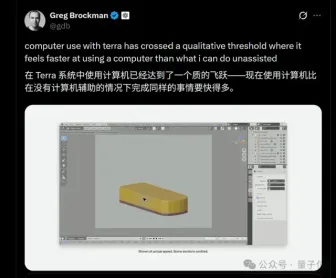
    OpenAI releases new model GPT-6.1 Terra, featuring lower costs for complex tasks requiring visual reasoning and desktop software operation, opening to Plus, Pro, Enterprise, and Edu users on October 27, available in ChatGPT Work and Codex, with the API model identifier as gpt-6.1-terra.

    Why it matters: The original text provides multiple benchmarks and cost per task comparisons, allowing readers to judge the trade-offs of low-cost models in desktop automation.

  3. Artificial Analysis Articles85

    OpenAI released GPT-6.1 Terra, focusing on cost efficiency.

    OpenAI released GPT-6.1 Terra, the first Terra-level model after GPT-5.6, with input/output pricing at $1/5 per million tokens, lower than the $2/12 per million tokens of GPT-5.6 Terra.

    Why it matters: The original text used the scores of the Intelligence Index and Coding Agent Index, along with the cost per task, to quantify the change in cost-effectiveness of GPT-6.1 Terra compared to GPT-5.6 Terra.

  1. QbitAI78

    Rockchip Matrix, in collaboration with CUHK and CMU, has open-sourced EdgeRock-4B, reducing KV Cache by 99.1%.

    Rockchip Technology's Rockchip Matrix, in collaboration with CUHK and CMU, has released and open-sourced EdgeRock-4B, with a fixed KV Cache of 72MiB under 256K context, reducing the source model Qwen3.5-4B by 99.1%.

    Why it matters: The original provides a comparison of throughput under fixed memory, which can be used to judge the trend of GPU memory costs for long-context reasoning.

  1. Simon Willison82

    Kimi K3.1 Pro goes live with Kimi API, promising to open source weights by November 4th.

    Kimi K3.1 Pro goes live with Kimi API today, weights not yet open, Moonshot promises to release complete model weights by November 4th, 2026. Pricing is $2.00/100 million tokens for input, $10/100 million tokens for output, the same as GPT-6.1 Sol, half of Claude Opus 5.5, also provides a Highspeed version that is 2-3 times faster and doubles the price.