Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet
Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet
Google has released the Gemini 4 Carbon model, showing better reasoning performance than Fable 5.2 in the Artificial Analysis test, complementing rather than replacing Gemini 4 Argon, which is more suitable for most software engineering tasks.
Same story11 other outlets also reported this
- Artificial Analysis Articles··First
Gemini 4 Carbon topped the Artificial Analysis Intelligence Index v5
- Google DeepMind··+17 h 1 min
Google DeepMind releases the Gemini 4 Carbon cutting-edge model
- MarkTechPost··+17 h 49 min
Google DeepMind released Gemini 4 Carbon, emphasizing network security defense and coding.
- Ars Technica · AI··+18 h 47 min
Google has released Gemini 4 Carbon: a cutting-edge AI model that cannot be used immediately.
Adds:Ars Technica mentions the model has a 2x higher probability of generating bug-free code and a 10x higher ability to generate high-quality patches compared to non-Google models.
- The Decoder··+19 h 18 min
Google DeepMind releases Gemini 4 Carbon, just two weeks after Argon.
Adds:The Decoder notes the model topped the Artificial Analysis Intelligence Index v5.0 with 59 points, while the previous Argon scored 50 points.
- The Verge · AI··+20 h 3 min
Google releases Gemini 4 Carbon, achieving a 'major leap' in cybersecurity capabilities
- ITHome · AI··+20 h 52 min
Google has released Gemini 4 Carbon, focusing on cybersecurity and topping the Artificial Analysis Intelligence Index.
- 36Kr · AI··+23 h 52 min
- QbitAI··+24 h 4 min
Google released Gemini 4 Carbon, surpassing Claude Opus 5.5 in multiple benchmarks.
- Platformer··+2 d
What are the common points between the bad days of Google and Reddit?
- O'Reilly Radar··+10 d
- The Verge · AI··+14 d
Google has publicly released Gemini 4 Carbon and previewed the swarm agent feature.
- Google DeepMind··+14 d
Google DeepMind releases the Gemini 4 Carbon cutting-edge model
- n8n Blog··+14 d
Google Gemini 4 Carbon is released in n8n, enhancing the security, reliability, and efficiency of agents and workflows
- The Decoder··+14 d·Reading now
Google releases the Gemini 4 Carbon model
- ITHome · AI··+14 d
Google's strongest model yet, Gemini 4 Carbon, debuts: Focused on complex programming, scientific research, and cybersecurity
In order of publication · later reports are added as they appear · Compared by AI from each outlet’s title and summary
About two weeks ago, it looked as though Google would once again take the lead in AI models when it unveiled Gemini 4 Carbon. But the advertising and cloud giant took a bit too long to release it.
Now, Carbon is already starting to feel a little less fresh. Anthropic just unveiled its new top model, Fable 5.2, which outperforms the new Gemini model in the Artificial Analysis test even at lower reasoning intensity. The model cycle is spinning particularly fast right now. Still, it's good to see that Carbon is now generally available after a two-week testing phase for selected security experts.
Google says Carbon complements the previously released Gemini 4 Argon rather than replacing it. Argon is still the better choice for most software engineering and knowledge work tasks, according to Google, while Carbon is built for tasks that push the limits of model intelligence. That's a bit surprising, since both models have the same token price, but Carbon scores higher on benchmarks.
Google lists complex multi-step coding and debugging along with open-ended scientific research among Carbon's strengths. But the model uses more tokens than Argon to reason more deeply on complex debugging or open-ended research and to run longer verification loops. So in practice, the total bill is likely higher compared to Argon despite the same token price.
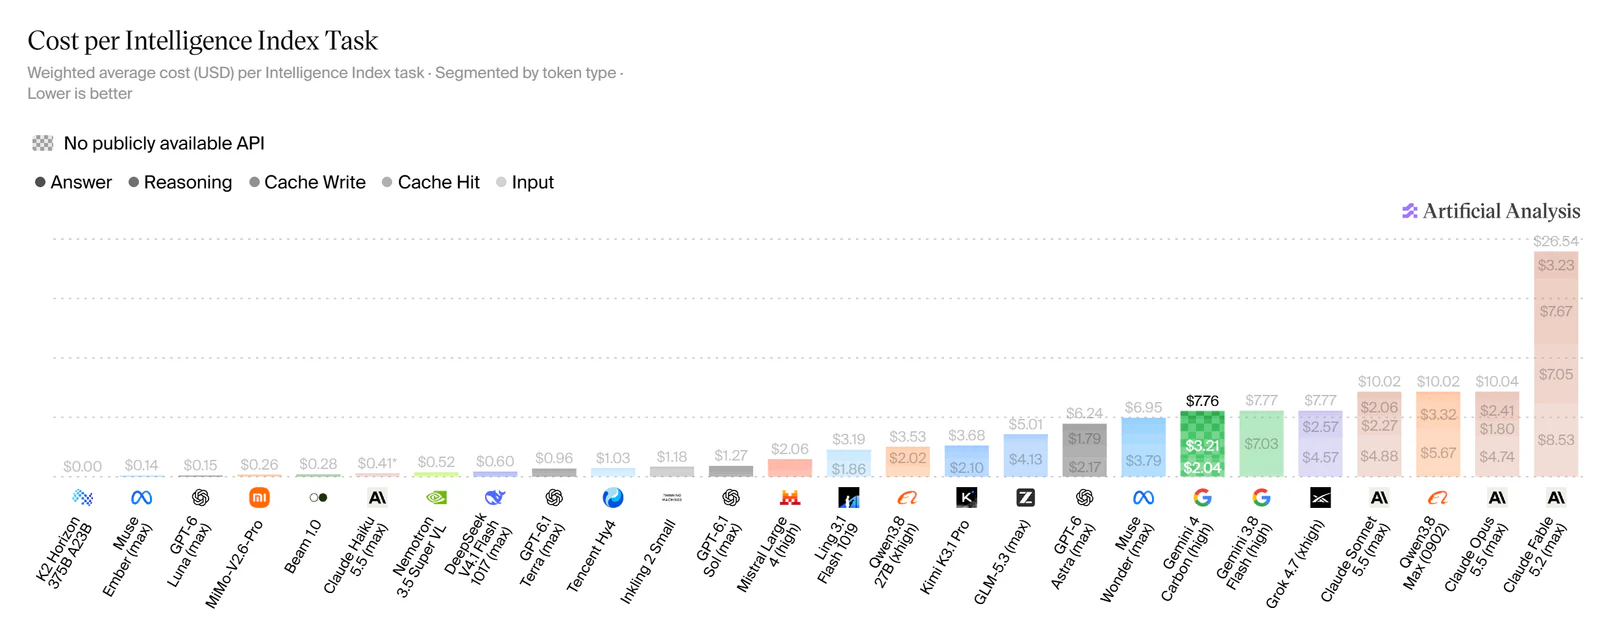
In the Artificial Analysis test published two weeks ago, Carbon cost $7.76 per solved task, already calculated at the regular standard price of four dollars per million input tokens and 20 dollars per million output tokens. That makes Carbon cheaper than the older budget model Flash 3.8 while delivering better performance, which is no small feat. A Flash variant of Gemini 4 is likely to launch soon.
In the same test, Opus 5.5 Max comes in at $10.04, GPT-6 Astra Max at $6.25. Fable 5.2 at its maximum tier costs as much as $26.50. At the High tier, Fable 5.2 costs "only" about $9 per task but still sits two points ahead of Carbon in the overall index (62 vs. 60).
Developers and business customers on paid tiers can access the model through the Gemini API in Google AI Studio, in Android Studio, or through Gemini for Business. The introductory price stays at two dollars per million input tokens and ten dollars per million output tokens.
Google introduces agent swarms that turn a single prompt into a coordinated AI agent team
Alongside the model launch, Google is previewing the "/swarm" feature in Google Antigravity, Google's counterpart to Claude Code. The new feature turns a single prompt into a coordinated team of agents whose work can be tracked in real time. Carbon takes on roles that need deep reasoning, such as architecture design, coordination, and auditing, while faster, lighter models run in parallel isolated workspaces and as adversarial verifiers.
Google demonstrates the feature with a 3D game where users explore the Google campus in Mountain View as a pelican on a GBike, an interactive 3D reconstruction of the Eiffel Tower's construction based on historical photos, and a playable 18th-century fortepiano with seat-specific spatial acoustics.
The cost-benefit ratio of agent swarms like these is being debated across the industry. OpenAI and Anthropic have recently sounded cautious, and researchers are skeptical too. The main benefit seems to be greater speed through parallelization, but that's complex.
Carbon keeps up with the new Fable 5.2 on some benchmarks but costs far less
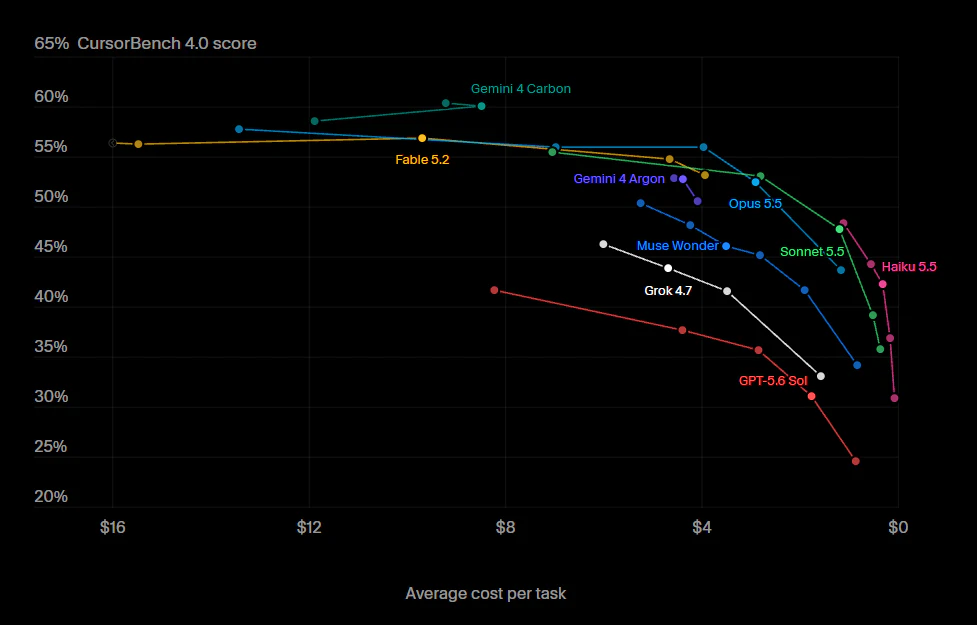
In addition to the performance data already known from late October, Google cites new benchmark results. Carbon takes first place on the coding benchmark CursorBench 4.0, ahead of Fable 5.2, on Perplexity's WANDR, and on Zapier's AutomationBench, at less than half the per-task cost of the next-best model, Fable 5.2.
For analyzing dense documents with charts, blueprints, and tables, Google partnered with Artificial Analysis to launch the new Multimodal Knowledge Agent (MKA) benchmark. Carbon finishes second here, just behind Fable 5.2 and just ahead of Opus 5.5, but costs less than one-sixth of what the top performer does on average.
Gemini 4 Carbon finds real zero-day vulnerabilities in under two hours
From the two-week early-access testing phase through the Fairwind Program, Google is sharing concrete real-world results for cyberdefense for the first time. As part of security firm Wiz's Scan for Good program, Carbon found real zero-day vulnerabilities while scanning two large SaaS providers in under two hours. Google's own cloud security team also used the model to write working proof-of-concept exploits for two known bugs in a popular open-source project.
Only then could the bugs be proven critically exploitable, comparable to the PHP2Shell vulnerability. In Google's autonomous security system Project Fortify, Carbon boosted the detection rate on open-source codebases by more than 25 percent over Argon.
Google highlights cybersecurity capabilities as a particularly strong feature of Carbon. The model leads on the benchmarks SEC-bench Pro (finding vulnerabilities), ExploitGym (exploiting vulnerabilities), and CWE-bench v1 (patching vulnerabilities), according to Google, but that applies only to the version available through the Fairwind Program. Google doesn't share specific numbers.
Google's Carbon is the first AI model to hit a zero percent success rate on a prompt injection test
Google has also published a full safety report and the model card. On an internal honesty test with 375 tasks, Carbon passes 92 percent of tests (Argon: 70 percent) and refuses to fabricate missing experimental data in 98 percent of cases.
In simulated cyberattacks, the model blocked 99 percent of attack paths from adaptive red-teaming agents and cut the breakthrough rate per attempt from 3.1 percent with Argon to 0.8 percent. External testers from Trajectory Labs didn't find a single universal jailbreak in 132 hours and over 13,000 queries.
On the Gray Swan IPI benchmark, Carbon achieved a prompt injection success rate of zero percent, Google says, meaning it wasn't cracked even once. Google says this is the first time any model has reached that milestone. That doesn't mean prompt injections are solved; the test may just be saturated. It's still progress, especially since some competitors are still more vulnerable here.
AI News Without the Hype – Curated by Humans
Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section.
Source: The Decoder · the-decoder.com