Skip to content
Live
  1. Hacker News · 300+78

    llama-modchip enables the 284B DeepSeek-V4-Flash to run on a 64GB memory without GPU

    llama-modchip releases a set of ggml/llama.cpp core patches and quantization transcoding tools, compressing the 284.33B DeepSeek-V4-Flash to 56.56 GiB (1.71 bpw), which can run on a pure CPU machine with 64 GB memory, with a peak memory of 57.61 GiB under 256K context and no need for swap.

    Why it matters: The project provides a quantization scheme and core patches for running 284B MoE on 64 GB memory, along with measured data for each hardware, which can be used to determine the feasible boundary for pure CPU deployment.

  1. vLLM Blog60

    vLLM serves DeepSeek-V4.1-Flash on GB300 NVL72: performance matches DeepInfer and extends to the entire rack

    The vLLM team used P/D separation and Wide-EP to serve DeepSeek-V4.1-Flash on a single NVIDIA GB300 NVL72 rack, achieving 954K tokens/s per GPU and 196 tokens/s for single-user P90 on SemiAnalysis AgentX, which is 7.9 times the early single-node results.

    Why it matters: The vLLM team has released per-item optimization and measured data for serving DeepSeek-V4.1-Flash on GB300 NVL72, which can be compared with DeepSeek's own engine DeepInfer.

  1. vLLM Blog62

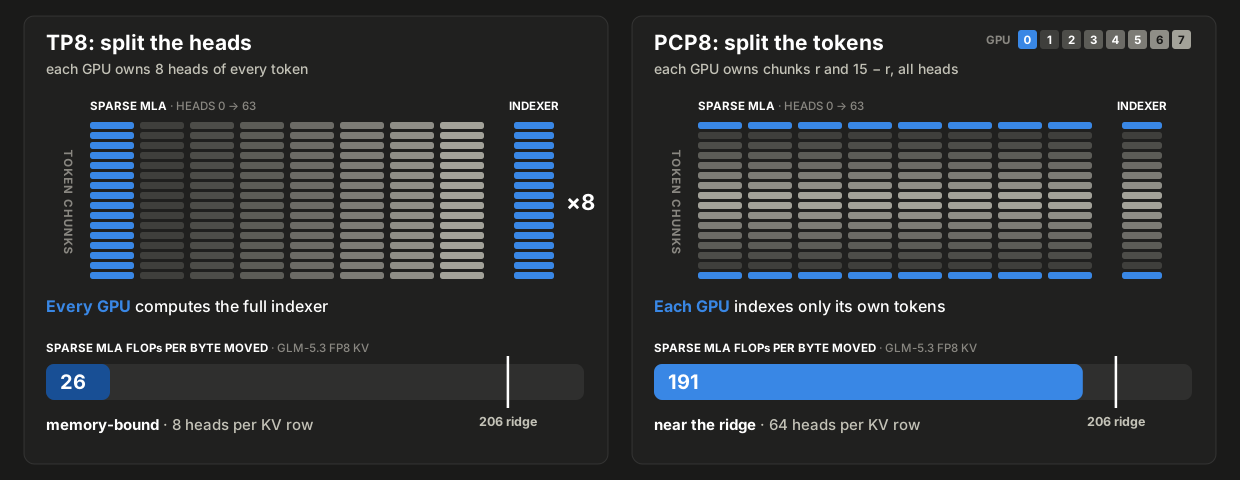
    vLLM provides an in-depth explanation of the optimization of PCP, DCP, and Hybrid HiSparse for GLM-5.3 on 16 H200s

    vLLM team releases the second part of GLM-5.3 optimization, deploying on 16 H200s with 1 pre-filled node and 1 decoding node, using PCP to split pre-fill by token and DCP to split KV cache by token, allowing 1M context to fit into the pre-fill node

    Why it matters: The vLLM team has dissected how PCP, DCP, and Hybrid HiSparse can be combined on 16 H200s, allowing readers to understand the memory and pre-fetch bottlenecks of long-context deployment.

You are all caught up