Google DeepMindFeatured7676
Google DeepMind releases Gemini Robotics 2.5 vision-language-action model
Google DeepMind released Gemini Robotics 2.5, claiming it is the most capable vision-language-action (VLA) model to date, with a 30% to 100% increase in success rate on 200 tasks compared to previous baselines, and 20% to 30% faster task completion speed.
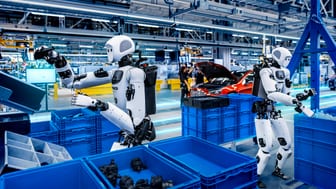
Why it matters: Officially disclosed were 200 task evaluations and actual production line test data showing a 96% success rate for Mercedes-Benz, which can be used to judge the extent of VLA model deployment in real industrial scenarios.